

AI & Machine Intelligence
How machine reasoning is measured, where it beats people, where it still fails, and what any of it says about human intelligence.

METR Time Horizon Explained: The Latest Numbers and Why It Is Not an IQ
METR's time horizon is the task length, set by how long a skilled human takes, that an AI agent completes about half the time. The top figure in its data file is 17.4 hours (95% CI 8.5 to 55.1), which METR itself calls unreliable above 16 hours, and it is not an IQ.

Is the Tower of Hanoi an IQ Test? What It Measures in People and in AI
No norm table turns Tower of Hanoi moves into an IQ. In people the puzzle overlaps with inhibition, working memory and fluid reasoning; in AI it became the centrepiece of Apple's 2025 "collapse" paper, a published reply, and a revision. We read all three.

AI Scores on the Mensa Norway Test: What 151 Means and What It Does Not
A late-September report said an AI reached the theoretical maximum of 151. TrackingAI's own score log, read on 7 October 2026, shows that 151 is a ceiling set by a formula, that 11 perfect sittings exist in 1,906, and that the top entry's 151 rested on one sitting.

Humanity's Last Exam Scores: What the Leaderboards Show
Three public boards give three different top scores on Humanity's Last Exam: 54.8%, 59.9% and 61.4%. Each uses a different question set, judge or tool setting. We read all three, the Nature paper and the audits of the answer key, and ask whether any of it is an IQ.

GPQA Diamond Score: What It Measures and How Far AI Has Come
GPQA Diamond is 198 multiple-choice science questions. Its top score on 6 October 2026 was 96.3%, up from 38.8% for GPT-4 in 2023. The "65% for experts" figure everyone quotes is not the Diamond number, and 198 questions leave little room to rank models.
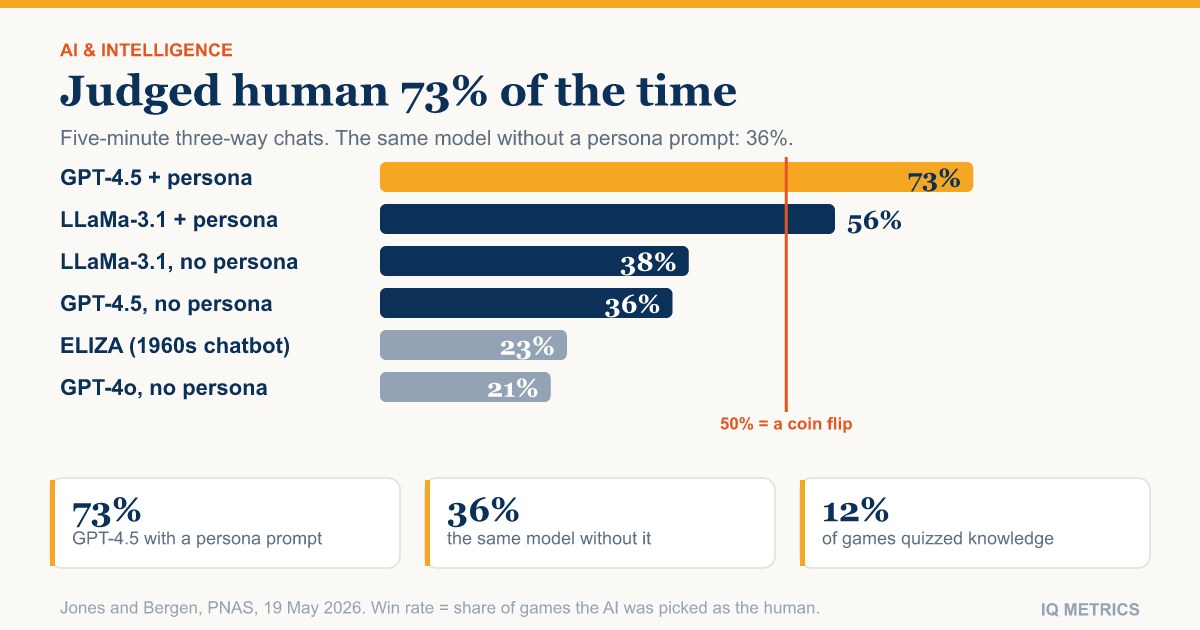
Has AI Passed the Turing Test? What the 2026 PNAS Study Found
A peer-reviewed PNAS paper says GPT-4.5, given a humanlike persona, was picked as the human in 73% of five-minute chats. Without the persona it managed 36%, and the authors say the test measures humanlikeness, not intelligence.

IQ Checkers for X Accounts: What They Actually Estimate
Sites and bots that promise an instant IQ score for any X (formerly Twitter) username read public profile data, not cognitive ability. Here is exactly what the number is built from.

Plausible Nonsense: Only 4 of 60 AI Models Cleared a Reasoning Benchmark
A PNAS paper published on 9 September 2026 tested 60 large language models against human deliberation. Only four consistently cleared its benchmark, while the rest could still sound reasonable. Here is what the abstract does and does not establish.

What the Artificial Analysis Intelligence Index Measures, and Why Scores Move
Headlines call it an AI intelligence score. It is a weighted average of ten evaluations, and it was rebuilt five times between August and September 2026: Claude Fable 5.1 scored 66 on 1 September and 53 under v4.3. Claude Opus 5.5 now leads at 58.

Is There a g Factor for AI Models? What the Benchmark Correlations Show
Language models that do well on one benchmark tend to do well on the others, and published psychometric analyses have extracted a dominant common factor from those scores. Whether that factor is anything like human g depends on a question about what is varying between the models.
Two Scores, One Model: How the Harness Decides an ARC-AGI-3 Result
GPT-6 Astra scored 62.7 per cent and 99.9 per cent on the same benchmark in the same week. The difference is not the model. It is how the test was administered.
AI-Generated IQ Test Questions: What Changes for a Score
Machines have been writing reasoning items since long before the current wave of language models, and the research is clear about where the difficulty lies. Generating a plausible question is the easy half. Knowing how hard it is remains the expensive half.
Can AI Pass an IQ Test? On ARC-AGI-3, Humans Score 100% and AI 0.51%
Frontier systems now clear reasoning benchmarks that defeated them a year ago. Put them in front of puzzles screened so that ordinary people solve every one, and the best models finish under one per cent.
AI and Memory: What Cognitive Offloading Research Shows So Far
The sturdiest results are narrow and decades old. The 2025 studies that drew the headlines rest on self-reports and small preprints — and none of them measured intelligence at all.
When a Model "Scores 120", That Number Is Not an IQ
IQ scales are defined by a human reference sample, and a language model is not in it. Placing a machine on that scale is not a hard measurement problem — it is a category error.
Written to be checked, not just clicked
Every number carries its scale
An IQ figure is meaningless without the scale it was measured on and the range around it. Every story here reports all three, or says plainly that the source did not.
Sources are listed, not implied
Each story ends with the studies, datasets and documents it draws on, named and attributed, so you can go and read them yourself.
We correct in public
Spotted an error? Write to corrections@iqmetrics.org. Corrections are made on the story and noted at the bottom of it — never quietly.
Read the research.
Then find your own number.
Our IIF-certified assessment reports your score with its scale, percentile and confidence range — and a breakdown of the cognitive domains behind it.
Start IQ Test →