IQ Metrics
IIF Certified Assessment Start IQ Test
IIF Certified Assessment

Gardner’s Multiple Intelligences

Research & Evidence

Multiple Intelligences: Why the Theory Never Entered Testing

Gardner’s multiple intelligences theory is one of the most influential ideas in education and almost entirely absent from the tests psychologists use. That gap is not stubbornness. It comes down to one stubborn statistical finding, one missing instrument, and a real insight the theory carries.
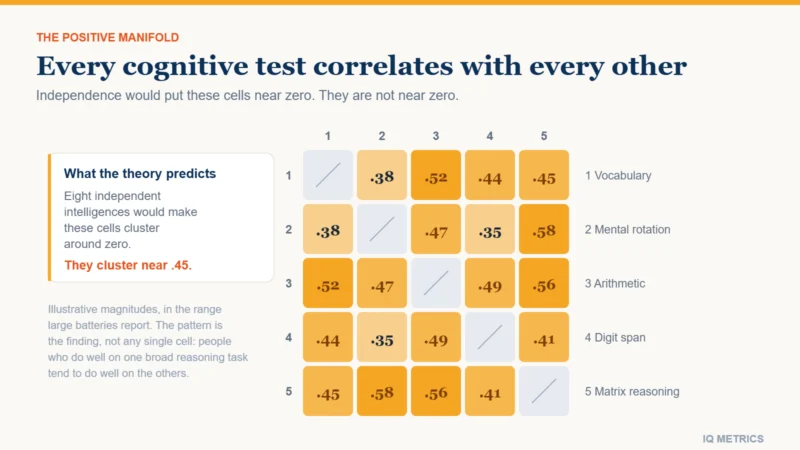
Diagram of the positive manifold: a correlation grid showing that verbal, spatial, numerical and memory tests all correlate positively with one another, which is the finding multiple intelligences theory predicts should not appear

Multiple intelligences theory occupies an unusual position: it is one of the best-known ideas in education and one of the least used in psychometrics. Howard Gardner proposed it in Frames of Mind in 1983, it reshaped how a generation of teachers talked about ability, and forty years later no standard cognitive battery measures the eight intelligences. That is not professional stubbornness. There are three specific reasons, and one of them is a finding the theory has to explain and has not.

What Gardner actually proposed

The claim was not that people have different strengths — nobody disputes that. It was that human intelligence is not one capacity but several biologically distinct and largely independent ones, each with its own developmental path and neural substrate. The original seven became eight, with a ninth debated.

  • Linguistic — language, rhetoric, writing
  • Logical-mathematical — abstraction, proof, quantity
  • Spatial — mental rotation, navigation, visual design
  • Musical — pitch, rhythm, timbre
  • Bodily-kinaesthetic — skilled movement, physical craft
  • Interpersonal — reading and influencing other people
  • Intrapersonal — accurate self-knowledge
  • Naturalistic — recognising and classifying living things

Gardner did not pick these arbitrarily. He set out eight criteria a candidate had to satisfy, including isolation by brain damage, the existence of prodigies and savants in the domain, an identifiable core set of operations, a distinct developmental history and evolutionary plausibility. Two of the eight criteria were psychometric. Those two are where the trouble starts.

The criteria themselves are a genuine methodological contribution, and they are more demanding than most popular summaries suggest. The neuropsychological criterion in particular does real work: amusia, prosopagnosia and specific language impairment are established dissociations, and they are the strongest evidence Gardner has. The difficulty is that a candidate could satisfy six criteria comfortably while failing both psychometric ones, and the theory offers no rule for what to do when that happens. In practice, admission has been decided by argument rather than by a threshold, which is why the count has moved from seven to eight with a ninth perpetually under discussion.

The positive manifold, and why it is the whole argument

Take any broad set of cognitive tests — vocabulary, mental rotation, arithmetic, digit span, pattern completion — and give them to a large unselected sample. Almost without exception every test correlates positively with every other. People who do well on one tend to do well on the rest. This is the positive manifold, first described by Spearman in 1904, and it is one of the most replicated results in psychology. It is what our note on the g factor describes, and what the hierarchical models behind how modern IQ tests work are built to represent.

Multiple intelligences theory predicts something different. If the intelligences are genuinely independent, then measures of them should be substantially uncorrelated. When researchers have constructed ability-based measures of Gardner’s domains, the correlations keep turning up — and the domains that submit most readily to objective measurement, linguistic, logical-mathematical and spatial, are precisely the ones that load most heavily on the general factor the theory sets out to replace.

The magnitudes matter here. Correlations between broad cognitive domains in large samples typically sit somewhere between 0.3 and 0.7, and a general factor commonly accounts for something in the region of 40 to 50 per cent of the variance in a broad battery. Independence would predict something close to zero. What the data show is neither one intelligence nor eight separate ones, but distinguishable abilities that travel together.

This is not a knockout blow. Gardner’s reply has been that the correlations reflect the narrow, schooled tasks psychometricians choose, and that the domains furthest from the classroom have never been measured properly. That is a coherent objection. It has just not yet produced the data that would settle it.

The measurement gap

Which is the second problem. Gardner has consistently declined to build a battery, on the stated grounds that reducing the intelligences to test scores would repeat the error he was diagnosing. That is a defensible philosophical position with a severe practical cost: a theory that resists operationalisation cannot easily be confirmed either.

The instruments that circulate under the multiple intelligences banner are almost all self-report inventories — a person rates how musical or interpersonal they feel. Self-rated ability correlates only modestly with measured ability across most domains. These questionnaires capture self-concept, which is a real and interesting variable, and not the thing the theory is about. The contrast with the clinical batteries psychologists use, each with published reliability figures and standardisation samples, is stark.

It is worth stating what would settle the argument, because it is not out of reach. Build performance tasks for each of the eight domains — judged musical production, tested spatial navigation, scored social inference, measured motor learning. Administer all of them to one large sample. Factor the results. If eight roughly independent factors appear, the theory is vindicated against the strongest objection to it. If a general factor absorbs most of the shared variance again, it is not. Nobody has run that study at scale, and until somebody does, the disagreement stays where it has been since 1983.

Diagram of the positive manifold: a correlation grid showing that verbal, spatial, numerical and memory tests all correlate positively with one another, which is the finding multiple intelligences theory predicts should not appear
Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

What the theory gets right

None of the above makes the idea worthless, and the dismissive version of this argument is as sloppy as the credulous one.

Gardner was right that standard batteries sample a narrow slice of human competence. A test that predicts school achievement well is not thereby a measure of everything valuable about a mind. Musical skill, athletic judgment, social perception and craft ability are genuine, developable and largely unmeasured — and the fact that they may correlate with g does not mean they reduce to it. He was also right that the label attached to a child changes what is expected of that child, which is a real cost of testing set out in the case for and against IQ testing.

There is a second thing it gets right, less often credited. A general factor is a statistical abstraction extracted from a correlation matrix, not an organ or a substance. It is easy to slide from “a general factor explains much of the shared variance” to “there is a single quantity of intelligence that people possess in amounts”, and the second claim does not follow from the first. Gardner pushed hard against that slide, and he was right to.

That insight has an established home in the literature. It is the subject of whether intelligence is limited to IQ, it drives the research on IQ and creativity, and it is why the site treats a score as one input rather than a verdict.

Multiple intelligences, EQ and the triarchic theory

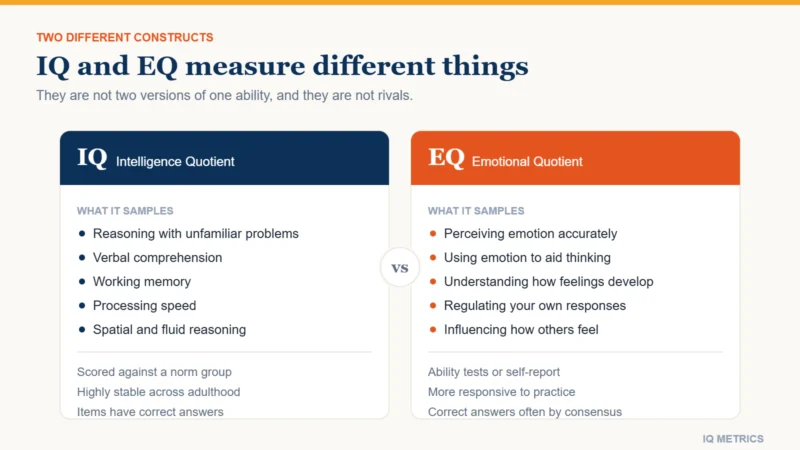
Gardner’s is not the only rival. Sternberg’s triarchic theory proposed analytical, creative and practical intelligence, and made more effort to measure its constructs; its practical intelligence component remains contested on whether it adds predictive power beyond g. Emotional intelligence covers similar ground to Gardner’s interpersonal and intrapersonal domains, with the same recurring split between ability-based tests and self-report questionnaires that the comparison of IQ and EQ sets out.

What psychometrics adopted instead was the Cattell-Horn-Carroll model, which resolves the tension a third way: many distinct broad abilities, arranged in a hierarchy, with a general factor above them. It gets the plurality Gardner wanted and keeps the correlations the data insist on.

Why it conquered classrooms anyway

The theory spread for reasons largely independent of its evidential status. It arrived when single-number labelling of children was under sustained criticism. It is egalitarian in a way a single ranking cannot be: every child is intelligent in some way. And it is easy to convert into activities.

That last quality is also how it went wrong. Multiple intelligences is routinely conflated with learning styles — the idea that a kinaesthetic learner should be taught kinaesthetically — and Gardner has publicly and repeatedly rejected the conflation. His intelligences are content domains, not delivery channels. The meshing claim is one of the brain myths that failed when tested directly.

How to use the idea honestly

  • Treat it as a corrective, not a measurement system. It is a good argument about what tests leave out and a poor basis for profiling anyone.
  • Distrust any multiple intelligences profile you were given. If it came from a questionnaire about preferences, it measured preferences.
  • Keep the two claims separate. That people have uneven strengths is certain; that those strengths are independent intelligences is the contested part.

If you want a number that is defined, normed and reported with its error band rather than a profile of eight, that is what a properly constructed IQ test is for — and knowing exactly what it does not cover is the most useful thing Gardner leaves you with.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged Cattell Horn Carroll, emotional intelligence, G Factor, Howard Gardner, intelligence test, IQ, IQ Score, Learning Styles, mental ability, mental capabilities, multiple intelligences, Positive Manifold, theories of intelligence, Triarchic Theory

Brain Myths About Intelligence

Understanding IQ

Left Brain, Right Brain, and Five Other Myths About Intelligence

You are not left-brained or right-brained, you do not use ten per cent of your brain, and matching a lesson to your learning style does not help you learn. Six claims about intelligence that almost everyone repeats, what the studies that tested them found, and the smaller true fact hiding inside each one.
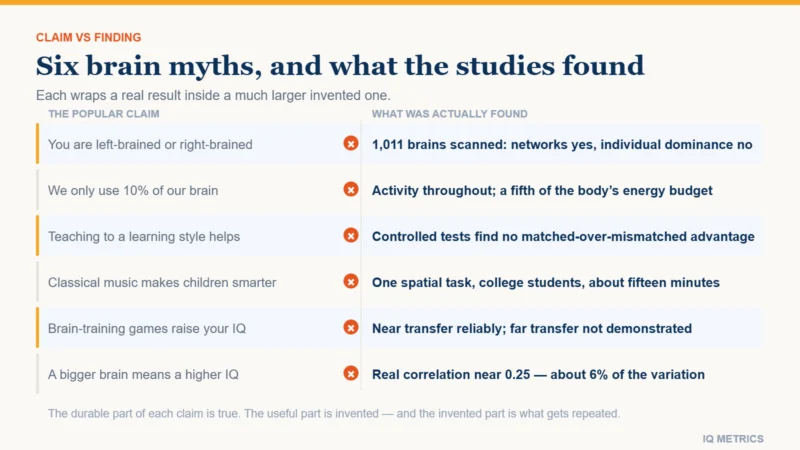
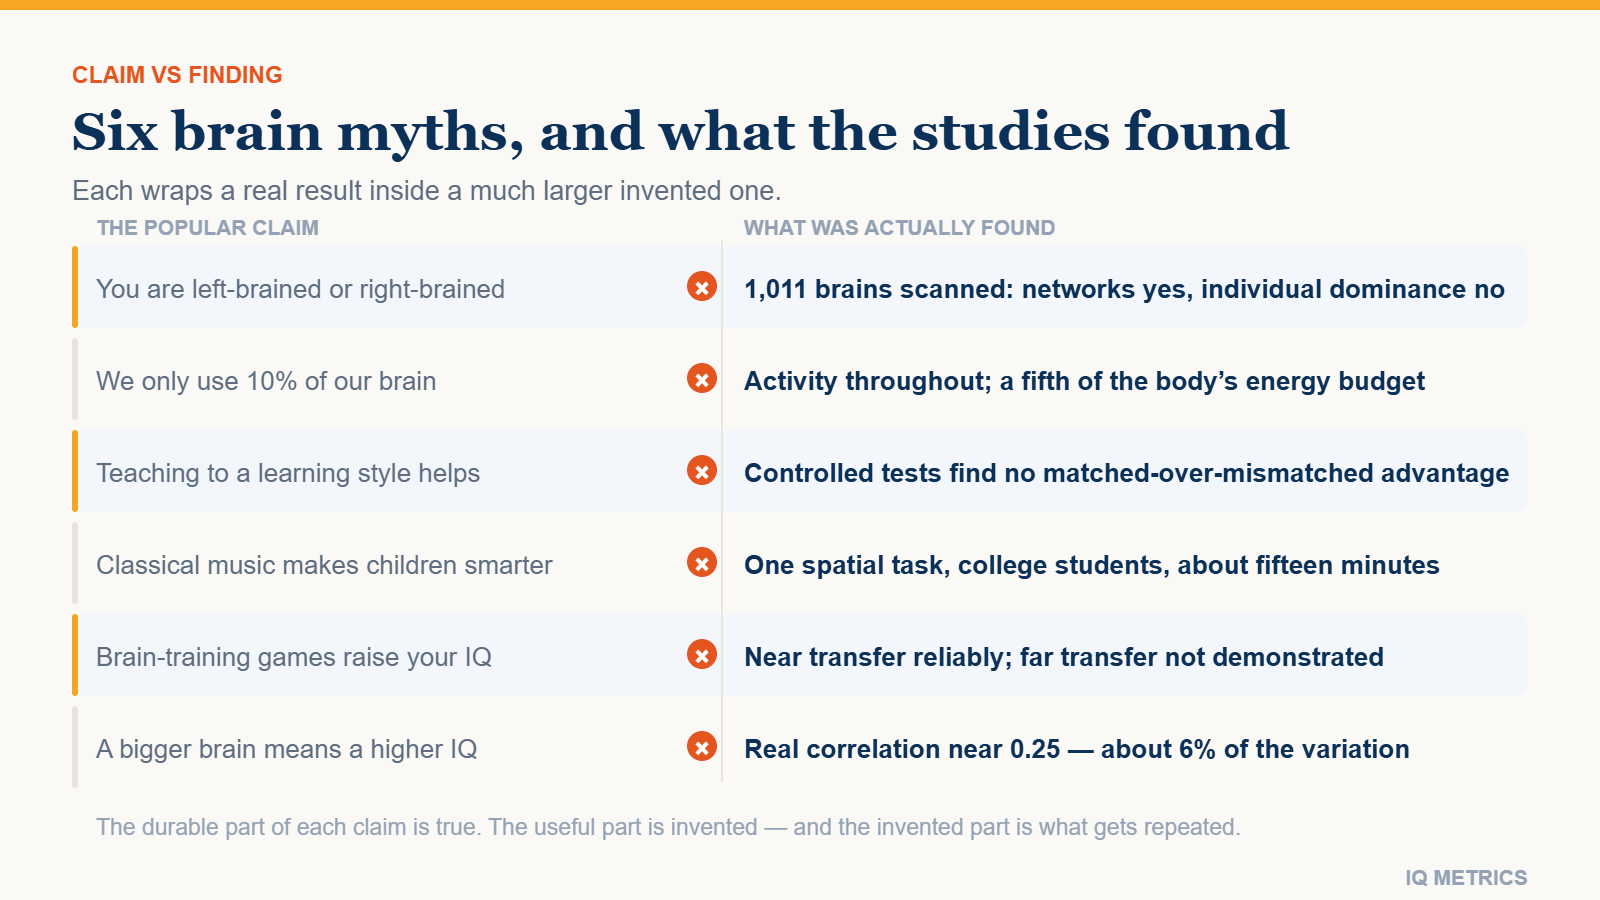
Chart contrasting six popular brain claims with what research found, showing the residual grain of truth in each: lateralisation without dominance, whole-brain activity, no meshing effect, no far transfer and a small brain size correlation

Most brain myths about intelligence survive because each one wraps a real finding in a much larger false one. Hemispheres really do specialise — but nobody is left-brained. Brain size really does correlate with test scores — but far too weakly to tell you anything about a person. The durable part is true, the useful part is invented, and the invented part is what gets repeated.

Here are six of them, the study that tested each, and the smaller true fact left standing afterwards.

Myth 1: you are left-brained or right-brained

The claim is that people have a dominant hemisphere, and that dominance produces a personality: left-brained people are logical and analytical, right-brained people creative and intuitive.

It was tested directly. A 2013 University of Utah analysis of resting-state scans from over a thousand brains looked for exactly this — individuals whose left-lateralised networks were globally stronger than their right, or the reverse. The lateralised networks were there. The individual dominance was not. People did not sort into two types.

The idea has a respectable ancestor, which is why it is so hard to dislodge. Roger Sperry and Michael Gazzaniga’s split-brain work in the 1960s studied patients whose corpus callosum had been severed to control epilepsy, and demonstrated that the disconnected hemispheres really could process information separately. That is a Nobel-recognised finding about surgically divided brains. The leap from there to intact brains having a dominant half, and from a dominant half to a personality, was made by popular writing in the 1970s and never by the research.

What is true: lateralisation is real and well-mapped. Language production is left-lateralised in the large majority of right-handed people; aspects of spatial attention and prosody lean right. What does not follow is a personality type, and certainly not a study technique. Every complex task, including every item on an IQ test, recruits both sides. Our page on which part of the brain IQ tests measure covers the distributed frontal and parietal network that actually does the work.

Myth 2: we only use 10 per cent of our brain

This one has no identifiable source study, which is itself telling. It has been attributed to William James, to Einstein and to a misreading of early glial-cell counts, and none of the attributions holds up.

It fails on three independent grounds. Functional imaging finds activity throughout the brain over the course of a day, not in a tenth of it. The brain consumes roughly a fifth of the body’s energy at about two per cent of body weight — metabolically implausible for tissue that is ninety per cent idle. And damage to almost any region produces a deficit, which would not be the case if most of the organ were spare capacity.

What is true: not all neurons fire at once, which would be a seizure. Efficiency, not idleness, is the finding — and there is some evidence that higher-scoring brains show less activation on easy tasks, not more.

Myth 3: teaching to a learning style improves learning

The claim: people are visual, auditory or kinaesthetic learners, and matching instruction to the style raises achievement.

This is the myth with the cleanest test, because the claim makes a specific prediction — an interaction. Assess learners, split them, teach half in their preferred style and half in another, then test everyone. The matched groups should win. A 2008 review commissioned by Psychological Science in the Public Interest found that studies using this design were rare, and that the few well-controlled ones did not produce the interaction. Later replications have agreed.

Belief in it remains close to universal. Surveys of teachers across several countries have repeatedly found nine in ten endorsing the idea, and it persists in training materials long after the reviews. The reason it feels true is that it makes a correct prediction about something else: students who are taught in a way they enjoy report enjoying it more, and engagement genuinely helps. The style-matching part adds nothing on top of that.

What is true: people do have preferences, and material has a best modality — you learn geography from a map and pronunciation from audio, whoever you are. Preference is real; the benefit of matching is what fails. This one matters more than it looks, because it is the mechanism by which multiple intelligences theory is most often misapplied in classrooms.

Myth 4: classical music makes children smarter

The 1993 study behind the “Mozart effect” reported a small, temporary improvement on one spatial task in college students, lasting about fifteen minutes. It did not test children, did not measure IQ and did not claim a lasting effect. Everything else was added by the coverage. Later work traced the small effect to arousal and mood: anything enjoyable produces it, including an audiobook, if you like audiobooks. Our fact-check on whether music raises IQ has the full history.

What is true: sustained musical training is a different proposition with a genuinely more interesting literature, though causal claims there remain contested too.

Chart contrasting six popular brain claims with what research found, showing the residual grain of truth in each: lateralisation without dominance, whole-brain activity, no meshing effect, no far transfer and a small brain size correlation
Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

Myth 5: brain-training games raise your IQ

People who practise a brain-training task get better at that task. They also improve on tasks that closely resemble it. What large randomised trials have struggled to demonstrate is far transfer — improvement on unrelated reasoning that was never trained. Meta-analyses of working-memory training find reliable near transfer and little to no far transfer.

The largest single test of the claim recruited more than eleven thousand participants through a television-linked online trial and trained them on reasoning, memory and attention tasks over six weeks. Trained tasks improved. Untrained cognitive tasks did not improve more in the training groups than in the control group. Subsequent trials have complicated the picture in places, particularly for older adults and for specific working-memory paradigms, but no result has established the broad transfer the products advertise.

What is true: scores do move, and the honest account of why is unglamorous. Familiarity with format, reduced anxiety and better strategy are real gains that show up as points without a change in underlying ability. That distinction is the whole subject of whether you can improve your IQ, and it is why a second sitting of the same test is not independent evidence.

Myth 6: a bigger brain means a higher IQ

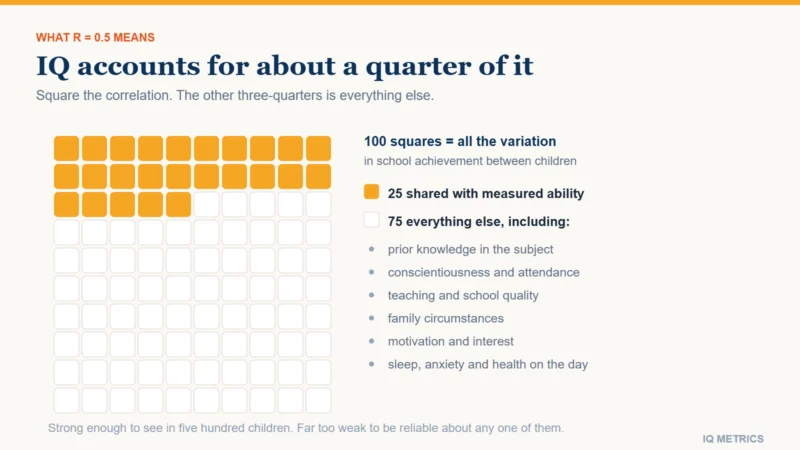
Unlike the others, this one starts from a real correlation. Meta-analyses of in-vivo imaging put the relationship between total brain volume and IQ score at roughly 0.24 to 0.30 in adults. It is a genuine, replicated finding.

It is also nearly useless about an individual. A correlation of 0.25 accounts for around six per cent of the variance, which means brain volume tells you almost nothing about any particular person’s score. Organisation, connectivity and cortical thickness carry more signal than gross volume, and between-species and between-sex comparisons break the pattern entirely.

The historical record here is a warning rather than a curiosity. Nineteenth-century craniometry measured skulls with real instruments and real arithmetic, and produced conclusions that tracked the prejudices of the measurers rather than the tissue. The methods were not the problem; the willingness to read a small, noisy correlation as a verdict about groups was. That failure mode has not gone away, which is part of why the history of intelligence testing is worth knowing before quoting any number about brains.

Why these particular myths survive

Three features keep them alive, and recognising the pattern is more useful than memorising the list.

  • Each contains a true kernel, so a correction that denies the whole claim sounds wrong to anyone who knows the kernel.
  • Each offers an identity or a shortcut. Being a right-brained visual learner explains something about you and asks nothing of you.
  • Each is unfalsifiable in daily life. Nothing that happens this week will disconfirm the ten per cent claim.

Checking a brain claim in ninety seconds

You do not need a neuroscience background to filter most of this. Four questions catch the large majority of bad claims.

  • Does it describe a type of person? Brains vary continuously. Claims that sort people into two or four kinds are almost always folk taxonomy wearing a lab coat.
  • What was the outcome measure? “Improved brain function” is not one. A named task with a published score is.
  • Was there a control group doing something equally engaging? Most training and music effects vanish against an active control rather than a do-nothing one.
  • How large is the effect, in the units you care about? A real but tiny correlation is the commonest way a true finding becomes a false headline.

The same three features explain why the popular picture of intelligence drifts so far from the measured one — and why the gap between IQ and emotional intelligence as marketed and as measured is so wide. If you want to see what a test actually samples rather than what folklore says it does, the IQ tests hub sets out each reasoning domain and what it is built to capture.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged Brain Myths, Brain Size and IQ, brain training, intelligence test, IQ, IQ Score, iq testing, Learning Styles, Left Brain Right Brain, mental ability, Mozart Effect, Neuromyths, power of mind, Practice Effect, Working Memory

Cultural Bias in IQ Tests

Research & Evidence

Are IQ Tests Culturally Biased? What the Evidence Shows

Ask whether IQ tests are culturally biased and you get two confident, opposite answers. Both are partly right, because the word means something far narrower to a psychometrician than it does in ordinary use. Here is what the item-level evidence shows, and where culture really does get into a score.

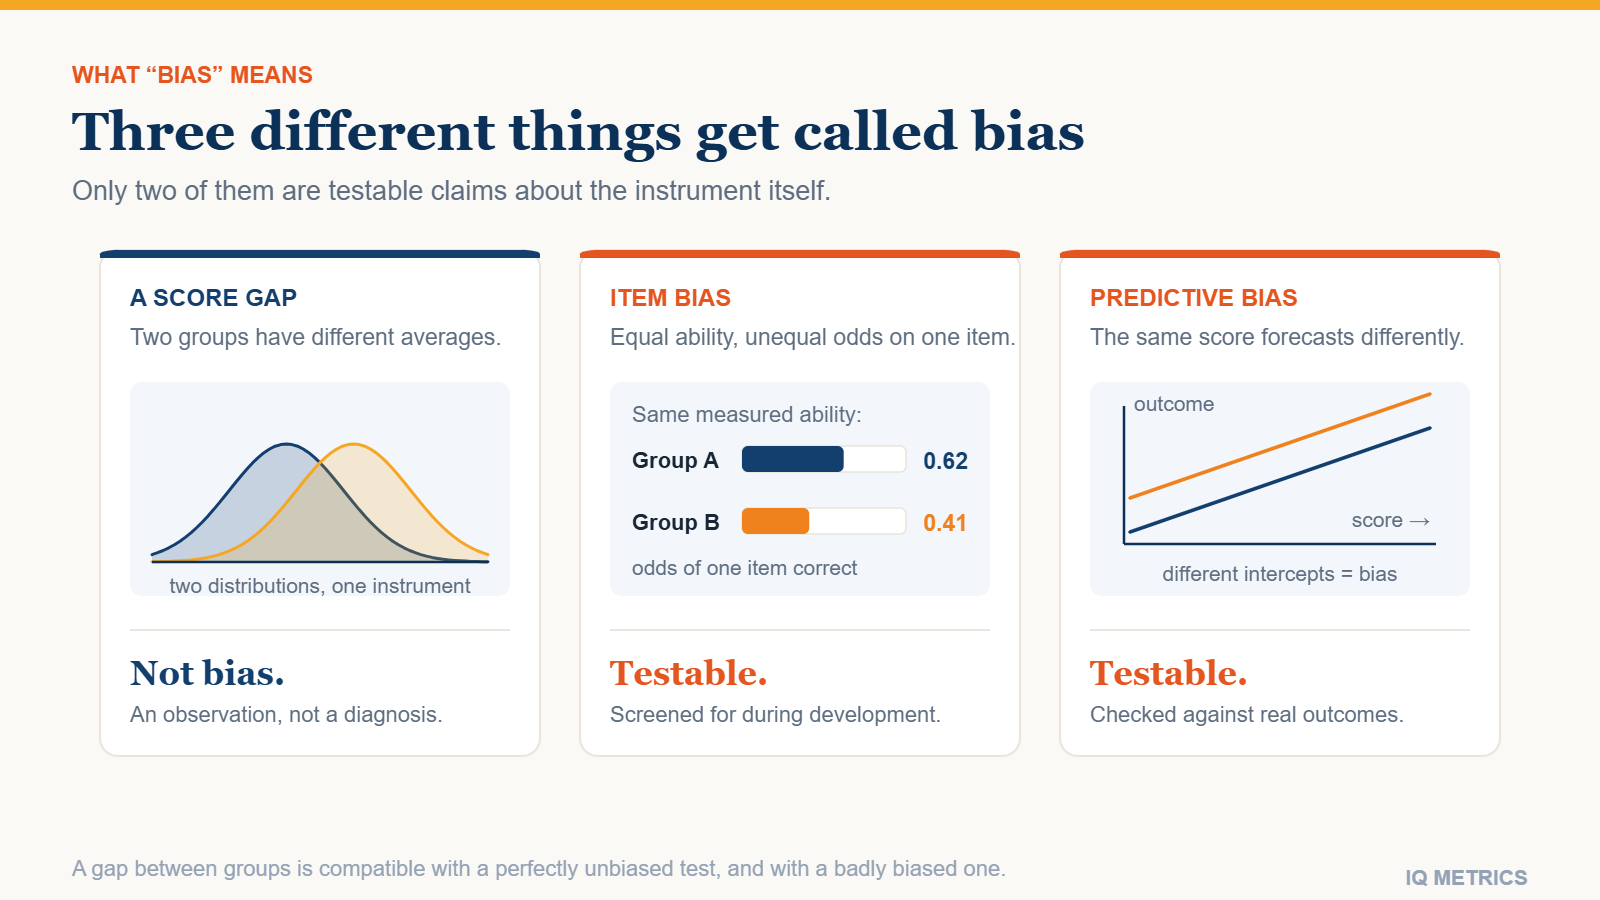
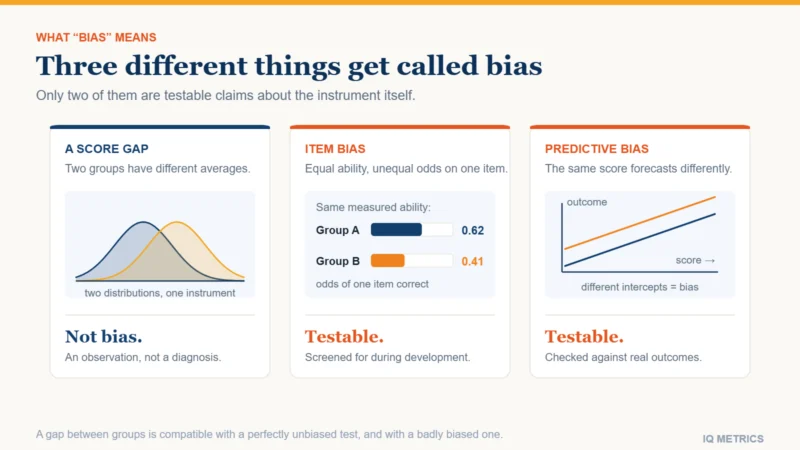
Diagram separating three things often confused under the word bias: a score gap between groups, item bias where equally able test-takers answer differently, and predictive bias where a score forecasts an outcome differently by group

Cultural bias in IQ tests is real, but it is narrower and stranger than the phrase suggests. When psychometricians test for bias in modern batteries they usually find little of it in the technical sense they mean — and that finding does almost nothing to settle the question most people are actually asking. The confusion is not carelessness on either side. The word bias has a narrow statistical meaning in test development and a broad, moral one in ordinary use, and the two answers to “are IQ tests culturally biased” are answers to two different questions.

This article separates them. First what bias means to the people who build the tests, then what their own studies find, then the four places culture genuinely does get into a score — most of which are not in the questions at all.

Three different things get called bias

Almost every argument about this topic is two people using one word for three separate claims.

  • A score gap. Two groups have different average scores. This is an observation, not an explanation. A thermometer is not biased because two cities differ.
  • Measurement bias. Two people of genuinely equal ability have different chances of getting an item right, because of something about the item other than the ability it is meant to tap. This is testable, and it is what test developers screen for.
  • Predictive bias. The same score forecasts a real-world outcome — a grade, a job rating — differently depending on which group the test-taker belongs to. Also testable, using regression slopes and intercepts.

Only the last two are bias in the technical sense. A gap on its own is compatible with a perfectly unbiased instrument, and equally compatible with a badly biased one. That is why the existence of group differences settles nothing on its own, and why national IQ rankings cannot support the conclusions drawn from them regardless of which direction the numbers point.

The regatta question, and why it was removed

The most-cited example of a culturally loaded item is real. An SAT analogy question asked test-takers to complete runner is to marathon as oarsman is to ___, with regatta as the answer. The word belongs to a leisure activity distributed very unevenly across social classes, and the item behaved exactly as you would predict. It was dropped, and analogy items were eventually dropped from the SAT altogether.

This is worth dwelling on for a reason people usually skip: the item was identified and removed by the statistical screening process. It is evidence that the screening works, not that it does not. But it also shows where the danger sits. Vocabulary and general-knowledge subtests are the most culturally loaded parts of any battery, and they are loaded by design, because they measure acquired knowledge rather than novel reasoning. That is the distinction between crystallized and fluid ability covered in our guide to how IQ tests work, and it is exactly why a verbal reasoning section cannot be culture-free even in principle.

What the item-level studies actually find

Major batteries such as the Wechsler scales and the Stanford-Binet run differential item functioning analyses during development. An item is flagged when test-takers matched on overall ability still differ in their odds of answering it correctly, and flagged items are revised or cut before publication. Expert review panels screen content separately.

The published result is consistent and, to many people, counter-intuitive: within a single country and language, residual differential item functioning in well-constructed batteries tends to be small, and measurement invariance broadly holds across major demographic groups. Reviews of predictive bias reach a similar place — where tests are validated against school or job outcomes, they generally do not under-predict performance for lower-scoring groups.

Two honest caveats belong with that finding. Invariance within a country is a much weaker claim than invariance across countries and languages, where translation, adaptation and separate norming samples make the comparison far shakier. And invariance means the test measures the same construct in the same way for everyone; it says nothing about whether the construct itself was shaped by unequal opportunity long before test day.

Diagram separating three things often confused under the word bias: a score gap between groups, item bias where equally able test-takers answer differently, and predictive bias where a score forecasts an outcome differently by group
Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

Where culture actually gets into a score

If the items are largely clean, the interesting question is what is left. Four things, none of them a question on the page.

The culture of test-taking itself

Sitting alone with a stranger, working fast, guessing when unsure rather than staying silent, treating an obviously artificial puzzle as worth serious effort — these are learned conventions, and they are learned unevenly. Someone taught that admitting ignorance is more honest than guessing will lose real points on a scored-right test. Familiarity with the format is itself worth points, which is the same mechanism behind the practice effect on repeated testing.

The language of administration

A bilingual test-taker assessed in their second language is being measured partly on that language. This is the single largest and least controversial source of cultural distortion in practice, and it is why a large verbal-nonverbal split is a flag for a clinician rather than a finding — see what a gap between your verbal and non-verbal scores means.

Stereotype threat

The proposal is that awareness of a negative stereotype about your group consumes working memory during the test itself. The original laboratory demonstrations were striking. The picture since has become genuinely contested: several large replications have found much smaller effects than the early studies, and meta-analyses report evidence consistent with publication bias. The fair summary is that the mechanism is plausible and probably real in some settings, and that its size in a routine testing session is unresolved. Ordinary test anxiety, which is better established, points the same way.

The norm group your score is compared against

An IQ score is not a count of correct answers. It is a position relative to a standardisation sample, so who was in that sample is part of the measurement. A score from a sample that under-represents you is a comparison you did not consent to. This is also why the same raw performance yields different numbers on scales with different spreads, as our percentile calculator and the note on standard deviation 15 versus 16 both show.

Content bias versus construct bias

There is one more distinction worth having, because it is where the two sides of this argument genuinely disagree rather than merely talk past each other.

Content bias is an item behaving unfairly. It is what the screening catches, and modern batteries are reasonably good at it. Construct bias is a deeper claim: that the ability being measured is itself a culturally particular thing — that valuing speed over deliberation, abstraction over context, and the lone solver over the group is a set of choices about what counts as intelligent, made by a particular tradition.

Cross-cultural work gives this some support. Studies of everyday cognition have documented people performing complex practical reasoning fluently in their own setting — market arithmetic, navigation, agricultural planning — while scoring poorly on the formal-school version of the same operations. Whether that makes the test biased or simply narrow is partly a question about words. What is not in dispute is that it makes a low score, on its own, a weak claim about a person’s reasoning.

Culture-fair tests: what they fix and what they do not

The response to all this, from the 1930s onward, was to strip out language and acquired knowledge. Raven’s Progressive Matrices and the Cattell Culture Fair scales present abstract visual patterns with a rule to be found. Our own culture-fair IQ test is built on the same principle, and these instruments do remove the most obvious problem.

They do not remove culture. Reading a two-dimensional grid as a representation, scanning left-to-right and top-to-bottom, accepting that an abstract puzzle has exactly one defensible answer — all of these are schooled habits. The decisive evidence is the Flynn effect: across the twentieth century the largest score gains were on Raven’s-type tests, the ones designed to be culture-free. Whatever changed in those decades, it was not the human genome. A test that gains twenty points in fifty years is exquisitely sensitive to environment, which is the opposite of culture-free. Our note on why IQ norms expire covers what happened next.

What to do with your own score

None of this makes a score meaningless. It makes it a measurement with conditions attached, which is what every measurement is. Three habits follow.

  • Read the confidence interval, not the point. A single number hides a band of several points either side, as test accuracy and error explains.
  • Ask what the score is being used for. Prediction of school achievement is well evidenced; ranking human worth is not a use the instrument supports, and what a score predicts about school is narrower than most people expect.
  • Treat a low score in an unfamiliar language or format as uninformative until it is repeated under better conditions.

The short answer to the question in the title: modern tests are far less biased at the item level than their critics assume, and far less culture-free than their defenders imply. Both halves of that sentence are load-bearing.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged Cultural Bias, Culture Fair Test, Differential Item Functioning, Flynn Effect, intelligence test, IQ, IQ Score, iq testing, iq tests, Measurement Error, Measurement Invariance, Norm Group, standard deviation iq, Stereotype Threat, Test Bias

Verbal vs Non-Verbal IQ Scores

Scores & Scales

When One Half of Your IQ Score Is 15 Points Higher Than the Other

Two people can hold the same IQ number and have completely different profiles, and a split between the verbal and non-verbal indexes is far commoner than most test-takers expect. Here is what base-rate tables and compounding measurement error say about how large a gap has to be before it means anything.

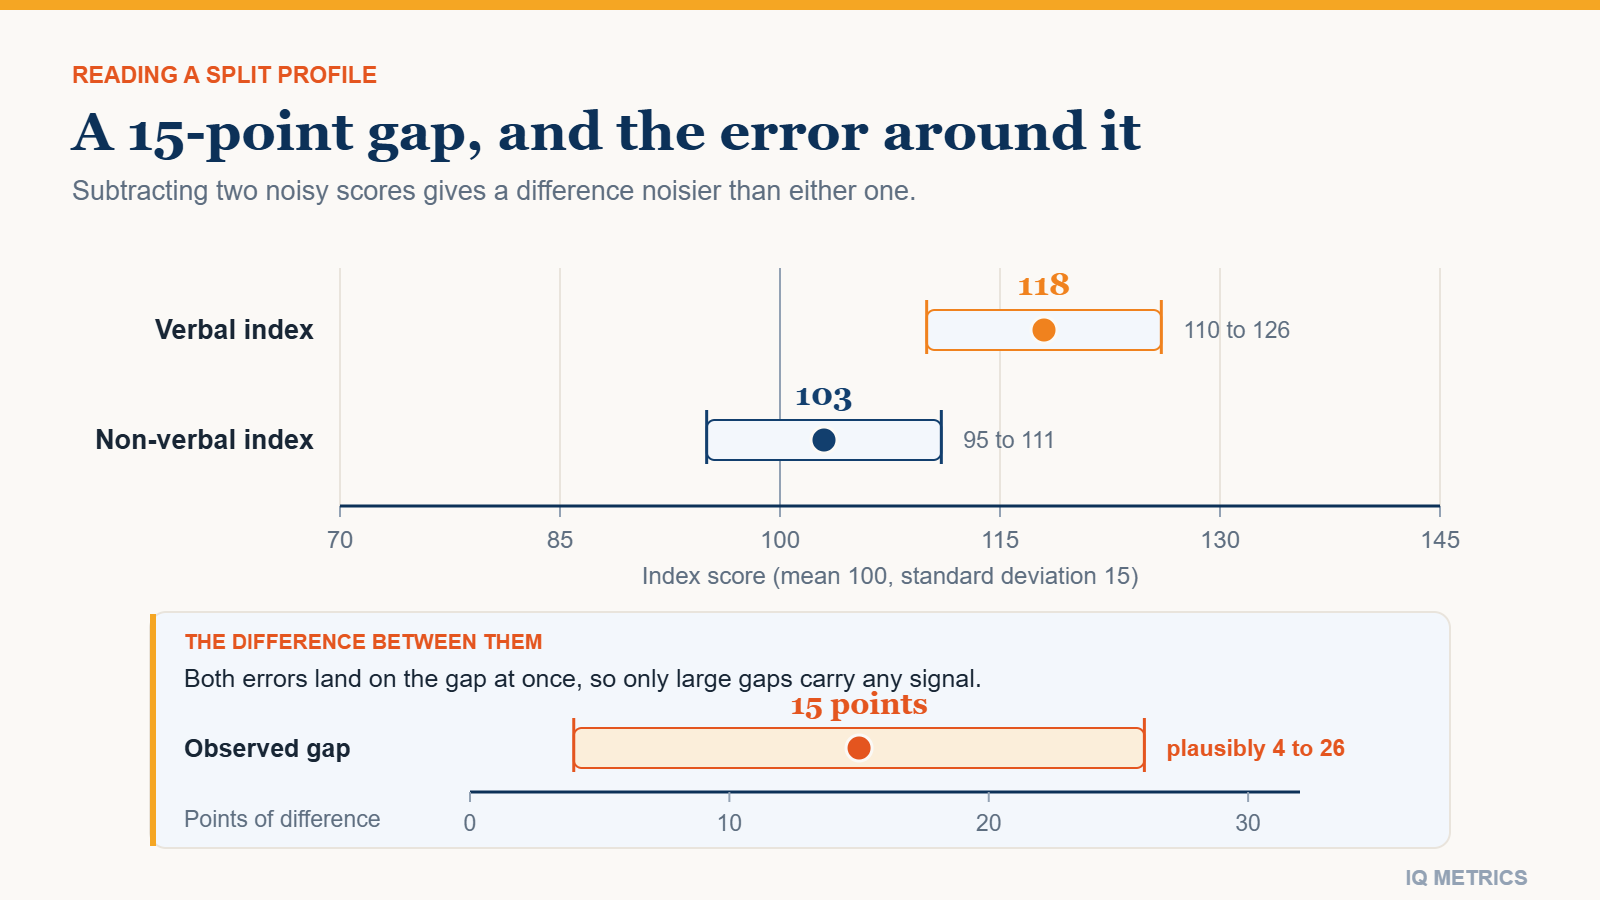
Chart showing a verbal index of 118 and a non-verbal index of 103, each with its measurement error band, and the 15-point gap between them carrying a much wider band of roughly 4 to 26 points

A gap between your verbal and your non-verbal scores is far more common than most people assume. Published base-rate tables from the major batteries show index splits of 10 to 15 points turning up in a substantial minority of the standardisation sample, so a verbal vs non-verbal IQ score difference of that size is usually unremarkable. The useful question is not whether you have a split, but whether yours is big enough to survive the measurement error sitting on both sides of the subtraction.

One number is an average, and averages destroy shape

A full-scale score is a weighted average of several index scores, and averaging is a lossy operation. Two people can arrive at the same 112 by completely different routes: one of them even across every domain, the other with a strong verbal index dragging a weaker visual-spatial one up to the mean. The composite is identical; the profiles are not.

That is why psychologists read the indexes before the total, and sometimes decline to interpret the total at all when the indexes disagree sharply. If the parts of a measure point in different directions, their average summarises something that does not really exist as a single quantity.

The two directions a split can run

Index score discrepancies are not symmetrical in what they suggest. A verbal score sitting above a non-verbal one keeps different company from the reverse pattern, and neither is a diagnosis. Treat the two shapes described here as typical associations, nothing stronger.

Chart showing a verbal index of 118 and a non-verbal index of 103, each with its measurement error band, and the 15-point gap between them carrying a much wider band of roughly 4 to 26 points

Verbal sitting above non-verbal

This shape is common in people with long formal education, heavy reading habits and verbally loaded work: teaching, law, journalism, anything whose day is made of words. Vocabulary and general knowledge keep accumulating with exposure, while timed matrix and pattern tasks do not reward exposure in the same way, so the pattern tends to flatter older test-takers.

That asymmetry between accumulated knowledge and reasoning on the spot has a standard name in the literature, and how IQ tests are built and scored sets it out. The point here is only that a verbal edge is often a record of practice rather than a difference in raw horsepower.

Non-verbal sitting above verbal

The reverse split is common among people testing in a second language, people whose schooling was interrupted or happened in a different system, and younger adults, who have simply had fewer years to accumulate the vocabulary and general knowledge the verbal side rewards. Reading and language difficulties can also hold down verbally loaded scores without that implying a matching limit on reasoning, which is a clinical question rather than a scoring one and is handled in the piece on ADHD, autism, dyslexia and test scores.

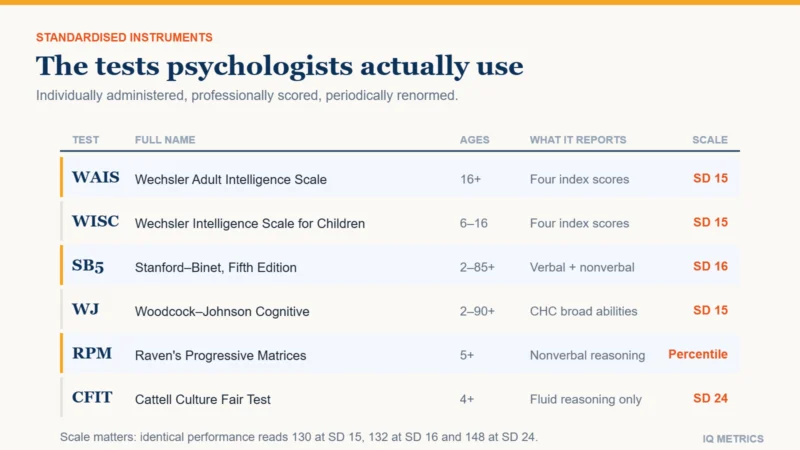
Language load is the obvious confound in this direction, and batteries differ in how much of it they carry; those differences are compared in the guide to professionally administered IQ tests.

How big does a gap have to be before it is signal?

Two things have to hold before a split is worth interpreting. It has to be unusual relative to the population, and it has to be larger than the combined error of the two measurements that produced it. Most of the gaps people worry about fail both tests.

Base rates: lopsided profiles are ordinary

Test manuals publish base-rate tables showing how often each size of index difference occurred in the standardisation sample. The consistent finding is that double-digit splits are common among entirely typical people: published tables put differences of roughly 10 to 15 points in a substantial minority of the sample. The exact percentage depends on the battery and on which pair of indexes you are comparing, so treat any single figure you see quoted as specific to one test rather than universal.

The practical consequence is deflating. A 12-point split is not a finding. Differences of that order turn up often enough in the standardisation samples that seeing one tells you almost nothing about the person holding the score. Gaps only start to look genuinely uncommon well beyond the double-digit range, and where that line sits is decided by the table for that specific index pair on that specific battery, not by any single number that carries across tests.

Why subtracting two noisy numbers widens the error

Every score carries measurement error. A well-built battery with a reliability near 0.90 has a standard error of measurement of roughly 4 to 5 points, which is why a score of 115 is honestly reported as a roughly 95 per cent band of about 106 to 124 rather than as a single point; that arithmetic is worked through in the piece on how accurate IQ tests really are. Index scores rest on fewer items than the full scale, so their bands are if anything a little wider than that.

Now subtract one of those bands from another. Uncertainties do not cancel when you take a difference, they accumulate: the gap between two index scores is a noisier quantity than either index on its own, so its error band is wider than the band on either score you started with. Two errors of 4 to 5 points combine into an error on the difference of roughly 6 to 7 points, which puts a band of something like 12 or 13 points either side of any gap you measure. A difference has to clear a higher bar than a score does before it can be told apart from zero.

Said plainly: if each of two scores can land several points either side of your true standing, a gap of 8 or 10 points between them can be manufactured by nothing more than which day you sat down. Small splits are usually not small effects but no effect at all, which is why a modest gap so often shrinks or flips direction on a retest.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

Subtest scatter is even weaker evidence

Once a split appears, the temptation is to go one level deeper and interpret individual subtests: strong on one, weak on another, therefore a profile. Resist that. Subtests are shorter than indexes, shorter means less reliable, and less reliable means the scatter across them is noisier still.

Decades of research on interpreting individual subtest peaks and troughs have been unkind to the practice. Index-level differences are the smallest unit worth taking seriously, and only when they clear both the base-rate hurdle and the error hurdle. Keep constructs separate too: a weak memory-loaded score is not the same evidence as a weak reasoning score.

What a real discrepancy actually licenses you to conclude

Suppose your split profile clears every hurdle: large, rare in the base-rate table, and still there on a second sitting. What have you learned? A hypothesis about how you learned and where you are practised — not a second IQ, and not a diagnosis.

  • It is descriptive, not causal. A high verbal index says the vocabulary and verbal reasoning are there. It does not say whether they came from schooling, reading, work or something else entirely.
  • It is not a ceiling on the weaker side. Index scores move with familiarity and practice, and retest gains are usually larger on the non-verbal side than on the verbal one.
  • It is not a label. Score patterns are consistent with many explanations and specific to none; a diagnosis needs history, observation and criteria that no test result supplies.
  • It is not a career instruction. The link between profile shape and occupational outcomes is far too loose to guide an individual decision.

The honest use of a split is narrower. It tells you which kind of task you are likely to find comparatively effortful, which is worth knowing when you decide how much preparation an exam or an aptitude screen deserves.

How to read your own rough profile

Breaking the composite apart is the only way to see shape, and a few rules keep the exercise honest.

  • Sit the domains separately: the verbal reasoning test, the spatial reasoning test and the numerical reasoning test, ideally on different days, so that fatigue does not manufacture a gap for you.
  • Convert every result to a percentile first. Different tests are not marked on the same ruler, and percentiles are the closest thing to a common currency.
  • Compare the percentiles, not the raw scores. If your two most extreme domains land within about ten percentile points of each other, treat the profile as flat — flat is the normal answer, and anything wider still has to clear both hurdles above before it means anything.
  • Re-sit your two most extreme domains once. A gap that survives a repeat is worth thinking about; a gap that moves was noise wearing a costume.

One caution about self-administered results: unsupervised tests vary in quality and in how carefully they were normed, so a split measured across two different tests carries all the error above plus the gap between two norming samples. Comparing within one family of tests is safer.

Where to start if your number feels uneven

If you are holding one score and a suspicion that it does not describe you evenly, the cheapest next step is to take it apart rather than to take it again. Sit the domains one at a time, run each result through the IQ percentile calculator, and look at the shape instead of the total.

Most people find their profile is flatter than they expected, and that is the good outcome: a flat profile means the composite you already have is doing its job. A large, repeatable split is rarer, and even then it describes where your practice has gone rather than what you can learn next.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged Index Scores, intelligence test, iq level, iq scale, IQ Score, iq scoring, iq test results, iq test score, Measurement Error, Non-Verbal IQ, Score Discrepancy, standard deviation iq, Subtest Scatter, Verbal IQ

ADHD, Autism and Dyslexia in IQ Testing

Taking a Test

How ADHD, Autism and Dyslexia Change What an IQ Test Measures

A test score is a measurement, and a measurement can be biased by the conditions under which it is taken. ADHD, autism and dyslexia each depress performance on particular kinds of item without lowering the reasoning underneath. Here is what actually interferes, condition by condition, and what to do next.

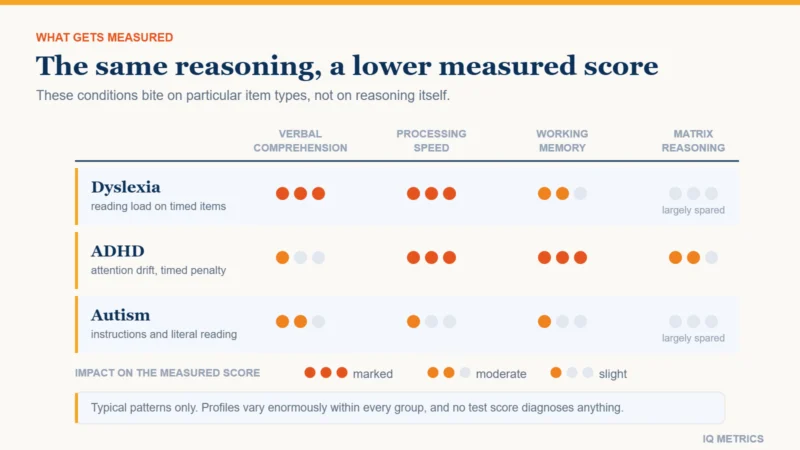
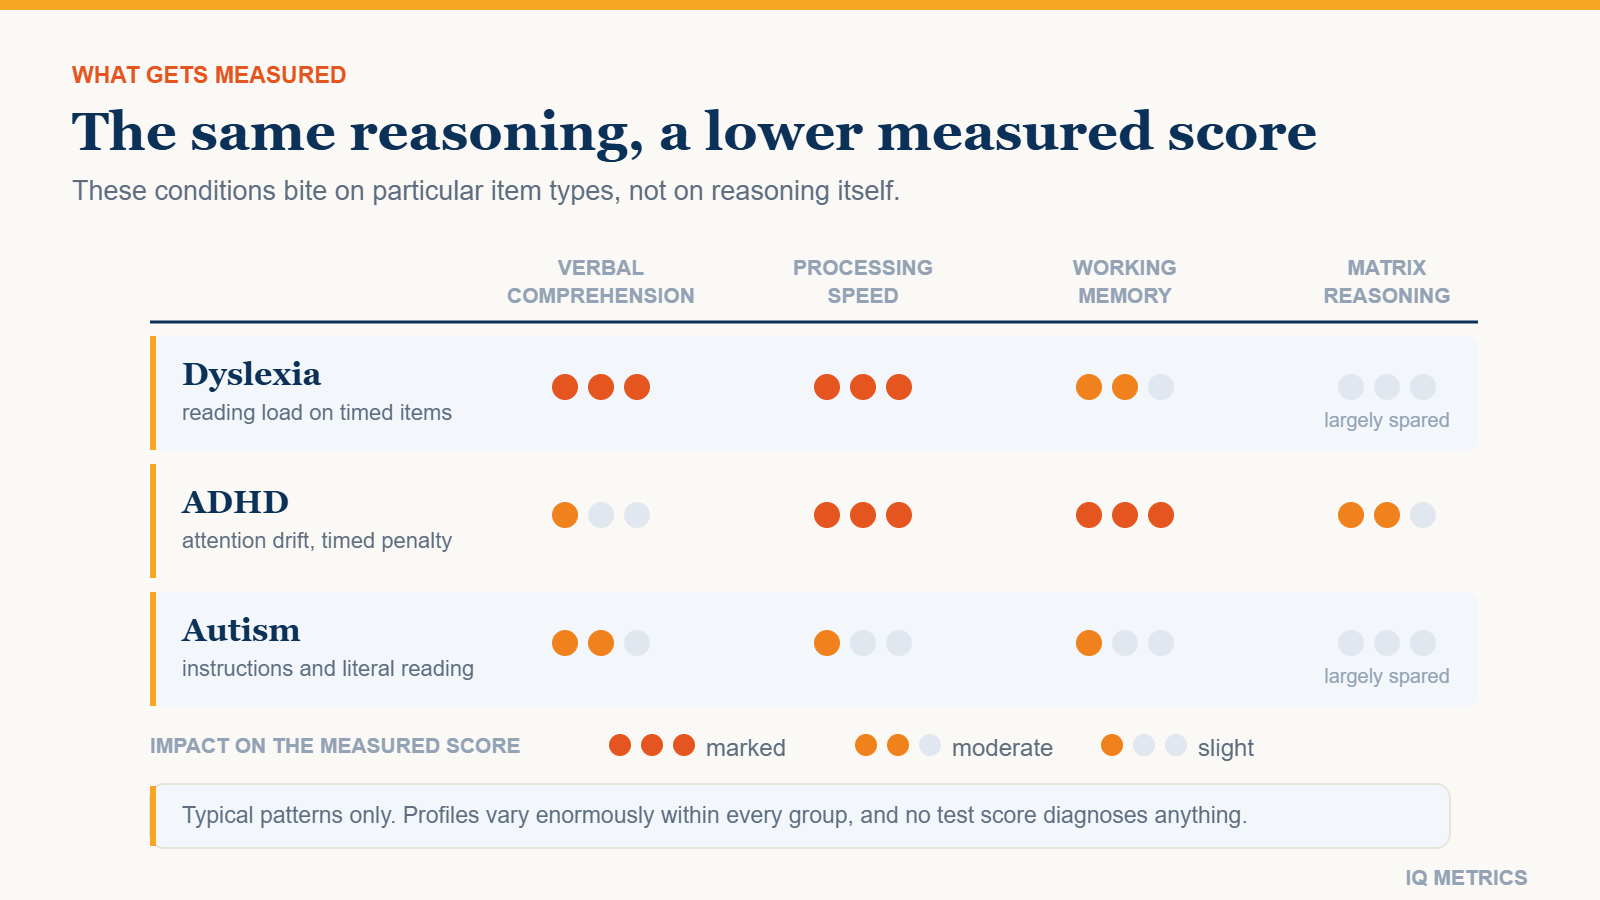
Grid rating how far dyslexia, ADHD and autism affect four IQ test domains: verbal comprehension, processing speed, working memory and matrix reasoning, which is largely spared

If you have ADHD, autism or dyslexia, a score from a timed online test is not meaningless, but for many people it reads lower than their reasoning does. ADHD and IQ test scores interact through the format rather than through intelligence: attention, reading load and the clock all sit between your thinking and the number at the end. What follows names the mechanism for each condition, and what to do about it.

This site publishes tests and explains scores; it has no clinical standing, and nothing here is diagnosis or medical advice. No IQ score, and least of all an unproctored online one, can indicate or rule out ADHD, autism or dyslexia. A qualified assessor is the only route to that answer.

A Depressed Score Is Not a Lower Ability

Much of what is written about neurodevelopmental conditions and testing quietly folds two different claims into one. The first is that measured composites in these groups often come out lower than in comparison samples. For ADHD and dyslexia that is a reasonably consistent finding; for autism it depends heavily on which test was used and how the sample was recruited.

The second claim is that these groups reason less well. That does not follow from the first. A test score is a measurement, and any measurement can be distorted by the conditions under which it is taken. It is more precise to say the score is depressed than that the ability is lower.

A bathroom scale on a thick carpet reads wrong; the reading changed, the weight did not. Much of what these three conditions do to a test result is carpet.

Ordinary test-day variables work the same way; the same person can land several points apart across a fortnight. Our longer piece on the factors that affect IQ test results covers sleep, anxiety, caffeine and practice. The difference is that these three conditions are stable features of how you process information, not the state you turned up in.

Where the Interference Actually Lands

A modern battery is not one thing. It samples several fairly distinct abilities and averages them into a single composite, and interference rarely hits all of them equally. It lands hard on one or two, and the composite carries the damage without saying so.

  • Verbal comprehension – vocabulary, similarities, general knowledge; all of it delivered in written language.
  • Fluid reasoning – matrices and number series, the part closest to raw pattern-finding.
  • Working memory – holding material in mind and manipulating it while you use it.
  • Processing speed – how quickly you get through easy items, not how hard the items are.
Grid rating how far dyslexia, ADHD and autism affect four IQ test domains: verbal comprehension, processing speed, working memory and matrix reasoning, which is largely spared

This is exactly why a profile beats a composite, and why the index-by-index breakdown produced by professionally administered tests is worth far more to a reader in this position than the headline figure.

Dyslexia: The Reading Load Hidden Inside the Test

Dyslexia is a difficulty with accurate or fluent word recognition, decoding and spelling, neurobiological in origin and not explained by a lack of instruction. On a test it lands in two predictable places. Verbal comprehension items have to be read, and so do the instructions and the answer options.

Processing-speed items are trivially easy in content and hard to finish. On a professional battery they use symbols rather than words, and are still often lower in dyslexic profiles because naming things quickly is part of what they measure. On an online test the speeded items are usually words and sentences, which puts the reading load back on top of the clock.

Fluid reasoning typically holds. A dyslexic reader who grinds through a vocabulary section will often complete matrix items at roughly the level the rest of their profile predicts, because a matrix does not have to be read. The composite then averages one fair estimate with one depressed estimate and understates the reasoning.

How large that gap gets varies from person to person, and a gap is not automatically meaningful on its own. The companion piece on verbal and non-verbal score splits covers when a difference between two indexes is big enough to interpret at all.

ADHD and IQ Test Scores: Inconsistency, Not a Lower Ceiling

The characteristic pattern for ADHD on a test is not uniformly weaker performance. It is variability. The same person can solve a hard matrix item in seconds and then miss three easy ones in the block that follows, and where in the session an item fell can matter more than how hard it was.

Three separate things cost points here, and they are worth keeping apart because they respond to different fixes.

  • Time pressure. A per-item or whole-test clock converts a slow start into lost items, even when the reasoning would have arrived a few seconds later.
  • Sustained-attention drift. Dozens of near-identical matrix puzzles in a row is close to a worst case: low novelty, no feedback, and wrong answers that feel exactly like right ones.
  • Working-memory load. Items that require holding several constraints at once are harder to finish when the holding itself takes effort.

That last one is worth holding apart from reasoning itself: the two are related but not interchangeable, and someone can have a genuinely low working-memory index and strong fluid reasoning at the same time. An item that loads both is limited by the weaker of the two.

Sleep and time of day move ADHD test performance, and so can where someone is in their usual routine on the day. That is another reason to treat one sitting as a single sample rather than a verdict, and to be sceptical of any score taken at the end of a long day.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

Autism: Uneven Profiles and Confounded Instructions

There is no autistic IQ profile. Autistic people cover the entire measured range, and the variation inside the group is far larger than any average difference between it and everyone else. Anything that describes one shape of profile as typical is describing a subset and calling it a population.

One pattern does show up often enough to be worth naming: a split between verbal and perceptual performance, running in either direction. Some autistic people score markedly higher on matrix reasoning than on verbal subtests, particularly where verbal items reward conventional usage; others show the reverse.

The larger measurement problem is often the wrapper rather than the item. Instructions written loosely can be read literally and answered correctly by their own logic. Asking which one does not belong has several defensible answers, and an item lost that way costs the same as an item nobody could solve. The score cannot tell the two apart.

Conditions matter too. An unfamiliar room, harsh lighting, the social weight of being watched while you think: none of that is reasoning, and all of it can move a number.

What an Online Screener Does to These Profiles

An unproctored online test has no way to accommodate anyone. It cannot verify a diagnosis, grant extra time, offer a quiet room, read an item aloud, or notice that you stopped concentrating twenty minutes ago. It records what happened and scores it.

Format still changes the size of the problem. A timed IQ test stacks the effects above into their worst configuration: a speed penalty, no way back from a slow opening, and a hard stop that arrives whether or not you were nearly there.

If the clock is your main obstacle, the untimed classical format is a fairer instrument for you. If reading load is the obstacle, a culture-fair test built from figures rather than sentences takes most of the language out from between you and the item. Neither is a formal accommodation; each just removes one confound.

Accommodations, and Who Can Authorise Them

Formal assessment does have answers to all of this, and they are unglamorous rather than clever.

  • Extended time, commonly one and a half times the standard limit, sometimes double.
  • Scheduled breaks between subtests, or the session split across more than one day.
  • A separate quiet room, with the examiner present and nobody else.
  • Untimed administration of subtests where speed is not the ability being measured, reported alongside the standard scoring rather than in place of it.
  • Items read aloud, or answers given orally rather than written.

None of that is self-service, which is the practical point most articles skip. Accommodations are authorised by whoever owns the assessment: a qualified psychologist for a clinical evaluation, a school’s special educational needs process for a child being tested, a university disability service, or an employer’s occupational-health route at work. Each normally wants documentation first, which is one more reason a screener result cannot start the process.

If You Think Your Score Is an Underestimate

Start by treating the number as information about a sitting rather than about you. Which sections felt bad, and why? Running out of clock, losing the thread halfway through a block, and reading the same sentence four times are three different failures, each pointing at a different index dragging the composite down.

Then take the test again in a format that removes the thing you identified, and compare. Two scores with a known difference between the conditions that produced them tell you more than one score of any size, and that comparison is the closest thing to self-accommodation a free screener can offer.

If a defensible number actually matters — for a school placement, an accommodation request, an assessment — an online result will not do that job. What a free online IQ test gives you is a rough bearing and, taken twice under deliberately different conditions, a sense of how much of your score is about the format rather than your reasoning.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged accurate iq test, ADHD, Autism, Dyslexia, intelligence test, iq assessment, IQ Test, iq test results, iq testing, kids iq test, Neurodiversity, Processing Speed, Test Accommodations, Working Memory