IQ Metrics
IIF Certified Assessment Start IQ Test
IIF Certified Assessment

Is a 120 IQ High?

Scores & Scales

Is a 120 IQ Score High? Where the Number Actually Sits

A score of 120 sits comfortably above average, and roughly nine people in ten score below it. But "high" is a comparison, not a property, and the honest answer depends on which scale produced the number, how much error is wrapped around it, and what you were hoping the score would tell you.
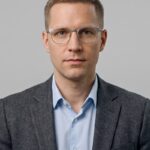
Bell curve of IQ scores with everything below 120 shaded, showing that about 91 percent of people score below that mark and about 9 percent score at or above it

Yes. A score of 120 is high. On a test scaled to a mean of 100 and a standard deviation of 15, it sits one and one-third standard deviations above the average, which places it at roughly the 91st percentile — about nine people in every ten score below it.

That is the answer. The rest of this article is about the three things the number does not say, because those are what people usually want when they ask the question: how rare 120 actually is, how much of it is real, and what it is supposed to be good for. If you want the companion piece on what a 120 reports about the measurement itself, we wrote that separately as what an IQ of 120 means, and what it does not.

Where 120 sits on the curve

IQ scores are not counts of anything. They are positions in a distribution, built by giving a test to a large representative sample and then re-expressing every raw score as a rank within that sample. The scale is fixed by convention: the middle of the reference group is called 100, and one standard deviation is called 15 points.

That convention is what turns 120 into a percentile. Twenty points is 1.33 standard deviations, and on a normal curve 1.33 standard deviations above the mean cuts off the top 9.2 percent. So:

  • About 91 percent of the reference population scores below 120.
  • About 1 person in 11 scores at or above it.
  • Inside a room of 100 people drawn at random, roughly nine others would match or beat the score.

That last framing is the one worth sitting with. A 120 is genuinely above average and it is genuinely not rare. Both are true, and which one feels more accurate depends entirely on the comparison group you have in your head. You can check any score against the curve directly with the IQ percentile calculator, or see the whole distribution laid out on the IQ bell curve page.

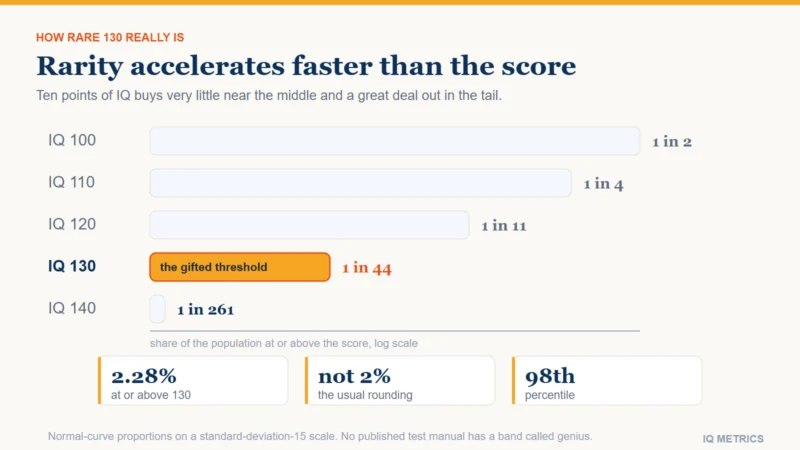
It is also worth noticing how quickly rarity changes as you move along the curve. Going from 100 to 120 takes you past 41 percent of the population. Going the same twenty points again, from 120 to 140, takes you past only another 8 percent, because the curve is thinning out underneath you. Equal steps in score are not equal steps in rarity, and that asymmetry is why a 20-point gap sounds like a fixed quantity and behaves like anything but. The scale is symmetric in the other direction too: 120 is exactly as far above the mean as 80 is below it, and the two are about equally common.

Bell curve of IQ scores with everything below 120 shaded, showing that about 91 percent of people score below that mark and about 9 percent score at or above it

The label attached to 120 depends on which manual you read

There is no single official vocabulary for IQ bands. Every test publisher writes its own, and they disagree at exactly the point where 120 falls.

  • On the Wechsler scales, the band containing 120 is usually printed as High Average or, in older editions, Superior — the boundary has moved between revisions.
  • On Stanford-Binet, 120 sits in Superior.
  • Many popular charts online invent a band, then attach adjectives to it that no test manual has ever used.

This matters more than it sounds. A reader who finds 120 called “Superior” on one chart and “High Average” on another has not found a contradiction in the data; they have found two publishers labelling the same slice of the same curve differently. If you want the labels compared properly, that is what IQ classifications and the ranges of IQ level are for. The number is the finding; the adjective is editorial.

Change the scale and 120 moves

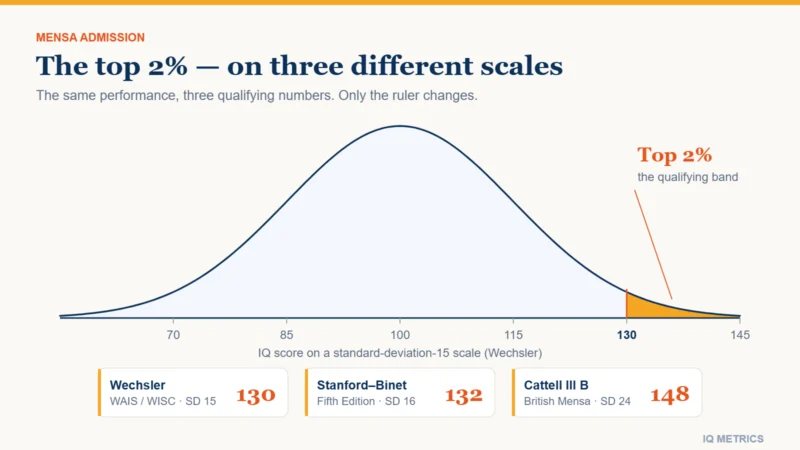
The 15-point standard deviation is a convention, not a law. Some tests, Cattell’s among them, use 16 points, and a handful of high-range tests use 24. The same performance therefore produces different numbers depending on which scale printed the report.

A score of 120 on a 15-point scale is about 121 on a 16-point scale, because both describe the same 91st percentile. That is a small gap in the middle of the range, but it widens fast towards the tails, which is why comparing two scores from two different tests is a real problem rather than a pedantic one. The IQ score converter does the translation, and the 15 versus 16 problem is written up in full.

The practical rule: a score without its scale is not a score. If a report does not say what standard deviation it used, the number in it cannot be compared to anything.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

The error bar around 120 is wider than people expect

No test measures without error. A well-built professional instrument reports a 95 percent confidence interval of roughly plus or minus 4 to 5 points on the full-scale score, and shorter or online tests are wider still.

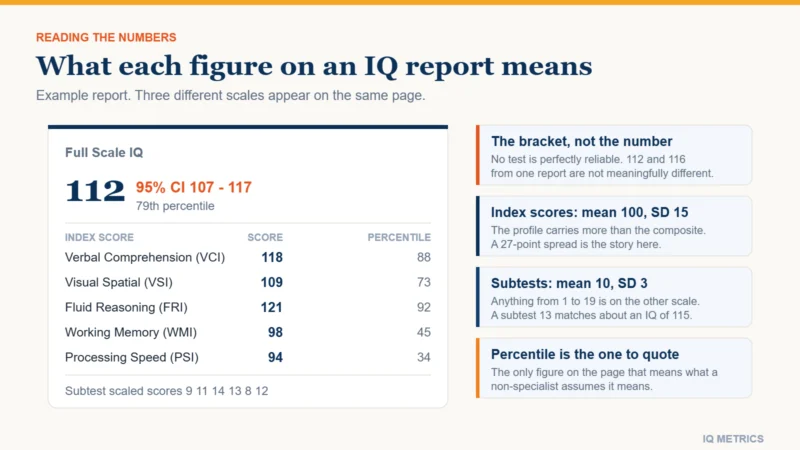
So a measured 120 usually means something closer to “this person’s true score is very probably somewhere between 115 and 125”. Every number in that band is compatible with the evidence, and treating the printed 120 as exact is the single most common misreading of an IQ report. Two people scoring 118 and 122 have not been distinguished by the test at all. The margin of error explained covers why, and how to read an IQ test report shows where the interval is printed on an actual score sheet.

What a 120 does and does not predict

Cognitive ability scores are among the better-validated predictors in psychology, which is a lower bar than it sounds. In the ranges around 120 the relationships are real, consistently replicated, and modest.

  • Academic work. Ability scores correlate with school attainment at roughly 0.5, which means they explain about a quarter of the variation in outcomes and leave three quarters to everything else. See does IQ predict school success.
  • Job performance. The correlation in complex roles is real but smaller than the older literature claimed, and it has been revised downwards as the corrections applied to it were re-examined. What a score predicts at work has the current numbers.
  • Income. Weakly, and mostly through education. Does IQ predict income goes through the evidence.
  • Almost everything else people hope for. Judgment, discipline, creative output and good decisions are only loosely related to ability scores, which is the whole subject of why smart people make bad decisions.

None of that makes 120 unimportant. It makes it a starting condition rather than a verdict.

Is 120 high enough for a specific thing?

The question behind the question is usually about a threshold someone else has set, and those are easier to answer than the general case.

  • Mensa. No. The entry requirement is the 98th percentile, which is 130 on a 15-point scale and 132 on a 16-point one — though what 130 actually marks is a separate question from what it admits you to. See Mensa IQ score requirements.
  • School gifted programmes. Usually not, on a strict cutoff, though many districts use local rather than national norms and some screen more broadly. Gifted cutoff scores explains why the line is set where it is and who it misses.
  • Postgraduate study or a demanding profession. There is no cognitive test threshold for either, and the admissions tests that do exist measure achievement and preparation as much as ability. Achievement tests versus IQ tests draws the line.

What to do with a 120

Very little, honestly, and that is not a dismissal. A single full-scale number is the least informative thing on a proper score report. The index scores underneath it — verbal comprehension, perceptual reasoning, working memory, processing speed — carry the information that is actually usable, and a flat 120 across four indices describes a different person from a 120 built out of a 135 and a 100.

If the number came from a short online test, treat it as an estimate with a wide interval rather than a measurement. If it came from a professional assessment, the interesting reading is in the profile, not the headline. Either way the useful next questions are about the shape of the score rather than its size: verbal versus non-verbal scores and processing speed are where that starts.

And if you are here because you scored 120 and wondered whether it was good, the more useful comparison is not against other people. It is against the same test taken again under better conditions, which is a genuinely different question and one the IQ comparison tool is built to answer.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged confidence interval, full scale iq, high average iq, intelligence test, iq 120, iq rating, iq scale, IQ Score, iq test ranges, Norm Group, percentile rank, Predictive Validity, standard deviation iq, superior iq

Gifted Cutoff Scores

Scores & Scales

Gifted Cutoff Scores: Why a Single Number Misses Children

Most gifted programmes draw their line at an IQ of 130. The number is a statistical convention rather than a boundary in nature, and three well-documented features of how the score is produced and used mean a strict cutoff reliably excludes children who belong on the other side of it.

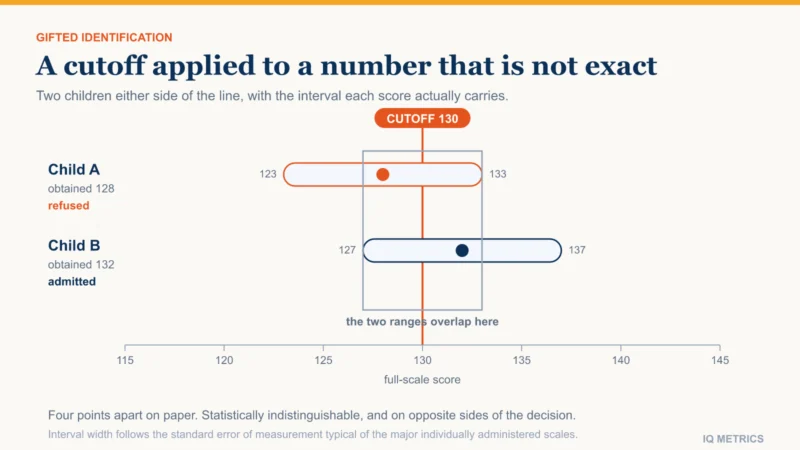
Diagram showing a confidence interval straddling the gifted cutoff of 130, illustrating how two children with different obtained scores can have overlapping true-score ranges

An IQ of 130 is the usual entry requirement for a gifted programme, and it is a convention, not a discovery. It marks two standard deviations above the mean on the scales most tests use, which places it at roughly the 98th percentile. Nothing changes at that point in the distribution. There is no cognitive category boundary there; there is a round number chosen because it is convenient.

That would matter less if the number the cutoff is applied to were exact. It is not, and the gap between an obtained score and the quantity it estimates is large enough to change the answer for a great many children. Three separate features of the process compound: measurement error, the choice of comparison group, and who gets tested in the first place.

Where 130 comes from

Modern tests are scored so that the population mean is 100 and the standard deviation is 15. Two standard deviations up is 130, which leaves about 2.3 per cent of the population above it. That is the entire derivation. The choice of two standard deviations mirrors the convention on the other side of the distribution, where a similar cutoff has historically been used in defining intellectual disability.

Because it is a percentile in disguise, the same label means different things on different instruments. A test standardised with a standard deviation of 16 rather than 15 puts the same percentile at a different number, and older scales computed scores in ways that do not map cleanly onto percentiles at all. Comparing a reported 132 from one instrument with a 129 from another is not a meaningful comparison — the underlying scales differ, as IQ classifications sets out.

The measurement error nobody applies

Every well-constructed test reports a standard error of measurement, and every properly written report expresses the result as an interval rather than a point. On the major individually administered scales, the ninety-five per cent interval around a full-scale score is usually about five points either side.

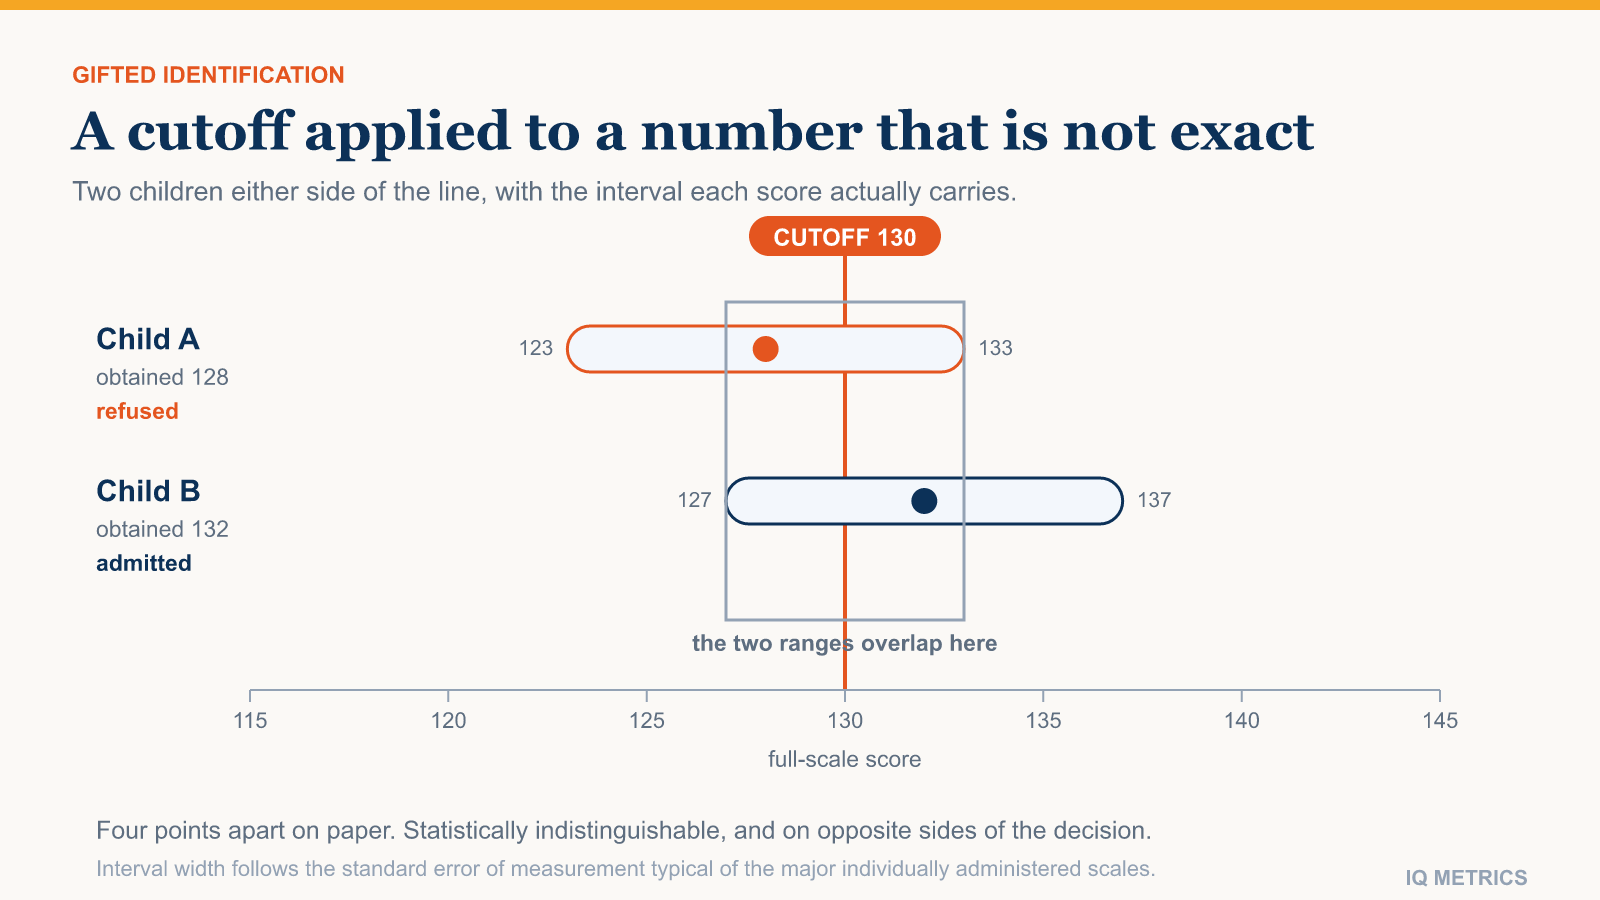
Work through what that does to a cutoff. A child who obtains 128 has a plausible range running from roughly 123 to 133. A child who obtains 132 has a range from roughly 127 to 137. Those ranges overlap across most of their width. The two children are not meaningfully different on the thing the test estimates, and yet a strict cutoff admits one and refuses the other.

The same arithmetic explains why retesting produces so many reversals. A child who scores 127 in March and 133 in October has not become more able; a second draw from the same distribution came out differently, which is what the interval was warning about. Reading an interval correctly is the single most useful skill for anyone handling one of these reports, and it is covered in how to read an IQ test report.

Diagram showing a confidence interval straddling the gifted cutoff of 130, illustrating how two children with different obtained scores can have overlapping true-score ranges

National norms against local norms

A standard score compares a child to a nationally representative sample. For deciding whether that child needs a different level of instruction than their classmates are getting, the relevant comparison is often the classmates.

The two diverge sharply in schools whose intake is not representative. In a high-achieving school, a large fraction of pupils may clear a national cutoff, so the cutoff stops discriminating and the programme becomes oversubscribed. In a school serving a disadvantaged catchment, almost nobody clears it, so a child who is dramatically ahead of everyone around them and plainly under-challenged is not identified — the label is reporting the catchment rather than the child.

Local norms address this by ranking within the school. They are not a softer standard; they answer a different and more relevant question, namely whether this child is being taught at the right level given the class they are actually in. The two criteria are best used together.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

The bigger leak: who gets tested at all

Measurement error and norm choice both assume a test happened. In many systems, identification begins with a nomination from a teacher or a parent, and only nominated children are assessed. Every child never nominated is outside the process before any cutoff is applied.

Research on districts that switched from referral-based identification to universal screening — testing every child in a given year group rather than waiting for a nomination — has found substantial increases in the number of children identified from groups that were previously underrepresented, including children from low-income households and those whose first language is not the language of instruction. The children were there; the referral step was not finding them.

This is the largest of the three effects and the easiest to fix, and it is worth being precise about what it shows. It is not a claim that the test was biased against those children. It is a claim that the step before the test decided who would be measured, and that step was not neutral. The instructions given around an assessment can matter as much as the assessment, a theme that also runs through stereotype threat.

The children a cutoff is worst at finding

Two groups are missed so consistently that the pattern is a known feature of the system rather than an accident of any one district.

The first is children whose ability and difficulty coexist — a strong reasoner who is also dyslexic, has attention difficulties, or is autistic. A full-scale score is an average across indexes, and averaging a very high reasoning index with a much lower processing speed or working memory index produces a middling composite that describes neither. The composite is the number the cutoff reads, so the child is refused on the strength of a figure that no clinician would treat as meaningful. Where the index scores are far apart, the full-scale figure should be set aside and the profile read instead — ADHD, autism, dyslexia and IQ test scores covers what those profiles look like.

The second is children still acquiring the language of the test. Verbal subtests measure vocabulary and verbal reasoning in a specific language, and a child two years into learning it will score below their reasoning ability on those subtests and much closer to it on the non-verbal ones. Averaging the two produces a composite that mostly reports language exposure. The gap between the two kinds of subtest is set out in verbal and non-verbal IQ scores.

In both cases the test is doing what it was built to do. The failure is in reducing its output to one number and comparing that number to a line.

What a parent can reasonably do with this

None of this means the score is worthless. It means a single number compared against a single line is a weak decision rule built on top of a reasonable measurement.

  • Ask for the interval, not the number. A proper report gives one. If a decision rests on a point estimate a few points from the line, the interval is the relevant fact.
  • Ask what the comparison group was. National norms and local norms answer different questions, and which one was used should be stated rather than inferred.
  • Ask whether screening is universal. If identification depends on nomination, then not being nominated is not evidence about a child.
  • Treat one session as one session. Attention, sleep and rapport with the examiner all move a result, which is why the same child produces different numbers on different days.

The useful question is not whether a child crosses a line. It is whether they are being taught at a level that fits them, which a score can inform and cannot settle. For what the high end of the scale does and does not mean, see what is genius IQ level; for how age affects the interpretation of a childhood score, see what age is most accurate to take an IQ test.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged confidence interval, full scale iq, genius iq level, gifted cutoff, gifted identification, iq classifications, iq scale, IQ Score, IQ Test Range, kids iq test, local norms, Measurement Error, Norm Group, percentile rank, universal screening

Stereotype Threat and Test Scores

Taking a Test

Stereotype Threat: Does It Really Change Test Scores?

Few findings in psychology have been cited as widely, or held up as poorly, as stereotype threat. The original experiments were elegant and the idea is intuitive. Two decades of replication attempts have left a much smaller and more uncertain effect than the textbook version suggests.

Diagram distinguishing cultural bias in test items, which is a property of the questions, from stereotype threat, which is a property of the testing situation and the instructions given before it

Stereotype threat is the proposal that being reminded of a negative stereotype about a group you belong to, immediately before a test that the stereotype concerns, lowers your performance on it. It is one of the most cited ideas in social psychology, it appears in most undergraduate textbooks, and it has had a rougher time in the replication literature than almost any other finding of comparable fame.

Both halves of that sentence deserve equal weight. This article sets out what the original studies found, why the effect is a different thing from test bias, what happened when large pre-registered replications were run, and what a person about to sit a test should reasonably conclude.

What the original experiments showed

The founding studies, published by Claude Steele and Joshua Aronson in 1995, gave university students a set of difficult verbal questions taken from a graduate admissions test. The manipulation was purely in the framing: one group was told the task was diagnostic of verbal ability, another that it was a laboratory exercise in problem solving. The questions themselves were identical.

The reported result was that performance differed by condition in a way that tracked the stereotype the framing made salient. It was a striking demonstration because nothing about the test had changed. If a sentence of instructions could move scores, then a score was partly a product of the situation in which it was collected, not only of the person producing it.

One methodological detail matters for what came later. The headline analyses adjusted for participants prior admissions-test scores. Whether that adjustment is appropriate has been argued about ever since, because it changes the quantity being estimated from “how did the groups score” to “how did they score relative to expectation”. Reasonable people disagree, and the unadjusted contrasts are weaker.

It is not the same thing as a biased test

These two ideas are constantly merged and they make different claims about different objects.

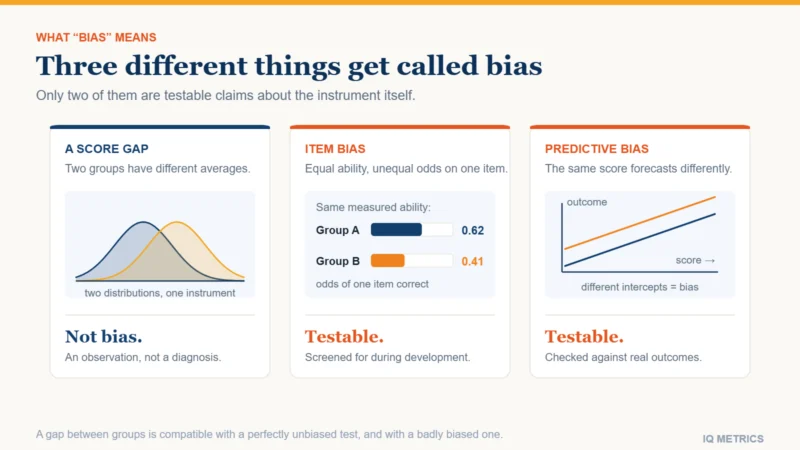
  • Test bias is a property of the questions. An item is biased when it draws on knowledge or conventions unevenly distributed across the groups taking it, so the item measures something other than the ability it is supposed to measure. It is detectable by statistical analysis of item functioning, and it is fixed by rewriting or removing items.
  • Stereotype threat is a property of the situation. The claim is that identical items yield different scores depending on what is said beforehand. Nothing about the instrument is faulty; the context surrounding its administration is doing the work.

The practical consequence is that they call for different remedies and produce different evidence. The item-level question is covered in cultural bias in IQ tests, which is about content. This article is about framing. Conflating them lets a weak result in one area be used as support in the other.

Diagram distinguishing cultural bias in test items, which is a property of the questions, from stereotype threat, which is a property of the testing situation and the instructions given before it

What replication did to the effect

The original result was followed by hundreds of studies, most of them small, and for some years the meta-analytic average looked solid. Then the same scrutiny that reshaped much of social psychology arrived, and it found the usual problems.

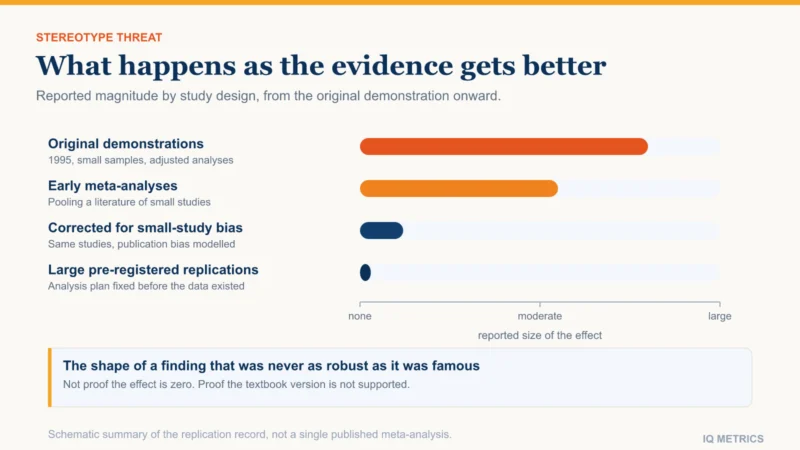
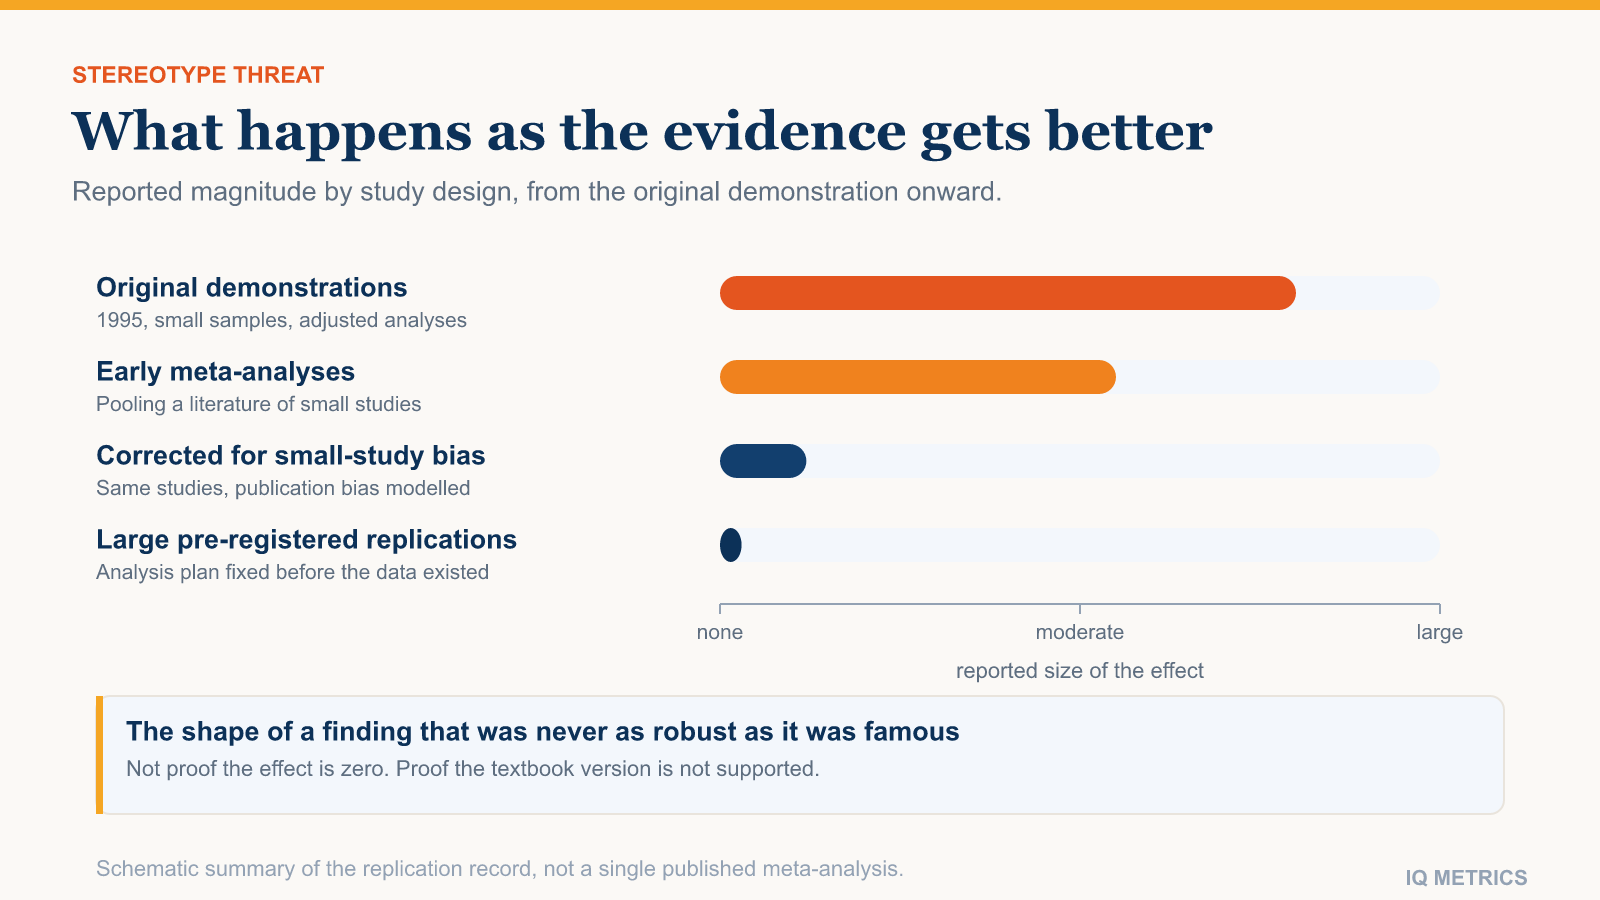
  • Small-study effects. Meta-analyses of the stereotype-threat literature on mathematics performance in girls found the classic signature of publication bias: small studies reporting large effects, large studies reporting small ones. Correcting for it moved the adjusted estimate close to zero.
  • Pre-registered replications came back null. Large studies that fixed the analysis plan in advance, across multiple schools and sizeable samples, have repeatedly failed to find the effect.
  • Analytic flexibility was substantial. Whether to covary out prior ability, which subgroups to analyse, and which outcome to treat as primary were all choices made after the data existed in much of the early work.

None of this establishes that the effect is zero. Absence of evidence in a set of replications is not the same as evidence of absence, and it remains possible that the phenomenon is real but requires conditions the replications did not reproduce. What it does establish is that the confident textbook version — a large, robust, easily triggered effect — is not supported.

It is worth noticing what this does and does not change about the underlying questions. Stereotype threat was often invoked to explain observed differences between groups on tests. If the effect is much smaller than claimed, that explanation weakens — but the differences themselves were always a separate empirical matter, with their own large literature and their own unresolved arguments, and nothing about the replication failures settles those. IQ tests and gender differences takes that question on directly. A weak mechanism is not evidence for any particular alternative mechanism.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

The laboratory and the examination hall

Almost all of this evidence comes from short experiments on volunteers, usually students, working through a subset of test items in a room they will leave in half an hour. Whether the effect transfers to a real assessment that matters to the person taking it is a separate empirical question, and it has been studied much less.

There are arguments in both directions and it is worth seeing them set against each other rather than picking one. On one side, a real assessment carries far more consequence, and if evaluative pressure is the mechanism then more consequence should mean more pressure. On the other, a real assessment is usually taken by someone who has prepared for it, in a familiar format, without an experimenter saying anything about groups at all — and the manipulation is precisely what the laboratory studies were adding.

The few attempts to test for the effect in operational admissions and certification data have generally not found it. That is not decisive either, because a field setting cannot control what each candidate is thinking. But it does mean the confident extrapolation from a thirty-minute laboratory task to national examination results was never supported by direct evidence.

The mechanism that still looks plausible

The most credible proposed mechanism is that evaluative pressure consumes working memory. Monitoring your own performance, suppressing an intrusive worry and continuing to reason all compete for the same limited resource, so anything that adds to the monitoring load has less capacity left for the task.

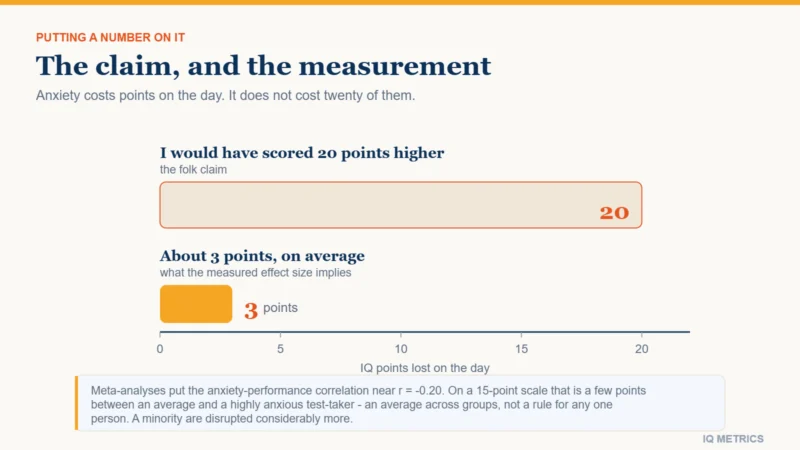
That account is attractive because it does not depend on stereotypes at all. It predicts that any source of evaluative pressure should cost performance, which is a much better-supported claim — and one with a substantial independent literature behind it, covered in test anxiety and IQ scores. On this reading, stereotype threat is a specific and hard-to-reproduce instance of a general effect that is easy to reproduce.

It also explains why the demonstrations were fragile. If the active ingredient is the pressure rather than the stereotype, then the stereotype manipulation only works when it happens to generate enough pressure — which will depend on the sample, the setting, the era and how plausible the framing sounds to the people hearing it.

What this means if you are about to take a test

The practical advice is unchanged by the controversy, because it follows from the well-supported half rather than the contested one.

  • Evaluative pressure costs performance. Whatever reduces it — familiarity with the format, an unhurried setting, treating a practice attempt as practice — is worth having.
  • Test conditions are part of the measurement. A score collected under pressure and one collected calmly are not interchangeable, which is one reason a single administration deserves less weight than people give it.
  • Be sceptical of a single dramatic study, including one you like. The reason this finding was believed for so long is that it was elegant and widely repeated, not that it was robust.

The broader lesson generalises past this one result. A test score is a measurement taken under conditions, and conditions vary. That is also why a threshold applied to a single number does more damage than most people realise, which is the subject of gifted cutoff scores. Where a finding in this field is genuinely contested, this site says so rather than picking the version that reads better.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged Cultural Bias, Culture Fair Test, Differential Item Functioning, intelligence test, IQ Science, IQ Test, iq test preparation, iq test tips, iq testing, Measurement Invariance, publication bias, replication crisis, Stereotype Threat, test anxiety

Nutrition and IQ

Research & Evidence

Nutrition and IQ: What Diet Can and Cannot Change

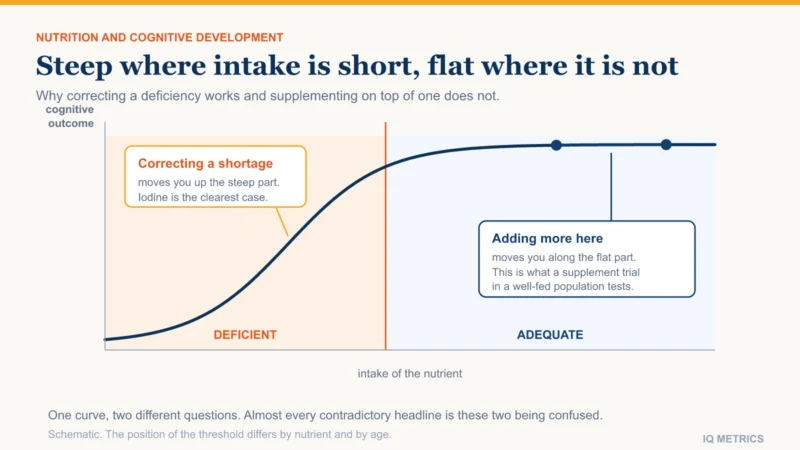
The evidence on diet and intelligence looks contradictory until you separate two questions that get asked as one. Fixing a real deficiency produces some of the largest effects in the field. Adding more of the same nutrient to an already adequate diet produces close to nothing.

Diagram contrasting the steep cognitive gain from correcting a nutritional deficiency with the flat response to supplementing an already adequate diet, shown as a curve that rises sharply and then plateaus

Nutrition affects IQ scores substantially when a real deficiency is present and corrected, and barely at all when it is not. Those two findings are not in tension; they are the same curve read at different points. The relationship between a nutrient and cognitive development is steep where intake is inadequate and close to flat once it is sufficient, which is exactly what you would expect from something the body requires in a fixed amount rather than an unlimited one.

Almost every confusing headline in this area comes from applying a result obtained at one end of that curve to people sitting at the other. This article separates the two, names the deficiencies where the evidence is strong, and explains why the supplement trials in well-fed populations keep coming back empty.

Iodine: the largest nutritional effect on record

Iodine is required to make thyroid hormone, and thyroid hormone governs brain development before and shortly after birth. Severe deficiency during that window produces profound and permanent intellectual disability. What made iodine the standout case is that the milder end of the range turned out to matter too.

Meta-analyses comparing populations in iodine-deficient regions with comparable iodine-sufficient ones have reported differences on the order of thirteen IQ points. That is an enormous figure by the standards of this literature — roughly the gap between the middle of the distribution and the boundary of the bottom sixth. It is also why salt iodisation is routinely described as one of the highest-return public health measures ever implemented.

The caveats are real and worth stating. These are comparisons between regions rather than randomised assignments, and iodine-deficient regions differ from iodine-sufficient ones in other ways. The supplementation trials that have been run give smaller effects than the observational comparisons. But the direction is consistent, the mechanism is understood at the level of a specific hormone, and no serious reviewer disputes that severe deficiency causes cognitive harm.

Iron, and the deficiencies that are common enough to matter

Iron deficiency anaemia in infancy is associated with poorer performance on developmental and cognitive assessments, and the association persists in children who are treated later — which suggests, without proving, that part of the effect is on development rather than on current functioning. General protein and energy malnutrition in early childhood shows the same pattern.

Two features recur across all of these findings and are worth holding on to:

  • Timing dominates dose. The same deficiency matters enormously in the first two years and much less later. The periods when the brain is building structure are the periods when a shortage of building material is expensive.
  • Correction is incomplete. Treating a deficiency after the developmental window has passed improves things without restoring the counterfactual. This is the single most important reason the deficiency findings do not translate into a supplementation strategy for adults.
  • Deficiency travels with everything else. Households where children are iron-deficient differ in many other respects. The better studies adjust for this; adjustment is never complete, and the honest estimates carry wide intervals.

Breastfeeding: the confounding problem in miniature

Observational studies have consistently found that breastfed children score a few points higher on cognitive tests. The problem is that in most countries the mothers who breastfeed for longer differ systematically from those who do not, in education, income and their own test scores — all of which independently predict a child result.

Two study designs have attacked this. Sibling comparisons, which contrast siblings raised in the same household who were fed differently, shrink the association sharply and in several analyses remove it. The PROBIT trial in Belarus did something rarer: it randomised the promotion of breastfeeding across maternity hospitals, producing a genuine experimental contrast. At age six and a half it found a meaningful verbal advantage in the intervention group; by adolescence, much of that had attenuated.

The reasonable position is that there is probably a small effect, that it is far smaller than the raw observational gap, and that anyone quoting the raw gap is quoting mostly the confounding. This is a good general lesson for reading any claim in this area: ask what else differs between the groups being compared, and whether any design in the literature has removed it.

Diagram contrasting the steep cognitive gain from correcting a nutritional deficiency with the flat response to supplementing an already adequate diet, shown as a curve that rises sharply and then plateaus
Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

Why the supplement trials keep coming back empty

Omega-3 fatty acids are the clearest example. The reasoning behind them is sound in outline: long-chain fatty acids are structural components of neural membranes, and infants deprived of them do worse. The inference that adding more to a child who is already getting enough will produce further gains is where it breaks down.

Randomised trials of omega-3 supplementation in adequately nourished children and adults have largely reported null results for general cognitive ability, and systematic reviews of that literature reach the same conclusion. The same pattern holds for most multivitamin trials in well-nourished populations: small, inconsistent, often non-significant, and rarely replicated at the same magnitude.

This is not a claim that supplements are useless. It is a claim about which question they answer. A supplement corrects a deficiency. If there is no deficiency, there is nothing to correct, and the trial measures what happens when you add a nutrient to someone who already has enough of it. The answer, repeatedly, is very little.

How to read a diet-and-intelligence headline

Studies in this area reach the public through a filter that systematically favours the surprising over the reliable. A handful of questions will usually tell you which kind you are looking at, and they can be asked without any technical knowledge of the subject.

  • Was the population deficient to begin with? If the sample was already adequately nourished, a null result is the expected result and a positive one needs replication before it is worth anything.
  • Was anything randomised? Diet is chosen, and people who choose one diet differ from people who choose another in income, education and health behaviour. Where a trial exists, prefer it to a survey, even a very large survey.
  • What was the outcome measure? A change on one reaction-time task is not a change in general ability. Studies often measure several outcomes and report the one that moved.
  • How long was the follow-up? Effects that are present at six months and gone at five years were probably never effects on development. The breastfeeding literature is the clean illustration of this.
  • Who paid for it? Trials of a specific supplement funded by its manufacturer report positive results more often than independently funded trials of the same compound.

Applying that list to the popular claims removes most of them. What survives is a short list dominated by early-life deficiency, which is the opposite of the story the supplement aisle tells.

Breakfast, glucose and the difference between state and trait

Skipping breakfast does measurably affect performance on attention and memory tasks in the following hours, particularly in children who are undernourished to begin with. This is a real effect and it is not the same kind of effect as anything above.

An IQ score is meant to estimate a stable characteristic. Hunger, sleep loss and caffeine change how well you perform on the day without changing the thing the test is trying to estimate — they add noise to the measurement rather than moving the quantity being measured. That distinction is why “eat before the test” is sensible advice for getting an accurate reading and is not a way to become more intelligent. The rest of the same-day list is in what affects IQ test results, and the case of nerves specifically is in test anxiety and IQ scores.

What to take from all of this

The picture that emerges is narrower and more useful than either “diet determines intelligence” or “diet is irrelevant”.

  • Correcting severe deficiency during early development produces some of the largest effects anywhere in this field, and iodine is the clearest case.
  • The effects are developmental, so most of the opportunity lies before school age rather than before a test.
  • Supplementation on top of adequacy has repeatedly failed to produce cognitive gains in randomised trials, and the honest reading of that literature is that it does not work.
  • Same-day factors such as hunger affect the measurement rather than the ability, which is why they matter for accuracy and not for capability.

Nutrition therefore belongs in the same small category as lead exposure: a genuine, well-evidenced influence on population-level cognitive development that operates almost entirely through early childhood, and that has very little to say to an adult wondering about their own result. The wider question of what can and cannot be changed later is covered on can you improve your IQ.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged breastfeeding, cognitive development, dietary supplements, how to increase iq, Improving IQ Scores, intelligence test, iodine deficiency, IQ Science, IQ Score, iq testing, micronutrients, nature vs nurture, nutrition and iq, omega 3

Lead, Pollution and IQ

Research & Evidence

Lead, Pollution and IQ: The Exposures That Move Scores

Most things people believe raise or lower intelligence turn out to be small, contested or confounded. Childhood lead exposure is the exception: one of the best-established environmental effects on cognitive test scores anywhere in the literature, with a dose-response curve most people find counterintuitive.

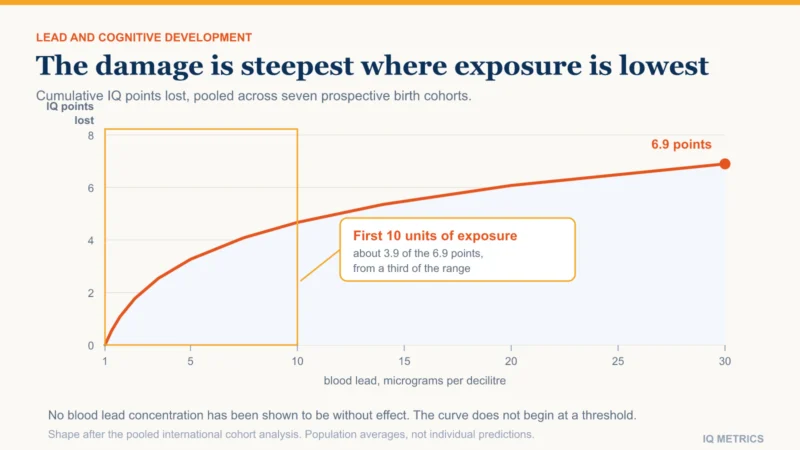
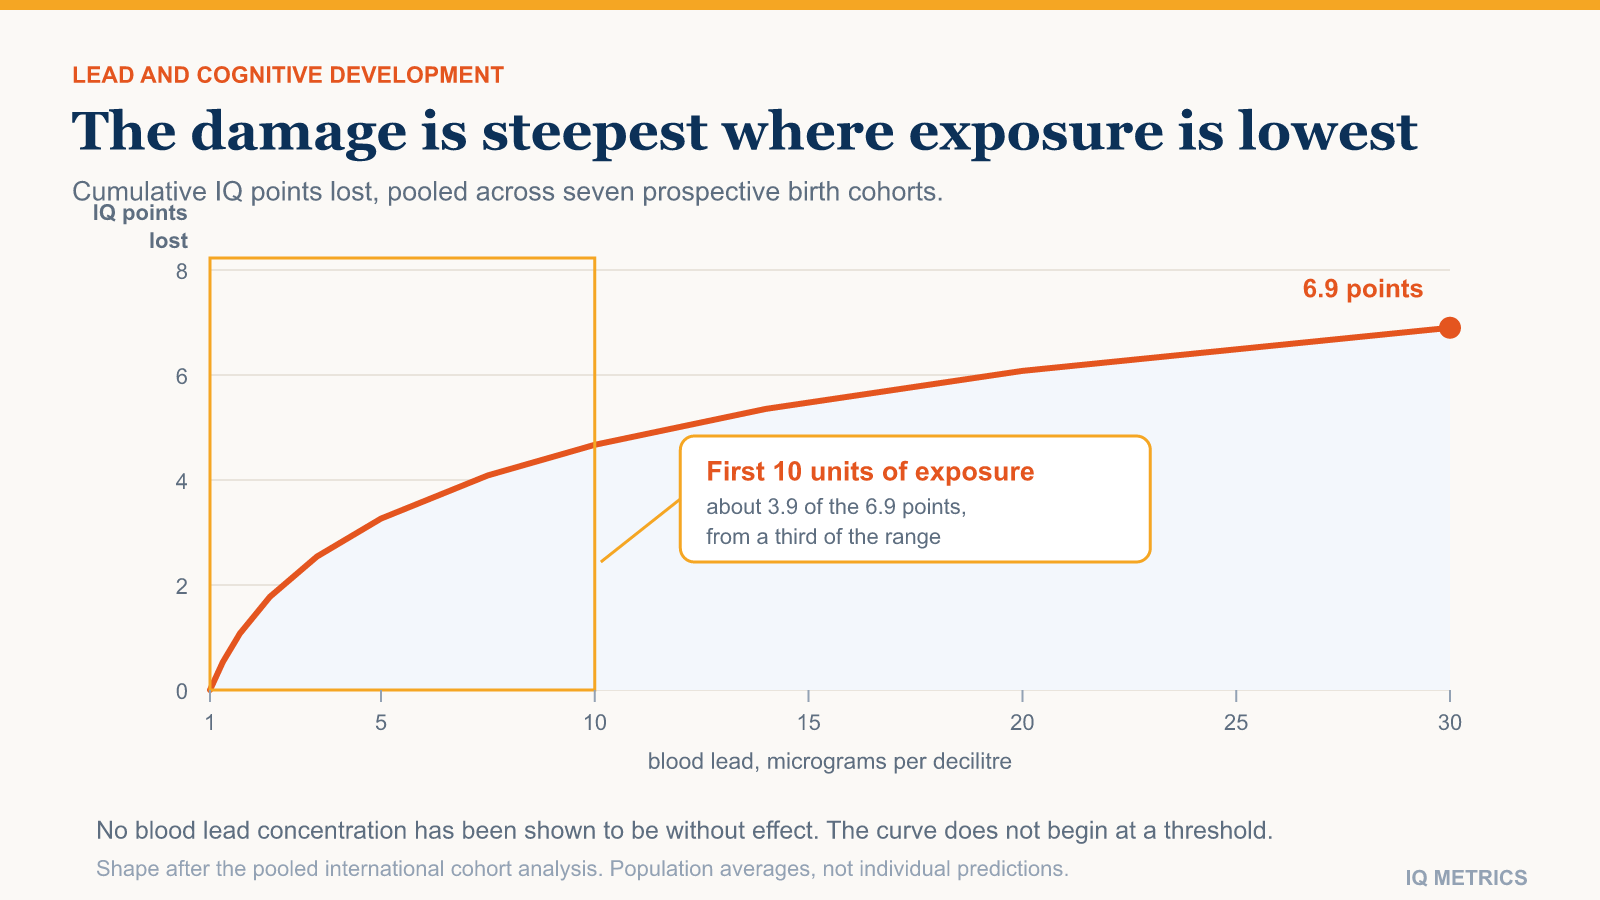
Chart showing the supralinear relationship between childhood blood lead concentration and IQ score, with the steepest loss occurring across the lowest range of exposure rather than the highest

Childhood lead exposure lowers IQ scores, and unlike almost every other environmental claim about intelligence, this one is not seriously disputed. It is supported by prospective cohorts on four continents, by a pooled analysis that combined seven of them, and by a population-scale natural experiment that ran for two decades when leaded petrol was withdrawn. Neither the World Health Organization nor the United States Centers for Disease Control now recognises a blood lead concentration below which no effect is observed.

The part that surprises people is the shape of the curve. The damage is not spread evenly across the range of exposure. Per unit of lead, the steepest loss happens at the lowest concentrations — the ones that were treated as unremarkable for most of the twentieth century. This article sets out what the evidence actually says, how large the effect is in score points, and why none of it tells you anything useful about your own adult test result.

Why a developing brain is the vulnerable target

Lead has no biological function in the human body. It is absorbed because it is chemically similar enough to calcium, iron and zinc to be taken up by the same transport routes, and children absorb a far larger fraction of what they ingest than adults do. Once in circulation it crosses the placenta and the immature blood-brain barrier, and it interferes with processes that are at their most active in early childhood: synapse formation, pruning and the myelination that makes signalling efficient.

That timing is the whole story. The same exposure that produces a measurable cognitive deficit in a two-year-old produces very little in a thirty-year-old, because the thirty-year-old has already built the structures the exposure disrupts. It is one of the clearest cases in the field of a factor that acts on brain development rather than on brain performance, which is also why the effect does not wash out: the deficits found at age five are still there at age ten.

How large is the effect in score points?

The most-cited number comes from a 2005 pooled analysis led by Bruce Lanphear, which combined the raw data from seven prospective cohort studies rather than averaging their published conclusions. Across an increase in blood lead from roughly 2.4 to 30 micrograms per decilitre, it estimated a loss of about 6.9 IQ points, with a confidence interval running from around 4 to 9 points.

Two things about that figure matter more than the figure itself. The first is the shape: the fitted curve is supralinear, meaning the slope is steepest where exposure is lowest. The analysis estimated a loss of roughly 3.9 points across the first stretch — from about 2.4 up to 10 micrograms per decilitre — and less than that across the whole remaining twenty. A child moving from very low to moderately low exposure loses more per unit than a child moving from high to very high.

The second is that this is an average across a population, not a prediction about a person. Four to seven points is a fraction of the ordinary spread of scores, and it sits well inside the measurement error of a single test session. No individual result can be attributed to lead. What the number does describe is what happens to a whole distribution when an entire birth cohort is exposed — and that is a very different quantity, as the next section shows.

The natural experiment nobody designed

Tetraethyl lead was added to petrol from the 1920s and phased out across most of the world between the mid-1970s and the 1990s. In the United States, average blood lead in young children fell from around 15 micrograms per decilitre in the late 1970s to below one today. That is a change of more than ninety per cent, applied to an entire population, over a period short enough to measure.

Applying the pooled dose-response curve to a shift of that size gives an expected gain of several IQ points at the population level, and a much larger proportional change at the tails: shifting a whole distribution upward by even three or four points substantially increases the number of people above any high threshold and reduces the number below any low one. That is the sense in which a small average effect can be a large public health effect.

How much of the twentieth-century rise in raw test scores this explains is genuinely contested. Scores were already climbing before leaded petrol was withdrawn, and the rise is measured across countries with very different exposure histories, so lead is at best one contributor among several — alongside nutrition, schooling and test familiarity. The wider argument about why norms drift is covered in why IQ norms expire. Treat lead as a demonstrated mechanism of the right sign and plausible size, not as the explanation.

Chart showing the supralinear relationship between childhood blood lead concentration and IQ score, with the steepest loss occurring across the lowest range of exposure rather than the highest
Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now! →

Secure & encryptedInstant results10–20 minutes

Air pollution and the other exposures

Lead is the exposure with the strongest evidence, not the only one ever studied. Fine particulate matter, prenatal exposure to certain organophosphate pesticides, and manganese in drinking water have all been linked to lower scores on cognitive tests in children. The findings are real enough to take seriously and much weaker than the lead literature, for a reason worth understanding.

  • Confounding is severe. Polluted air, older housing and low household income travel together. Separating the exposure from everything else that accompanies it is far harder than for lead, where blood concentration can be measured directly in each child.
  • The designs are mostly observational. Almost none of this evidence comes from anything resembling a randomised comparison, and where quasi-experimental designs exist the estimates usually shrink.
  • Effect sizes are smaller and less consistent. Where lead studies converge on a similar slope across countries and decades, the pollution literature does not yet converge in the same way.

The honest summary is that lead is established, and the rest is suggestive. That distinction gets lost when all of it is reported as “pollution lowers IQ”, and losing it makes the strong finding look as arguable as the weak ones.

What this does not tell you about your own score

If you have just taken a test and are wondering whether an exposure explains your result, the answer is almost certainly no, for three separate reasons.

  • The window has closed. The effect is developmental. Adult exposure at ordinary environmental levels does not produce the same deficits, because the processes it disrupts have finished.
  • The effect is smaller than the noise. A few points sit inside the confidence interval of any single administration. Reading a personal history out of one score is not something the measurement supports — see how to read an IQ test report for what the interval around a score actually means.
  • Nothing on a test detects it. There is no subtest, index or profile shape that identifies an exposure history. A blood test measures lead; a cognitive test does not.

The useful reading runs the other way. This is one of the few places where the research supports a concrete action — not for the person taking the test, but for a child who has not been exposed yet. It also belongs to a small group of factors that genuinely move population-level scores, alongside the nutritional deficiencies covered in nutrition and IQ. Most of what gets sold as a way to raise intelligence does not belong in that group at all.

Where this sits in the wider picture

Debates about intelligence tend to be framed as heredity against environment, as though a finding on one side subtracts from the other. Lead is a clean illustration of why that framing fails. Heritability estimates are computed within a population at a given time, and they say nothing about what a change in conditions would do — a point set out in is IQ genetic. A population can have high heritability for a trait and still shift substantially when a specific environmental insult is removed from everybody. That is roughly what happened.

It also sets a realistic bar for every other environmental claim. Lead has a measurable dose in each individual, a plausible biological mechanism, a consistent slope across countries, a dose-response relationship, and a population-scale removal that went the predicted way. When something else is described as changing intelligence, that is the standard of evidence worth asking for. Most candidates meet almost none of it — and the general list of things that shift a result on the day is covered in what affects IQ test results.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged air pollution, blood lead, cognitive development, environmental toxins, Flynn Effect, heritability of iq, intelligence test, IQ Science, IQ Score, iq testing, lead exposure, nature vs nurture