IQ Metrics
IIF Certified Assessment Start IQ Test
IIF Certified Assessment

High-IQ Societies Explained

Scores & Scales

Beyond Mensa: How Triple Nine, Prometheus and Other High-IQ Societies Work

Mensa is the famous one, but it is nowhere near the most exclusive. The Triple Nine Society admits one person in a thousand; the Prometheus Society, one in thirty thousand. Here is how each threshold is actually set, what test you would need, and why the further out you go, the less any single number can be trusted.
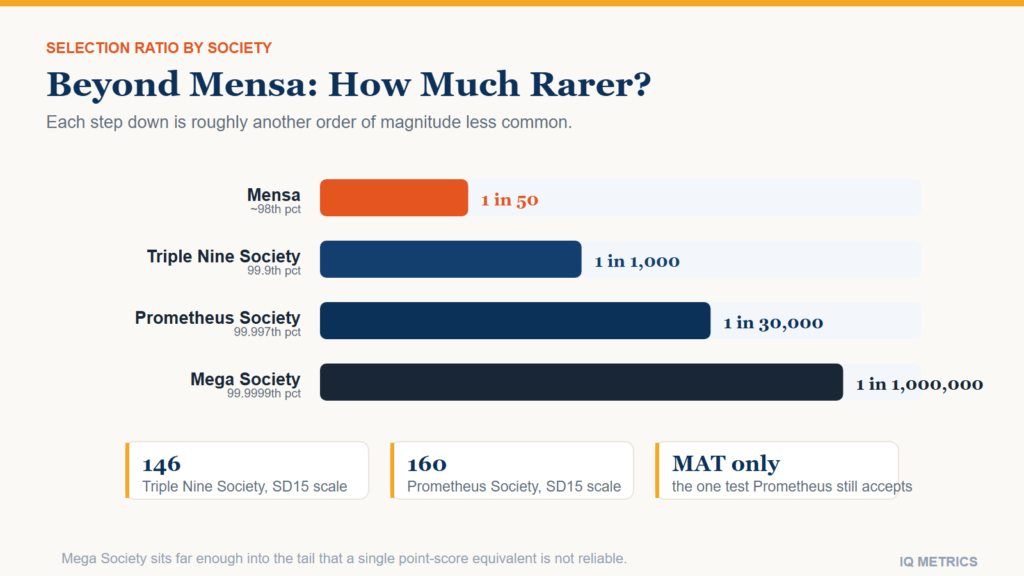
Bar chart comparing the rarity of Mensa, Triple Nine Society, Prometheus Society, and Mega Society admission thresholds, from 1 in 50 up to 1 in 1,000,000 of the population

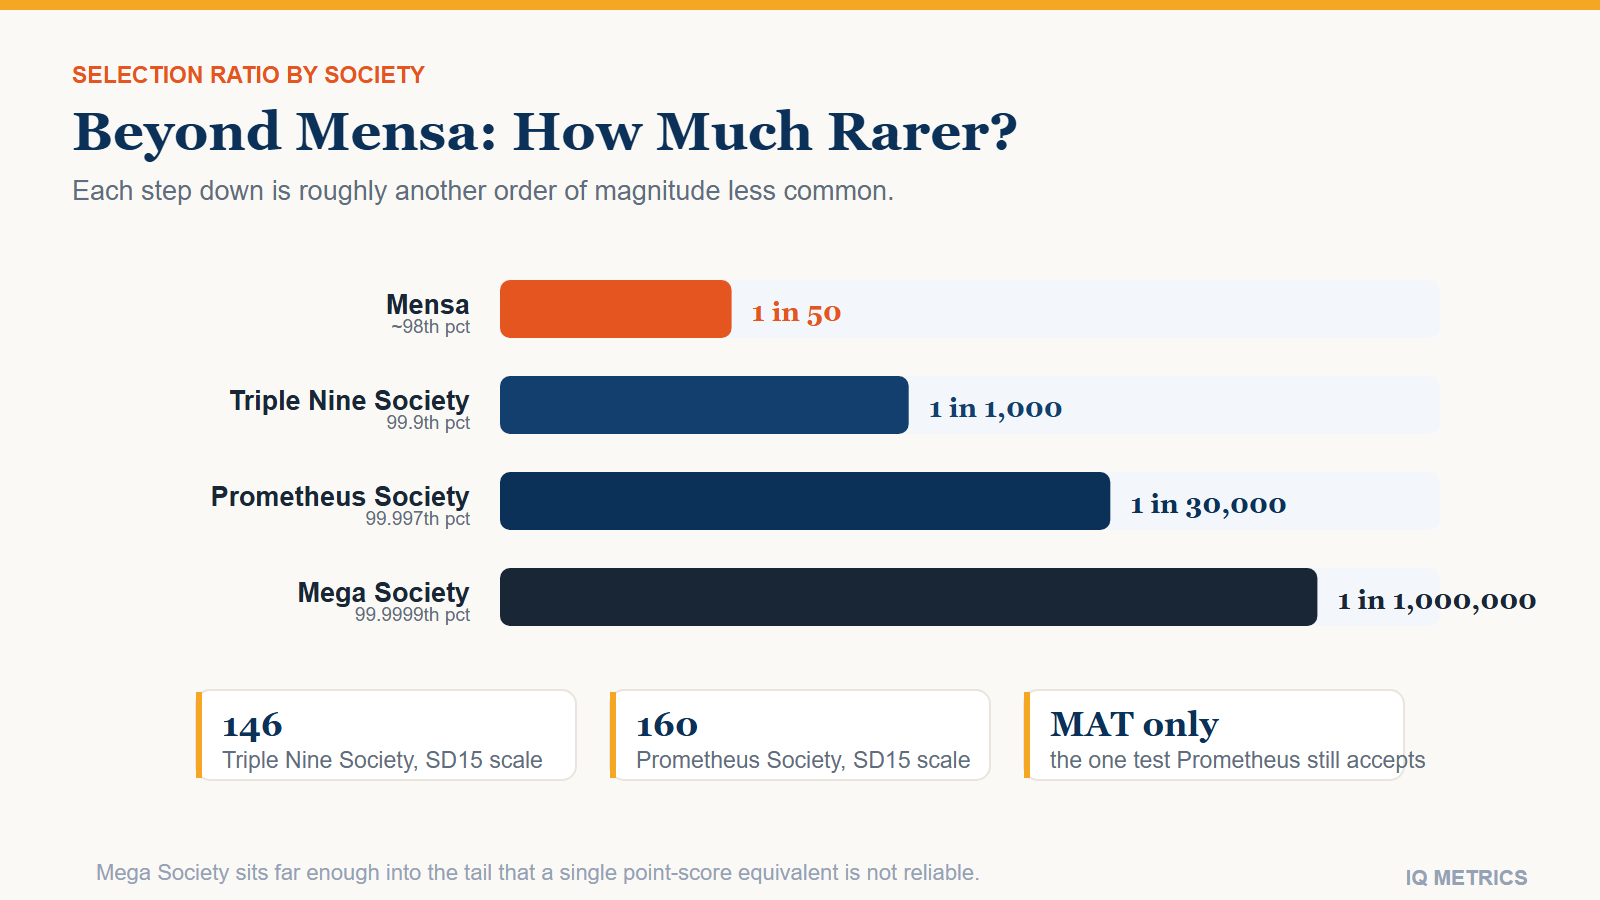
Several societies do, and by a wide margin. Mensa’s well-known threshold is the 98th percentile — the top 2 percent of the population. The Triple Nine Society sets its bar at the 99.9th percentile, roughly one person in a thousand. The Prometheus Society goes further still, to the 99.997th percentile, about one in 30,000, and the Mega Society further still beyond that. Each step down this list is a real, order-of-magnitude jump in rarity rather than a marginal increment, and each society comes with its own quirks about which tests actually qualify a candidate for membership.

The further out this list goes, though, the shakier the underlying numbers get — not because anyone is being dishonest, but because of a limit this site has covered before: no test can reliably measure a score that rare. Every society here uses the exact same 98th-percentile logic Mensa does; what changes from one to the next is simply how far right on the curve the cut-off sits, and how much less trustworthy that cut-off becomes the further right you go.

Mensa’s threshold, as a baseline

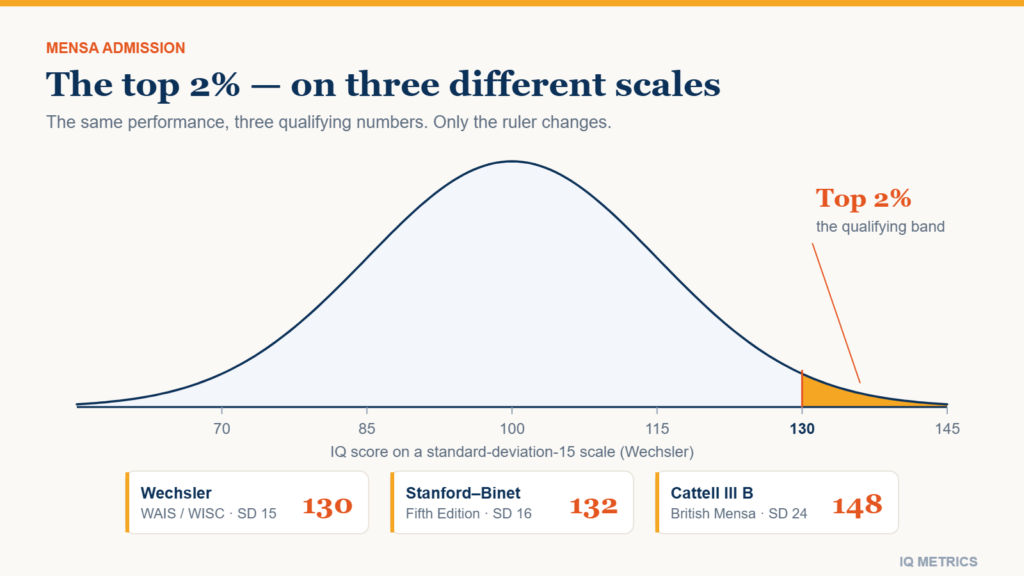
Mensa requires the 98th percentile on an approved, supervised test of intelligence — nothing else about age, education or background counts. On the SD15 scale most modern tests use, that works out to just under 130; this site’s full breakdown of that number, and why different publishers report it as 130 or 132 covers the derivation in detail and is not repeated here. What matters for the rest of this article is the baseline: everything that follows is progressively rarer than the one high-IQ society most people have actually heard of.

Triple Nine Society: one in a thousand

The Triple Nine Society takes its name from its threshold: "999" for the 99.9th percentile, about one person in a thousand. On the SD15 scale that is 146; on SD16, 149. It accepts scores from a wide range of standardized intelligence and academic-aptitude tests — over twenty of them — which makes it considerably more accessible than either of the two societies further down this list. Not easy: a 1-in-1,000 score is still rare enough that the overwhelming majority of people who sit a standard test will never see one on their own report, no matter how well they happen to do. But it is reachable through an ordinary supervised assessment, the same kind of test a school, clinic or employer might administer, rather than a specialist instrument built specifically to chase a rarer tail of the distribution.

Prometheus Society: one in thirty thousand

The Prometheus Society sets its bar at the 99.997th percentile — 160 on the SD15 scale, 164 on SD16, and roughly one person in 30,000. Here the practical requirements change in a way that is worth understanding rather than just noting: as of today, the society accepts essentially only the Miller Analogies Test (MAT) for qualification. That is not an arbitrary rule. Most standardized IQ tests simply are not built with enough discriminating power that far out in the distribution to certify a score that rare in the first place — which is the same ceiling problem covered in detail in why no IQ test can reliably score you above about 160.
Bar chart comparing the rarity of Mensa, Triple Nine Society, Prometheus Society, and Mega Society admission thresholds, from 1 in 50 up to 1 in 1,000,000 of the population
Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

Mega Society: one in a million, and a cautionary history

The Mega Society sits past Prometheus again, at the 99.9999th percentile — about one person in a million. Founded in 1982 by Ronald K. Hoeflin, it is a useful case study in what goes wrong at this level of rarity, and it is not merely a matter of statistics. Hoeflin’s own qualifying instrument, the Mega Test, ran unsupervised and untimed in Omni magazine in 1985 — anyone could take it at home, on paper, at their own pace. That design made sense for reaching a geographically scattered population of extremely rare scorers, and it was also its downfall: once enough people had discussed the questions and shared answers, later scores stopped meaning what earlier ones had. The society stopped accepting Mega Test scores from after 1994, and a successor instrument, the Titan Test, was eventually retired for the same reason in 2020.

That history matters beyond one society’s administrative footnote: it is a second, independent reason — alongside the statistical extrapolation problem below — that scores this far into the tail are hard to trust at face value. A test rare and specialised enough to target one-in-a-million scorers is also, almost by construction, too small and too specialised in its niche to be administered under the same tightly controlled, regularly re-normed conditions as a mainstream instrument like the WAIS.

Why the numbers get shakier as the club gets more exclusive

This is the important part, and it follows directly from that ceiling-effect article: a standardisation sample for a major test typically runs into the low thousands of people. That is plenty to characterise the middle of the distribution precisely, and it is nowhere near enough to empirically verify what a 1-in-30,000 or 1-in-a-million score should actually look like. Past a certain point, a test manual is extrapolating the shape of a curve outward from data it does not really have, not reading a measurement off a ruler. That is exactly why the Mega Society, at the 99.9999th percentile — one person in a million — is not given a specific point-score equivalent here. Past a certain rarity, a single number claims a precision the underlying test data cannot support.

What these societies actually do

Beyond the admission threshold, the day-to-day reality of Triple Nine, Prometheus and similar societies looks a lot like Mensa’s: member newsletters, online discussion groups, occasional in-person meetups, and special-interest groups built around members’ other hobbies. The exclusivity is entirely in the door, not in what happens after you are through it — joining one of these does not unlock anything functionally different from what Mensa already offers, just a smaller and more specifically selected room.

That is worth sitting with for a moment, because it cuts against the mystique these societies sometimes attract online. There is no secret curriculum, no exclusive research programme and no functional advantage to membership beyond the social one of meeting other people who cleared the same unusually high bar. For most people genuinely curious about their own score, an ordinary supervised test and a clear explanation of where the result sits on a standard scale will answer the actual question far more usefully than pursuing admission to any of these.

Should you try to qualify

If you are curious, the realistic first step is the same one either way: sit a properly normed, supervised test and see where you land, rather than assuming an online quiz score tells you anything about eligibility for any of these. A casual, ungraded online test is not accepted by any of these societies, and for the same reason it should not be treated as a real estimate of where you would land on one that is — the ceiling and norming problems described above apply just as much to an unverified quiz as they do to a specialist admission test, only with far less rigor behind the number it reports. And if you do not clear one of the higher bars, that is at least as likely to reflect the ceiling problem described above as it is to reflect anything meaningful about you — the tests that can distinguish the 98th percentile reliably were mostly never built to distinguish the 99.997th. Worth remembering, too: none of this measures the kind of skill covered in this site’s piece on memory versus IQ — these thresholds are about reasoning under test conditions, not how much you can memorize. For your own number, on a test that reports the scale, percentile and confidence range together rather than a bare figure, start here.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged admission requirements, cut-off scores, extreme scores, gifted, high iq societies, iq percentile, iq scale, IQ Science, mega society, mensa, prometheus society, rare scores, standard deviation, triple nine society

Memory and IQ

Understanding IQ

Does a Great Memory Mean You’re Smart? Memory and IQ, Explained

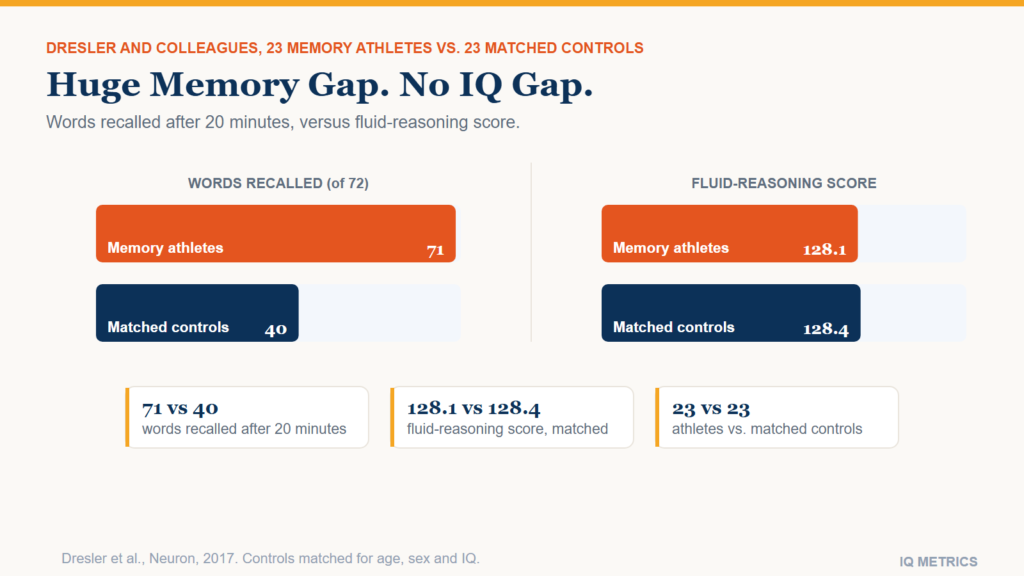
The world’s best memory athletes can memorize 71 shuffled words in twenty minutes. Their IQ scores are not measurably different from a matched control group who could only manage 40. If a spectacular memory is not the same thing as a high IQ, what actually is the difference?
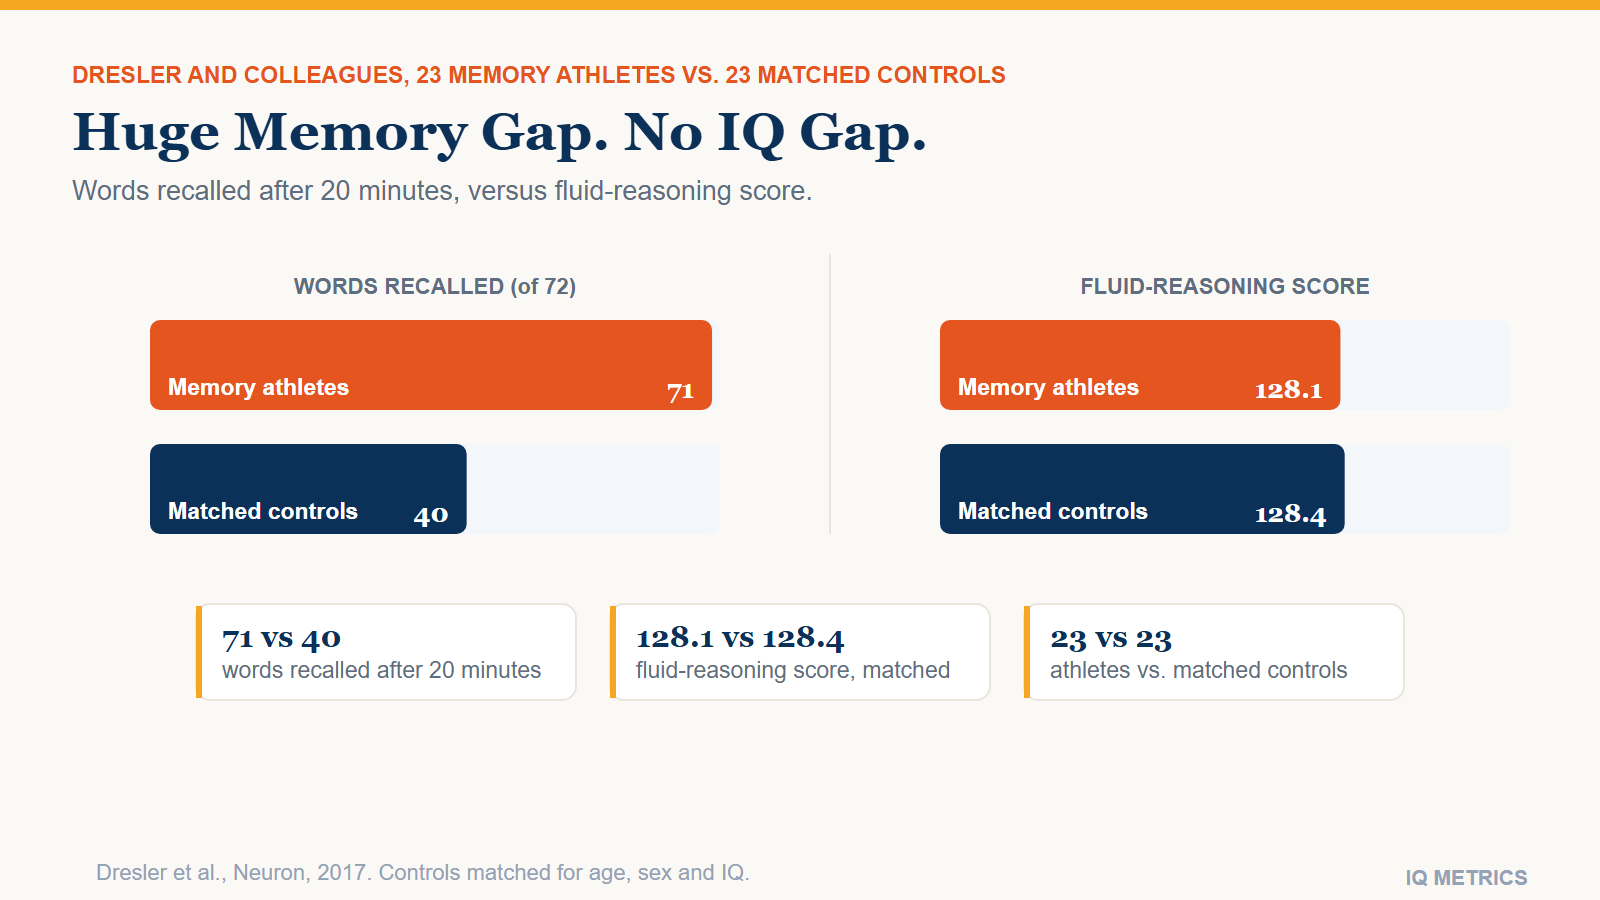
Two-panel bar chart comparing memory athletes and matched controls: 71 versus 40 words recalled after 20 minutes, but nearly identical fluid-reasoning scores of 128.1 versus 128.4

Not especially, no — and the cleanest evidence for that comes from a study that took the question as literally as possible. Researchers recruited 23 of the world’s top memory athletes, people who can memorize a shuffled deck of cards in under a minute, and compared them against 23 ordinary people matched for age, sex and IQ. On memory tasks, the athletes were not close — they recalled 71 of 72 words after a 20-minute delay against 40 for the controls. On a standard measure of fluid reasoning, the two groups scored 128.1 and 128.4. Statistically indistinguishable.

That gap between a massive skill difference and a nonexistent IQ difference is the whole story here, and it says something specific about what IQ tests measure that most people get wrong on their own — including, often, people who assume a sharp memory for names, dates or trivia is itself a sign of a high IQ.

The study that tested this directly

Dresler and colleagues, publishing in the journal Neuron in 2017, gathered 23 of the world’s top-50-ranked competitive memorizers and compared them, brain scans included, against 23 controls deliberately matched for age, sex, handedness and IQ — recruited partly from Mensa and academic-foundation mailing lists specifically so the comparison group would already be drawn from a high-functioning population, not an average one. That design choice matters: it means this study cannot tell you whether memory athletes outscore the general population on IQ (they likely do, since both groups here were well above average). It can tell you something more useful — whether the specific skill of extreme memorization tracks with reasoning ability even among people who already reason well. It does not.

Competitive memory itself is a real, standardized sport with its own disciplines: memorizing the order of a shuffled deck of playing cards as fast as possible, recalling long strings of random binary digits, matching dozens of unfamiliar faces to names seen once, and reciting memorized decimal digits of pi. None of these events resemble an IQ test’s matrix-reasoning or analogy items even slightly — they reward a specific, trainable encoding skill applied to arbitrary material, not the ability to spot a novel pattern you have never been drilled on.

A huge gap on one measure, none on the other

After studying a list of 72 words for a fixed period, memory athletes recalled an average of 71 of them 20 minutes later. Matched controls recalled 40 — a real skill, just not a remotely comparable one. On the fluid-reasoning measure, though, the two groups landed at 128.1 and 128.4 respectively, a difference small enough to be noise. The athletes were dramatically better at one very specific thing and not measurably better at the kind of on-the-spot problem-solving an IQ test is built to capture.

Two-panel bar chart comparing memory athletes and matched controls: 71 versus 40 words recalled after 20 minutes, but nearly identical fluid-reasoning scores of 128.1 versus 128.4

What made the athletes better, if not IQ

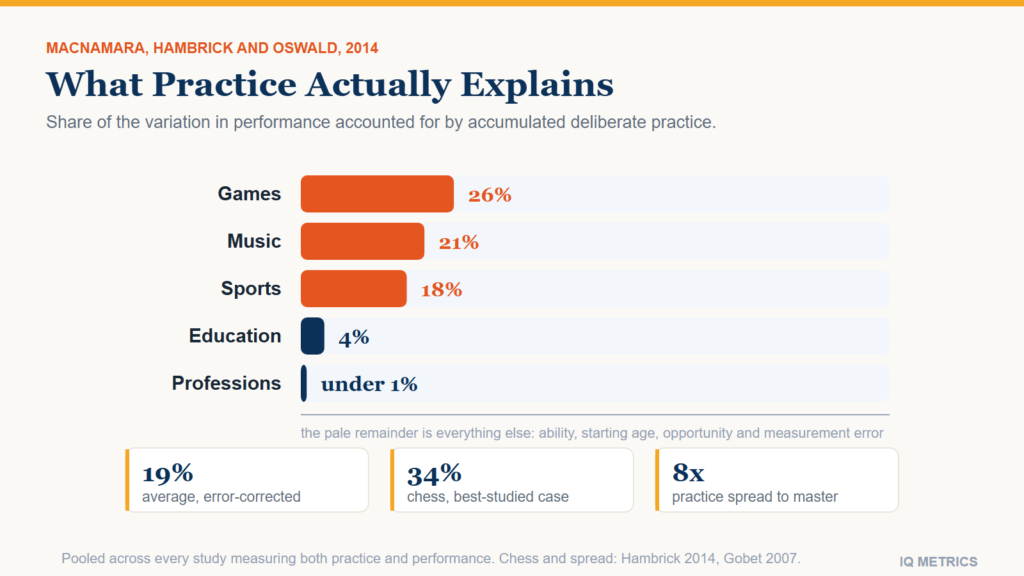
Brain imaging pointed to connectivity, not raw processing power: memory athletes showed stronger functional connections between brain networks involved in memory and in visual processing, consistent with the technique nearly every competitive memorizer uses, the method of loci — mentally placing items to be remembered along a familiar route and "walking" that route to retrieve them. The most striking part of the study is what happened when naive controls were taught this technique and given six weeks to practise: many approached the athletes’ recall performance, closing a gap that had looked biological. That result belongs to a pattern seen again and again across skill research, and this site has covered it before — see how much of expert performance generally comes down to technique and deliberate practice rather than a fixed, innate ceiling.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

Does training your memory make you smarter

This study is also a useful, if indirect, data point against a much broader claim: that training one narrow cognitive skill hard enough produces general gains in intelligence. The memory athletes in this study have trained one specific skill for years, often at a serious competitive level, and it produced exactly the outcome you would predict if training were narrow rather than general — a huge improvement on the trained skill and no detectable improvement on fluid reasoning. Commercial "brain training" programmes make a version of the opposite promise, and the research on whether narrow drills transfer to general intelligence is genuinely mixed at best; this study is a fairly clean illustration of why skepticism is the reasonable default position to start from.

Why IQ tests barely touch this kind of memory

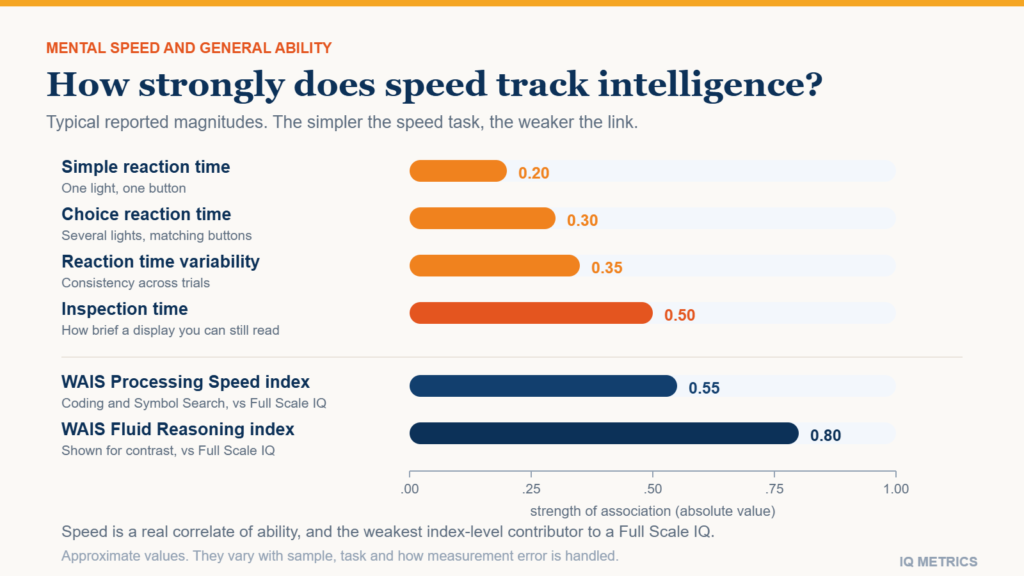
IQ tests do include a memory component, but it is a narrower one than most people picture: working memory, typically tested with tasks like repeating a string of digits forwards and then backwards, or holding a small amount of information in mind while manipulating it. That is genuinely a different cognitive skill from what a memory athlete trains, which is long-term, associative memory for large amounts of arbitrary material — a skill IQ tests were never designed to assess, because it responds so strongly to technique and practice rather than to the kind of novel, on-the-spot reasoning the tests are built around. For more on why even working memory itself is not the same thing as reasoning, see this site’s companion piece on the news desk, and for the IQ-test component that measures how fast you process information rather than how much you can hold, see processing speed and IQ.

The everyday version of this confusion

The same mix-up shows up outside competitive memorizing. "Photographic memory" as popularly imagined — a perfect, effortless mental snapshot of anything seen once — has never been reliably documented in a controlled study of an adult. What looks like it in daily life is usually domain-specific expertise: chess masters can reconstruct a mid-game board position from a glance not because their memory is generically superior, but because years of practice let them recognize and "chunk" familiar patterns instead of memorizing 32 pieces one at a time. This was demonstrated decades earlier, well before the memory-athlete study, in a classic experiment by Chase and Simon: put those same chess masters in front of a board with pieces placed randomly, in configurations that never occur in real play, and their recall advantage over a novice mostly disappears — because there are no real game patterns left to recognize. The skill was pattern recognition trained on a specific domain, not raw memory capacity, and it evaporates the moment the domain-specific structure is removed. The same logic applies to a memory athlete: ask one to recall a list of 72 unrelated, un-memorable historical dates instead of 72 concrete words their method of loci was built to handle, and the advantage would very plausibly shrink for exactly the same underlying reason.

None of this is a knock on the athletes. Encoding 72 words in a way that survives 20 minutes is a genuinely difficult, learnable skill, and they are simply better at it than almost anyone alive.

What this means if you are prepping for an IQ test

Mnemonic tricks are worth learning for their own sake, but they will not meaningfully move a real IQ test score, because the tests are deliberately built around novel problems you have not seen before and cannot pre-memorize a solution to. A digit-span task, which does appear on most IQ tests as part of the working-memory component, is one of the few places a memorized technique could theoretically help a little — but it is a small slice of the overall score, and the matrix-reasoning and verbal-analogy sections that carry most of the weight are immune to memorization by design. For what actually helps in the days before sitting one, see this site’s guide to preparing for an IQ test. And if raw memory is not what separates an ordinary score from an exceptional one, the next question is what does — which is exactly where the numbers get genuinely interesting: at the far, rarely-discussed end of the scale, covered in a look at what sits above Mensa.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged brain training, cognitive ability, fluid intelligence, general intelligence, intelligence testing, iq myths, IQ Science, memory, memory athletes, memory champions, memory techniques, method of loci, mnemonics, Working Memory

Preschool and IQ

Research & Evidence

Does Preschool Raise a Child’s IQ? What the Perry Project Found

The most famous experiment in early-childhood education raised participants’ IQ scores by as much as 13 points — then watched that advantage shrink to almost nothing within a few years. Their income, education and arrest records stayed different for the rest of their lives. Why would outcomes outlast the score that supposedly predicts them?

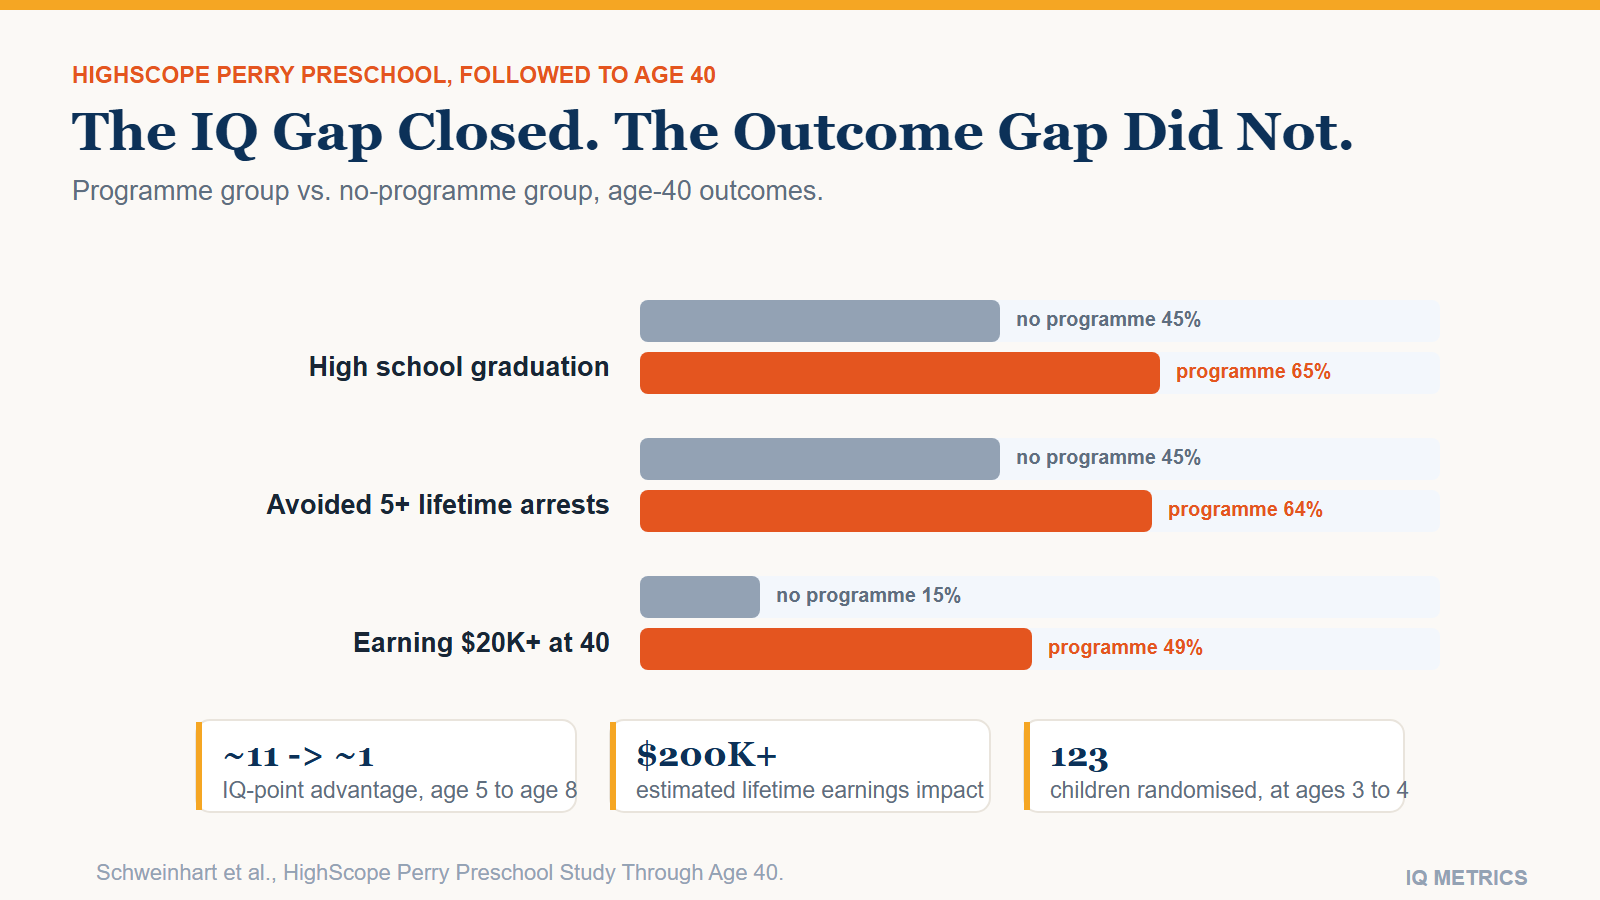
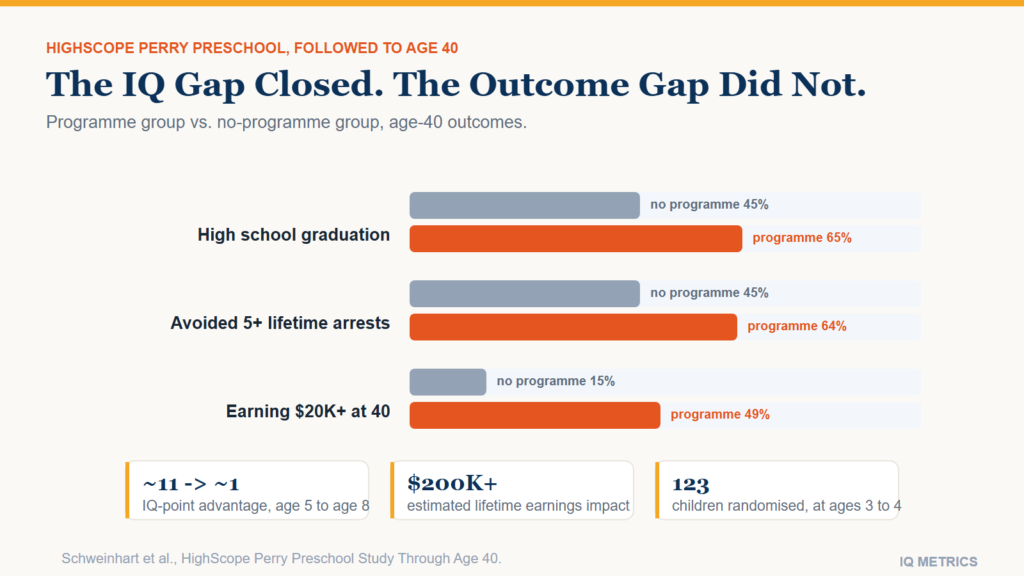
Bar chart comparing Perry Preschool program and no-program groups at age 40: 65 versus 45 percent high school graduation, 64 versus 45 percent avoiding five or more arrests, and 49 versus 15 percent earning over 20,000 dollars, despite the early IQ advantage fading by age eight

Yes, in the short term, and the size of that boost has been measured about as rigorously as anything in this field: a randomized trial that raised participants’ IQ scores by roughly 13 points. The complication is what happened next. Within a few years the IQ advantage had shrunk to almost nothing. What did not shrink was everything the IQ score was supposedly there to predict.

That combination — the measurable thing fading while the outcomes it was supposed to forecast kept diverging for decades — is the most-cited puzzle in early-childhood research, and it changes what a preschool IQ study can actually tell you. It also means the honest answer to "does preschool raise IQ" depends entirely on which year you ask the question, which is not the kind of nuance that fits in a single headline number.

The experiment that settled the design question

The HighScope Perry Preschool Study began in 1962 in Ypsilanti, Michigan, with 123 children living in poverty, ages 3 and 4, individually assigned to either a high-quality preschool programme or no preschool at all — not assigned by classroom or neighbourhood, which is what makes the results a genuine causal estimate rather than a comparison of whoever happened to enroll. Researchers then did something almost nobody else in this field has managed: they kept following the same 123 people all the way to age 40.

What the programme actually consisted of

It was not a light touch. Children attended a daily 2.5-hour classroom session every weekday morning, taught by certified public-school teachers holding at least a bachelor’s degree, at an unusually low child-to-teacher ratio of about 6 to 1. The classroom followed what became the HighScope curriculum’s "plan-do-review" routine: children planned an activity, carried it out, then reviewed what happened, rather than sitting through passive instruction. Teachers also made a 1.5-hour home visit to each family every week, working directly with mothers on extending the same activities at home. That combination of classroom intensity, low ratios, a specific pedagogy, and weekly direct parent involvement is a considerably heavier intervention than what most children who attend some form of preschool today actually receive, which matters for how far the results can be expected to generalise.

The IQ boost, and how fast it faded

At age 5, right after the programme ended, the treatment group’s IQ advantage measured about 0.75 standard deviations — on some analyses as much as 13 points, a large effect by any standard in psychology. By age 8, that gap had shrunk to roughly 0.08 standard deviations, about a single point, and was no longer statistically distinguishable from zero. The children who attended preschool were, by nearly any IQ test given in elementary school, no longer measurably different from the children who had not.

Bar chart comparing Perry Preschool program and no-program groups at age 40: 65 versus 45 percent high school graduation, 64 versus 45 percent avoiding five or more arrests, and 49 versus 15 percent earning over 20,000 dollars, despite the early IQ advantage fading by age eight

The outcomes that did not fade

Here is where the study becomes genuinely strange if you expect IQ to be doing the predictive work. Followed to age 40, the preschool group graduated high school at 65 percent versus 45 percent for the no-preschool group. They were arrested five or more times over their lives at 36 percent versus 55 percent. They were earning $20,000 or more annually at 49 percent versus 15 percent. Researchers estimate the programme’s impact on lifetime earnings at upward of $200,000 per participant. Every one of those gaps persisted for decades after the IQ gap that supposedly explained early advantage had already closed in elementary school.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

Why would outcomes outlast the IQ boost

The leading explanation is not that the IQ tests were wrong, but that IQ was never the actual mechanism of benefit — it was just the easiest thing to measure early. The economist James Heckman and colleagues, reanalyzing this same dataset, argue the programme’s lasting effect ran mainly through non-cognitive skills: self-control, sustained attention, motivation and the ability to work with other children — skills that do not show up on an IQ test at all but that plausibly shape whether a teenager stays in school or a young adult keeps a job. A more recent reanalysis (Garcia, Heckman and colleagues, 2025) goes further, arguing some of the apparent cognitive fadeout was itself a measurement artefact of how later tests were scored, and that real cognitive gains persisted further into adulthood than the original age-8 result suggested. That reanalysis is contested, not settled — but even by the original, more conservative reading, the outcome gap needs an explanation that is not simply "the IQ gap stayed open."

One further piece of evidence favours the soft-skills reading over a purely cognitive one: through elementary and middle school, years after the IQ gap itself had closed, the preschool group was still less likely to be placed in special education and less likely to be held back a grade than the no-preschool group. If the programme’s only lasting effect had been cognitive, those school-progress differences should have closed on the same schedule as the IQ scores. They did not, which is exactly the pattern you would expect if the programme had changed something more durable than a test score — how a child navigated a classroom, not just how they scored on one test.

Head Start’s larger, messier evidence

Perry Preschool is a single, small, unusually intensive programme from the 1960s, run at a scale and cost per child that no national system has matched, and its dramatic numbers do not automatically generalize to preschool at national scale. Head Start, the actual federal early-childhood programme serving over a million American children a year, has been studied far more broadly, and its own large-scale evaluation (the national Head Start Impact Study) found a similar shape — an early cognitive boost that fades within a few years of school entry — but with smaller, more debated effects on later life outcomes than Perry’s striking numbers. The honest summary is that intensive, well-resourced early intervention for children in poverty has a real and reasonably well-established effect on adult outcomes; exactly how large that effect is at the scale of an ordinary national programme is a genuinely open, actively studied question, not a settled multiple of the Perry numbers.

How this differs from does school raise IQ

This is a narrower question than whether ordinary schooling raises IQ across the school years, which looks at the general K-12 population. This article is scoped specifically to targeted early-childhood interventions for children growing up in poverty, where the comparison is not "more school versus less school" but "an intensive structured programme versus none, before age 5." The two questions share a family resemblance and not much more.

It also rhymes, more than coincidentally, with the one randomized trial on breastfeeding and IQ: another case where a real, causally established early cognitive advantage shrinks well before adulthood. The through-line in both is the same caution — an IQ score measured in early childhood is a snapshot of that moment, not a fixed prediction of the adult the child will become.

What this means, and does not mean

None of this makes IQ scores meaningless, and it does not mean preschool is pointless — if anything, Perry Preschool is some of the strongest causal evidence available that early intervention for children growing up in poverty changes the trajectory of a life. What it means is narrower and more useful: a single IQ number, especially one measured in early childhood, is an incomplete predictor of how a life turns out, because plenty of what shapes an adult outcome was never going to show up on that test in the first place.

It is also a useful corrective for reading any "programme X raised IQ by Y points" headline, in education research or anywhere else: ask what happened to that gap five years later before deciding how much weight it deserves. Sometimes, as with Perry Preschool, the score itself was never really the point.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged cognitive development, early childhood education, early intervention, head start, HighScope, iq fadeout effect, IQ Science, longitudinal study, Perry Preschool, poverty and iq, preschool, randomized trial, school readiness, Socioeconomic Status

Breastfeeding and IQ

Research & Evidence

Breastfeeding and IQ: What the Only Randomized Trial Found

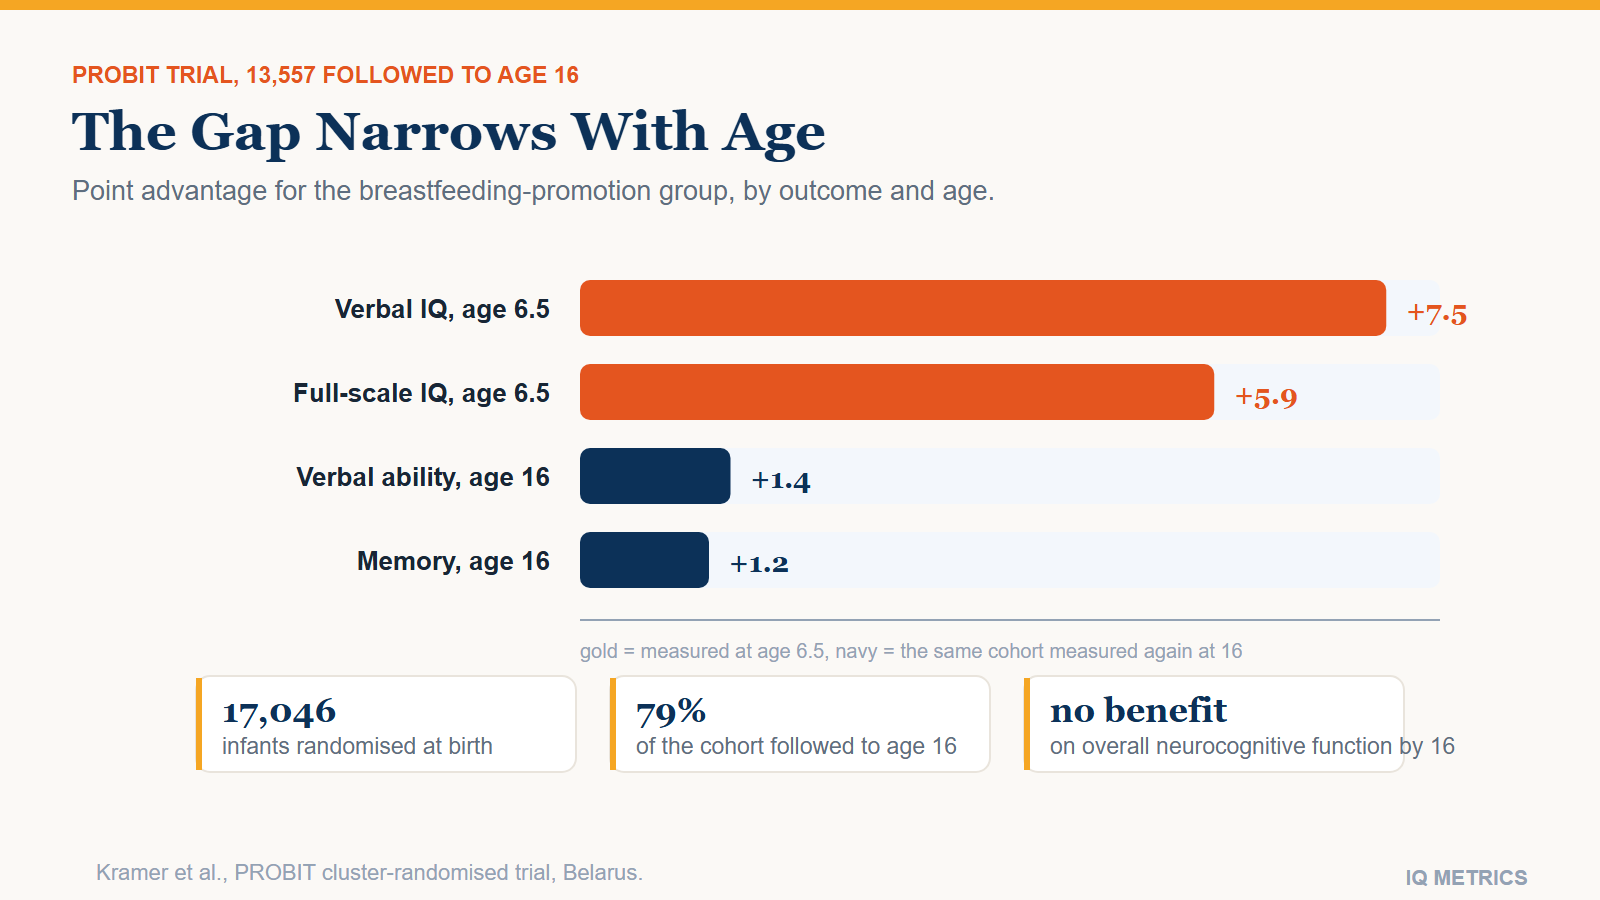
The largest randomized trial ever run on breastfeeding found a genuine IQ advantage at age six — about six points on full-scale IQ. By age sixteen, the gap on most measures had shrunk close to zero. Here is what the trial actually measured, and why it still beats every observational study that came before it.

Bar chart showing the breastfeeding-promotion group's IQ advantage shrinking from 7.5 points in verbal IQ and 5.9 points in full-scale IQ at age 6.5 to 1.4 and 1.2 points by age 16, from the PROBIT randomized trial

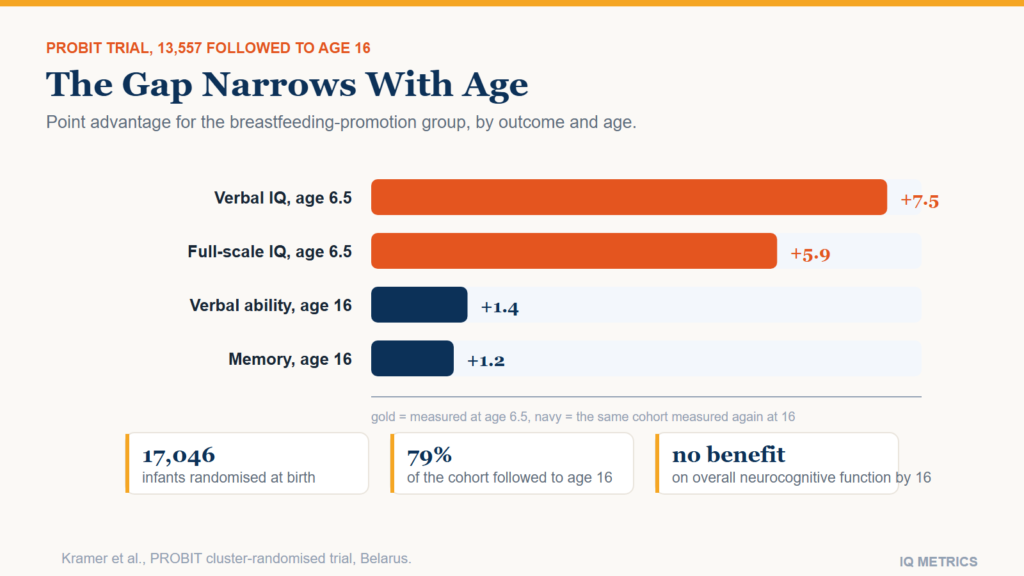
A little, and mostly early. The best evidence comes from a single randomized trial in Belarus that followed 17,046 infants from birth: at age 6.5 the breastfeeding-promotion group scored about 6 points higher on full-scale IQ and 7.5 points higher on verbal IQ. By age 16, most of that gap had narrowed to somewhere between nothing and a point and a half, depending which measure you look at.

That shrinking pattern is not a flaw in the study. It is the most informative part of it, and it is the reason this article leads with a single randomized trial most people have never heard of, rather than the much larger pile of observational studies on breastfeeding and IQ that came before it and that this trial was specifically designed to improve on.

Why this question needed a randomized trial

You cannot ethically assign babies to be breastfed or formula-fed, so almost every study on this topic before the 1990s was observational: researchers compared children whose mothers happened to breastfeed against children whose mothers happened not to, and measured IQ later. The problem is obvious once you say it plainly — mothers who breastfeed for longer tend, on average, to have more education, higher incomes and higher IQ scores themselves, all of which independently predict a child’s IQ. An observational study cannot cleanly separate "breastfeeding raised this child’s IQ" from "the kind of mother who breastfeeds also tends to have a smarter child regardless."

This is not a small confound to wave away. Maternal education and IQ are among the strongest known predictors of a child’s own IQ, and breastfeeding rates and duration both rise steeply with maternal education across almost every population they have been measured in. An observational study that does not fully strip that relationship back out is, in effect, partly measuring maternal IQ and reporting it as a breastfeeding effect.

The Promotion of Breastfeeding Intervention Trial (PROBIT) solved this the only ethical way available: it randomized the promotion, not the milk. Thirty-one maternity hospitals and clinics across Belarus were randomly assigned to either adopt the WHO/UNICEF Baby-Friendly Hospital practices, which substantially raise breastfeeding rates and duration, or continue standard care. Every mother still chose how she fed her own child. What the randomization controls for is everything else — the assigned hospitals and the control hospitals started with comparable populations, so any later difference in child outcomes is attributable to the intervention rather than to who chooses to breastfeed.

Concretely, the Baby-Friendly practices the intervention hospitals adopted included skin-to-skin contact and starting breastfeeding within an hour of birth, "rooming in" so infants stayed with their mothers rather than in a separate nursery, staff trained to help with common breastfeeding problems, and a shift away from routinely offering formula supplements without a medical reason. None of that is exotic or experimental — it is closer to ordinary good hospital practice today than it was in Belarus in the mid-1990s, which is part of why the trial could move breastfeeding rates by enough to detect an effect at all: infants at the intervention hospitals were breastfed more, and for longer, than infants at the control hospitals, even though no individual mother was assigned anything.

What the trial found at age 6

At the 6.5-year follow-up, children from the breastfeeding-promotion hospitals scored 7.5 points higher on verbal IQ (a real, statistically significant gap) and 5.9 points higher on full-scale IQ. The full-scale figure is worth a caveat the trial’s own authors flagged: its confidence interval technically touched zero, meaning it sits right at the edge of conventional statistical significance rather than comfortably past it. Performance IQ — the non-verbal half of the test — showed a smaller, clearly non-significant 2.9-point difference. Verbal ability carried almost the entire effect.

Bar chart showing the breastfeeding-promotion group's IQ advantage shrinking from 7.5 points in verbal IQ and 5.9 points in full-scale IQ at age 6.5 to 1.4 and 1.2 points by age 16, from the PROBIT randomized trial
Bar chart showing the breastfeeding-promotion group’s IQ advantage shrinking from 7.5 points in verbal IQ and 5.9 points in full-scale IQ at age 6.5 to 1.4 and 1.2 points by age 16, from the PROBIT randomized trial

The gap by adolescence

The same cohort was tracked down again at age 16 — 13,557 of the original 17,046 children, a 79.5 percent retention rate that is unusually high for a 16-year follow-up and a real strength of the trial. The headline result: "no benefit of a breastfeeding promotion intervention on overall neurocognitive function was observed." Two narrower measures still showed a small, statistically real gap — verbal function (+1.4 points) and memory (+1.2 points) — but both were well under a fifth the size of the verbal advantage measured a decade earlier.

A shrinking effect with age is exactly what you would expect if breastfeeding gives verbal development an early nudge that schooling, reading and everyday language exposure gradually swamp for everyone, breastfed or not. It is a considerably less dramatic story than the age-6.5 numbers alone would suggest, and a more honest one.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

Why a trial beats the studies it replaced

Here is the part that is easy to miss: PROBIT’s effect sizes are noticeably smaller than what many older observational studies reported, and that is a feature of the trial, not a weakness. Those larger observational estimates were almost certainly inflated by exactly the confound described above — maternal IQ and socioeconomic status riding along with the decision to breastfeed. When you randomize away that confound, the honest effect is real but modest, concentrated in verbal ability, and fades with age. That is a less exciting headline than "breastfeeding raises IQ by X points," and it is also much more likely to be true.

This same pattern — an early, measurable gap that narrows well before adulthood — shows up again in what randomized early-childhood programmes actually do to IQ scores, for a related but not identical reason: there, the IQ gap itself closes almost completely, while other outcomes that have nothing to do with an IQ number keep a real gap open for decades.

What might explain a real, if modest, effect

The leading biological candidate is the long-chain polyunsaturated fatty acids naturally present in breast milk — DHA in particular, which is a structural component of neural tissue and is added to many infant formulas precisely because of this hypothesis. Duration and exclusivity of breastfeeding also appear to matter in the literature more broadly, which is consistent with a dose-response biological mechanism rather than a purely social one. A competing, non-exclusive explanation is simply more one-on-one verbal interaction during feeding — breastfeeding sessions take longer than bottle-feeding on average, and the verbal advantage found in the trial, concentrated as it was rather than spread evenly across every cognitive domain, is at least as consistent with more talking and eye contact in infancy as it is with a nutrient in the milk itself. Neither explanation is settled with the same confidence as the trial’s headline numbers; both are plausible mechanisms behind them, not independently proven ones, and the trial itself was not designed to distinguish between them.

What this does not mean for any individual family

A population-average difference of a few IQ points, most of which narrows by adolescence, says essentially nothing about any single child. Formula-fed children are not destined toward a lower score — genetics, home language environment, broader nutrition and schooling all move the needle by more than this effect does, and countless people who were formula-fed as infants score well above average by any measure. A few IQ points at the population level, most of which narrows within a decade, is the kind of effect that shows up reliably only when you average across thousands of children — it disappears into the ordinary noise of one particular kid’s life, alongside sleep, illness, the specific school they attend and simple test-day variation. Breastfeeding also carries other, better-established maternal and infant health benefits that have nothing to do with IQ and are outside the scope of this article. If you are curious where your own score sits on a standard scale rather than a research statistic, the age-by-age IQ scale is the place to start.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged breastfeeding, causal evidence, child iq, cognitive development, early childhood development, infant feeding, infant nutrition, intelligence research, IQ Science, longitudinal study, nature versus nurture, PROBIT trial, randomized controlled trial, Verbal IQ

IQ Score Ceiling Effects

Scores & Scales

Why No IQ Test Can Reliably Score You Above 160

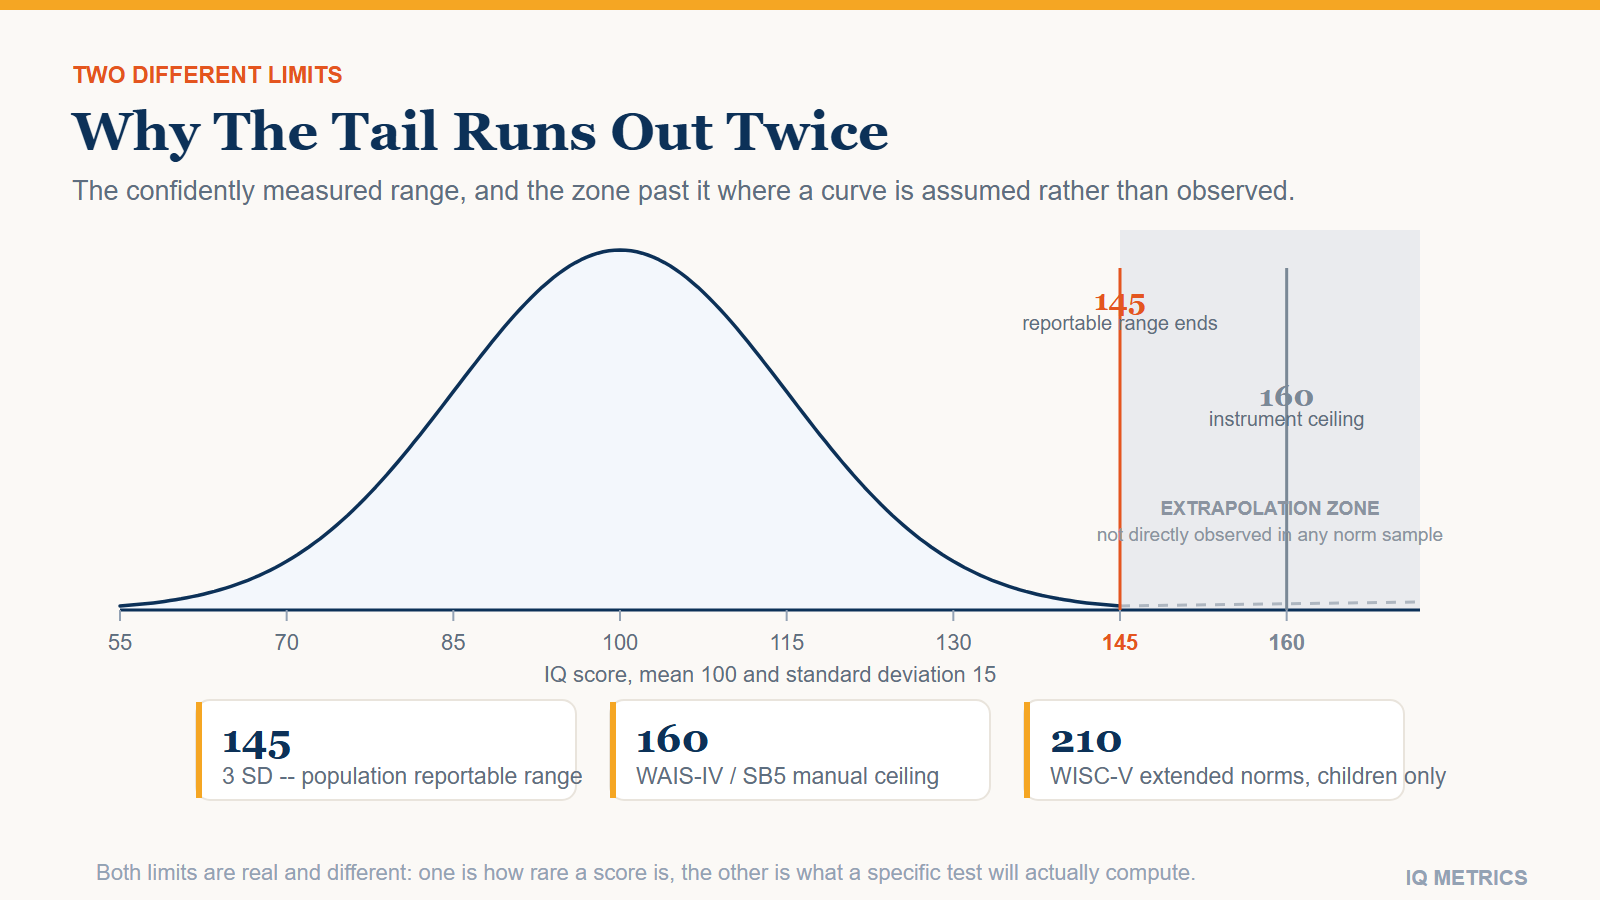
Two different numbers get used as "the top of the scale," 145 and 160, and they come from two different kinds of limit. One is a statement about population statistics; the other is about what a specific test manual will actually compute.
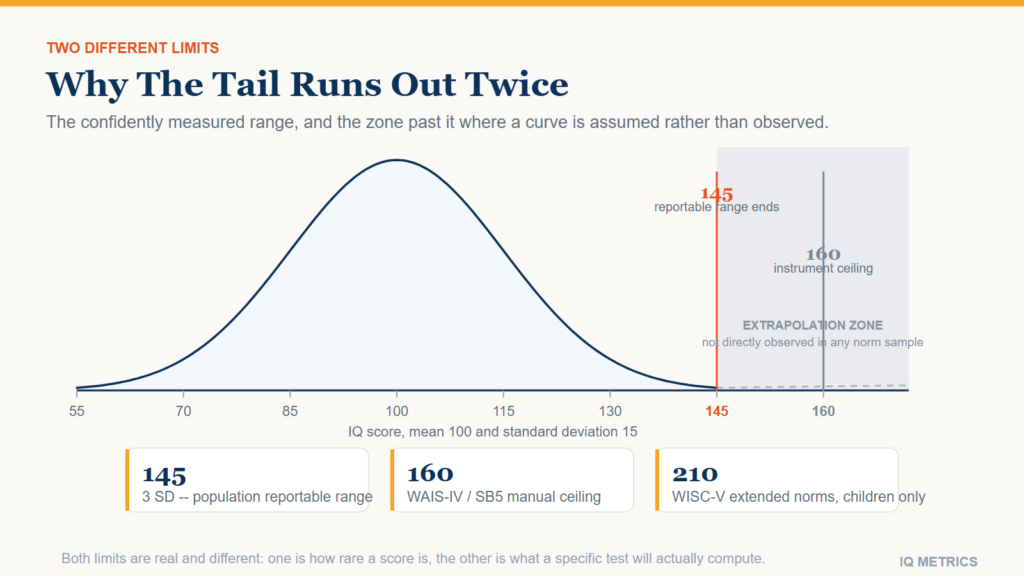
Bell curve chart of IQ scores with the population marked at 145, the three standard deviation boundary, and 160, the typical test ceiling, with the extrapolation zone beyond both shaded

No current IQ test can reliably score you above roughly 160, and the reasons split into two genuinely different limits that get conflated constantly. One is a statistical fact about how rare extreme scores are in any real population; the other is a mechanical fact about what a specific test’s norm tables will actually compute, regardless of population size. Knowing which one you are looking at changes what a very high number on a report should be taken to mean.

This site’s own breakdown of the IQ bell curve already states the first limit plainly: the reportable range runs out around 145, and anything past it is described there as extrapolation. What follows is the mechanism behind that statement, the second, different limit sitting behind the number 160, and how the two relate.

Two different numbers, two different reasons

145 is a population-statistics boundary. On the standard deviation-15 scale, 145 sits three standard deviations above the mean, the point past which roughly 99.7% of the population has already been accounted for. Above it, an individual score corresponds to a rarity — on the order of one person in several hundred to several thousand, and the exact percentile assigned that far out depends heavily on the precise shape assumed for the tail of the distribution, which nobody has ever measured directly because there are not enough extremely rare people in any single standardisation sample to measure it from.

Bell curve chart of IQ scores with the population marked at 145, the three standard deviation boundary, and 160, the typical test ceiling, with the extrapolation zone beyond both shaded

160 is a different kind of limit entirely: an instrument ceiling. The WAIS-IV and the Stanford-Binet Fifth Edition, the two most widely used individually administered tests, both cap their standard Full Scale IQ near 160, and their manuals provide no calculation at all for a raw score above the test’s hardest items. That is not a statement about the population; it is a statement about the test. Even a hypothetical person far more capable than anyone in the norm sample would still top out at the same number, because the test simply runs out of harder questions to ask them.

Why sample size is the real constraint

A standardisation sample for a major test typically runs into the low thousands of people, carefully balanced for age, sex and other demographics so that the middle of the distribution is measured with real precision. That is more than enough people to pin down what “average” looks like, and plenty to characterise the range most test-takers actually fall into. It is nowhere near enough to characterise a score that only one person in several thousand reaches. A norm sample of 2,000 people would be expected to contain zero individuals at the rarity a 160 implies under a normal distribution, which means the test cannot empirically verify what that end of the scale should look like — it can only extrapolate the shape of the curve outward from where it actually has data, and trust that the distribution keeps behaving the way the model assumes.

Why the manual just stops

Every subtest on a modern IQ test has a fixed set of items ordered roughly by difficulty. A test-taker who answers every item correctly, including the hardest ones, has hit what psychometricians call a ceiling effect: the test cannot distinguish that person from someone hypothetically even more capable, because there was nothing harder left to ask. The raw score still converts to a scaled score through the norm tables, but that scaled score is capped at whatever the hardest available item supports — it cannot extrapolate past the edge of what the test actually measured.

This also means the reliability of a score is not constant across the range. The standard error of measurement — the margin of uncertainty around any reported score — is smallest near the middle of the distribution, where the norm sample is largest and the item set is best calibrated, and grows toward both tails. A reported 160 carries a substantially wider confidence interval than a reported 100, even though both are presented as single, clean numbers on a report.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

Extended norms: the workaround, and its limits

Test publishers have addressed the ceiling problem for specific instruments through extended norms — not simply adding harder questions, but statistically remodelling the upper end of the scale using a separately recruited, targeted sample of unusually high-ability test-takers combined with the standard norm group. Pearson’s WISC-V Extended Norms is the clearest example, statistically extending the reportable composite range up to a Full Scale IQ of 210. That extension applies to the WISC-V, a children’s instrument — not to the adult WAIS-IV, which as of today still stops at its standard ceiling in ordinary clinical use.

Extended norms are a real statistical solution, not a workaround in the dismissive sense, but they only exist where a publisher has invested in building them for a specific test. A report from an instrument without an extended-norm supplement will still simply stop at its ordinary ceiling, and a clinician working with a potentially profoundly gifted child needs to know, ahead of time, which instrument actually has the extended tables built for it.

What "off the charts" should make you skeptical of

Outside a clinical setting, a claimed score comfortably above 160 is one of the more reliable signs that a result did not come from a properly normed, ceiling-aware instrument. A short online quiz built for a general audience is normed, if it is normed at all, against a sample built to characterise ordinary scores accurately, not the extreme right tail, so a headline result of “175” or higher from that kind of test is telling you more about the scoring formula than about the test-taker. The same caution applies in reverse to a very low reported score from an untested source: the further either end of the scale you look, the more the specific instrument and its norm sample matter, and the less a bare number can be trusted on its own.

Where the very high numbers in circulation come from

Numbers like “228,” which have circulated in reference books and media coverage of certain public figures for decades, do not come from any test administration capable of producing them — no standardised instrument has ever reported a score in that range, for exactly the ceiling reasons described above. Figures like that originate from retrospective estimation methods applied to historical biographical material — childhood achievements, ages at which milestones were reached — run through a formula, not from a person sitting a test with a documented ceiling anywhere near that high. It is one of a handful of durable public misunderstandings about intelligence testing covered in more detail in our piece on brain myths.

What a high-range report should actually say

In practice, psychologists assessing a potentially profoundly gifted child or adult choose instruments specifically for their documented upper range rather than assuming any test will do, and a competent report will say plainly when a score has hit a ceiling rather than presenting a capped number as a precise measurement. High-IQ societies with unusually demanding thresholds handle this the same way: they specify which tests and which scores they accept, generally requiring supervised administration of an instrument with documented norms at that level, rather than accepting any test’s raw maximum at face value. It is a stricter version of the same principle behind Mensa’s own admission requirements and ordinary gifted-programme cutoffs: the number only means what it claims to mean when the instrument behind it is named.

And because scores this extreme are rare enough that two very high-scoring parents do not straightforwardly produce a child at the same extreme, a single very high number — a child’s, an adult’s, or a historical figure’s — is almost always better read as “very high, with real uncertainty about exactly how high” than as a precise point on an infinite scale. If you want your own number, on an instrument with known, stated limits, a properly normed test is where to start; for how the ordinary part of the scale works, the score converter and the full range breakdown cover everything below the ceiling this article is about.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged ceiling effect, confidence interval, extended norms, full scale iq, iq ceiling effect, IQ Test Range, Measurement Error, mensa, Norm Group, profoundly gifted, standard deviation iq, wechsler adult intelligence scale