IQ Metrics
IIF Certified Assessment Start IQ Test
IIF Certified Assessment

Chess Ratings and IQ

Research & Evidence

What Chess Ratings Actually Say About IQ

Chess has a reputation as a proxy for raw intelligence. The best available meta-analysis puts the real correlation at a modest 0.24, and it gets noticeably weaker once you look only at ranked, adult tournament players.
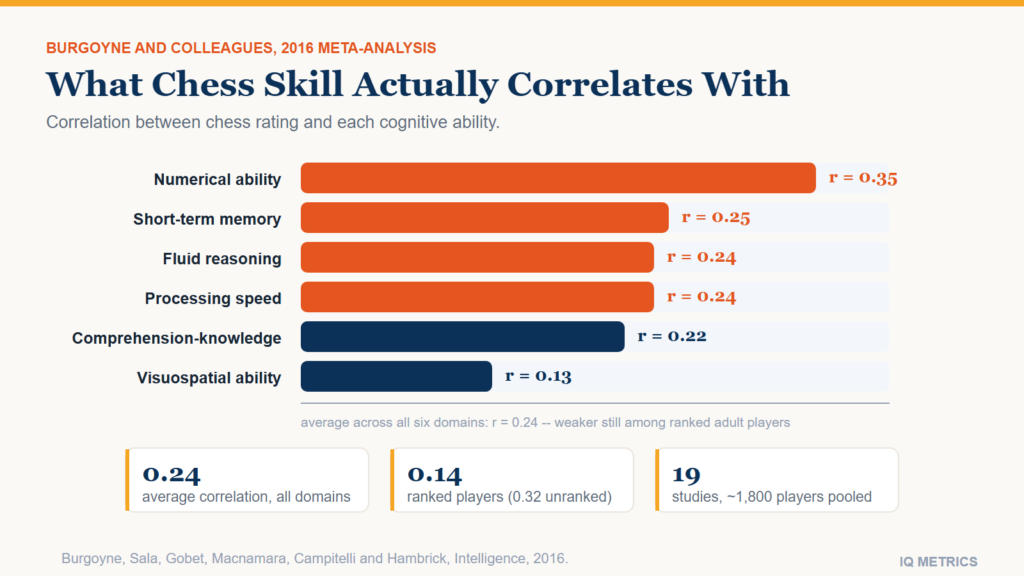
Bar chart of correlations between chess skill and six cognitive abilities from a meta-analysis, ranging from 0.35 for numerical ability down to 0.13 for visuospatial ability

Weaker than the reputation suggests, and weaker still among serious players. The most comprehensive meta-analysis on the question, pooling 19 studies and roughly 1,800 participants across multiple countries and age groups, found chess skill correlates with cognitive ability at an average of 0.24 — a real, statistically reliable relationship, but a modest one, and nowhere near strong enough to treat a rating as a stand-in for an IQ score.

The more interesting finding here is not really the headline number at all. It is what happens to that number once you stop looking at chess players in general and start looking only at the players who take rating and ranking seriously.

What the best evidence actually found

The studies pooled into this meta-analysis measured chess skill in different ways — some by official Elo rating, others by tournament title or self-reported experience — and paired that against a range of standard cognitive batteries rather than a single test. Pooling studies that use different measures of both variables is exactly what a meta-analysis is for: a single study might overstate or understate the relationship depending on who it happened to sample, while pooling nineteen of them, across roughly 1,800 people in total, gives a far more stable estimate of the true underlying correlation than any one study could on its own.

Burgoyne and colleagues’ 2016 meta-analysis (Intelligence, corrected in 2018, with the overall estimate holding near 0.22 after correction) broke the 0.24 average down by cognitive domain: fluid reasoning correlated with chess skill at 0.24, comprehension-knowledge at 0.22, short-term memory at 0.25 and processing speed at 0.24. Numerical ability showed the strongest link at 0.35, ahead of verbal ability at 0.19 and visuospatial ability at only 0.13 — a genuine surprise, given how visual the game looks from the outside.
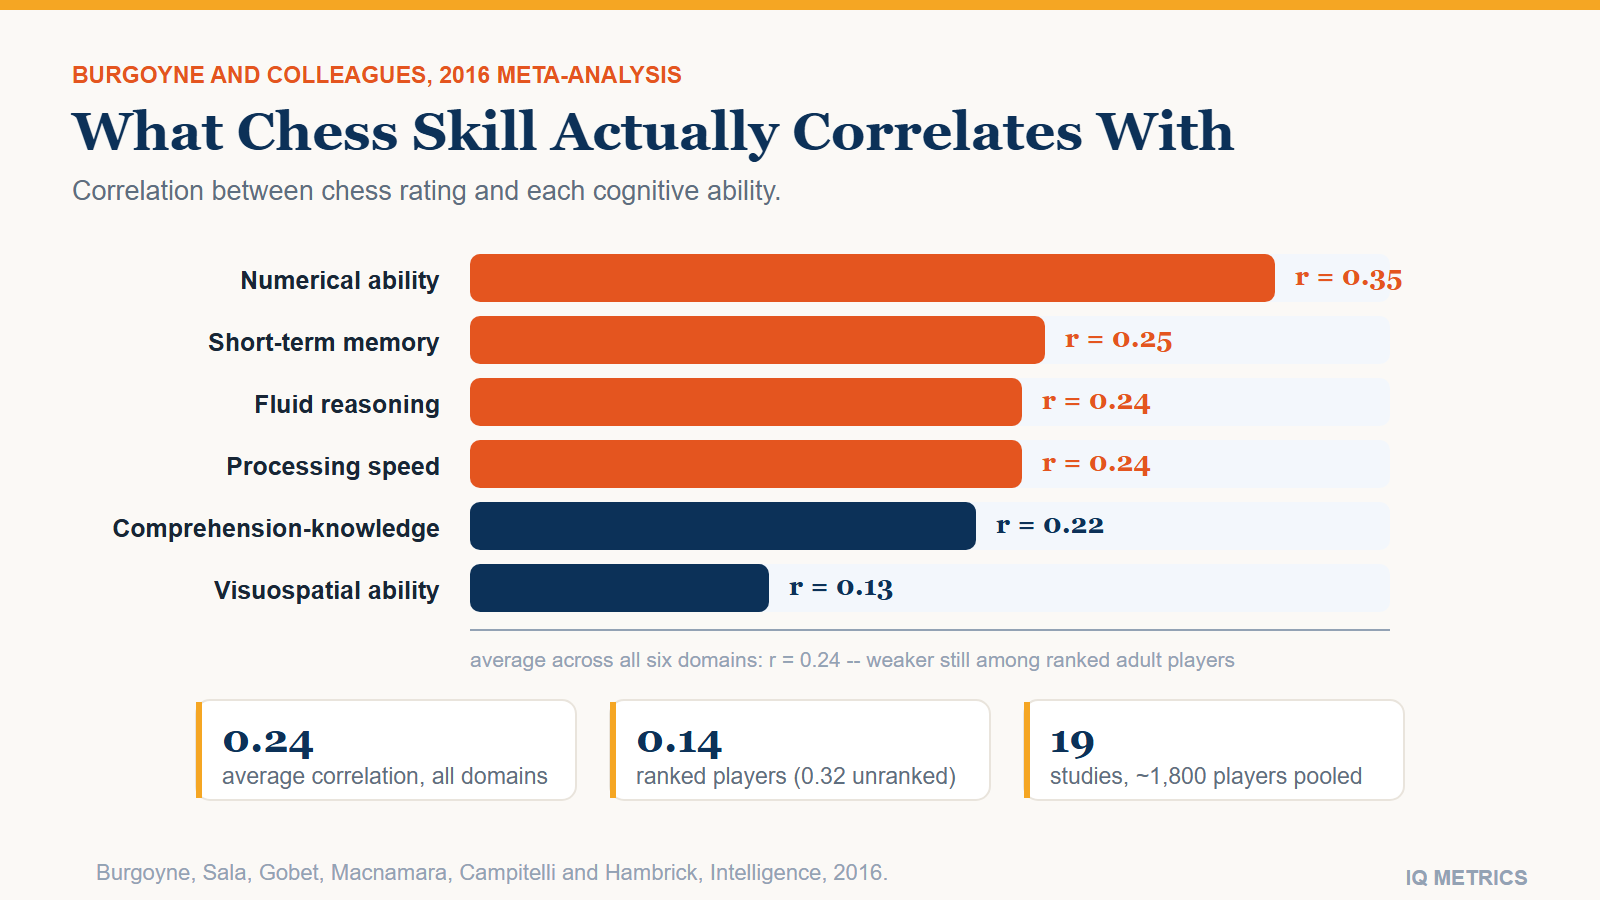
Bar chart of correlations between chess skill and six cognitive abilities from a meta-analysis, ranging from 0.35 for numerical ability down to 0.13 for visuospatial ability

None of these numbers describe a strong relationship. A correlation of 0.24 means cognitive ability, as these tests measure it, accounts for somewhere around 5-6% of the variation in chess skill across the pooled samples — real, worth explaining, and a small fraction of what actually separates a strong player from a weak one.

Why numerical ability and not visuospatial

The domain breakdown holds a genuine surprise. Chess looks like a visuospatial game from the outside — a board, pieces, geometric patterns of attack and defence — yet visuospatial ability produced the weakest correlation of any domain tested, at 0.13, while numerical ability came out strongest at 0.35. The likely explanation is that strong chess play depends less on rotating shapes in your head and more on calculation: tracking forcing sequences, counting material across several moves, holding a chain of if-this-then-that reasoning in mind while checking it against constraints. That is closer to arithmetic reasoning under working-memory load than to the kind of spatial rotation task a visuospatial subtest actually measures, which is exactly the sort of finding that a broad, unexamined assumption — “chess is a spatial game” — gets wrong until someone measures it directly.

Why the reputation outran the evidence

Chess earned its status as a shorthand for raw intelligence long before anyone ran a meta-analysis on the question. Competitive chess is public, scored with a single precise number, and its best-known players — Bobby Fischer winning the world championship as a Cold War news event, Garry Kasparov’s televised matches against IBM’s Deep Blue — were covered in exactly the language used for exceptional intellect. A precise, public rating number attached to a famous “genius” is a much more compelling story than a modest, noisy correlation coefficient, and the story took hold well before the research existed to check it. It is the same gap between a vivid anecdote and a measured effect size that shows up across several other durable myths about intelligence.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

The correlation gets weaker at the top, not stronger

If chess skill were mostly a measure of raw reasoning ability, you would expect the correlation to hold steady, or even strengthen, as players get more serious about the game. The opposite happened. Fluid reasoning correlated with skill at 0.32 in youth samples but only 0.11 in adult samples, and at 0.32 in unranked players but only 0.14 in ranked, competitive ones.

Two things are almost certainly driving that drop. The first is restriction of range: tournament players are already a self-selected group sitting well above the general population on cognitive measures, so there is simply less variation left for a correlation to be measured across. The second is that accumulated deliberate practice does most of the remaining work at the elite end — chess is the single best-documented case where practice explains a large share of skill variance, and that share only grows as players specialise. Raw ability may get you into the pool of serious players; once you are there, thousands of hours of study and opening preparation separate a 2000 rating from a 2700 one far more than a few IQ points would.

So, then, are grandmasters actually smart?

Probably above average, as a group — the selection into serious competitive chess in the first place likely filters on cognitive ability among other things, and the youth-sample correlations are meaningfully higher than the adult ones. But “probably above average as a group” is a much weaker claim than “rating tracks IQ,” and it is the second claim that gets repeated far more often than the evidence supports.

The two claims can both be true at once precisely because group averages and individual prediction answer different questions. Chess players collectively skewing above the general population on cognitive measures is fully consistent with a correlation of 0.24 — and separately, that same 0.24 is far too weak to let you predict one specific player’s IQ from their rating with any real precision. Two players rated 2200 could sit at noticeably different points on a cognitive-ability test and the rating alone would not tell you which was which. A rating measures chess skill extremely precisely; it was simply never built to measure anything else, and the data confirm it does that other job only weakly.

The site’s celebrity pages carry profiles for several well-known players, including Magnus Carlsen, Garry Kasparov, Bobby Fischer and Judit Polgar. None of them have a documented, professionally administered IQ score attached to their chess achievements — the figures that circulate for public figures are almost always estimates rather than test results, for reasons explained in where celebrity IQ numbers actually come from. Their rating is real and precisely measured. Their IQ, as a specific number, generally is not.

A different question than "does chess raise your IQ"

It is worth being explicit that this is a different question from the one covered in our article on whether playing chess raises your IQ. That piece asks about causation and transfer: does taking up chess make you more intelligent. This one asks about correlation among people who already play: does a higher rating indicate a higher IQ. The answers are compatible but distinct — a weak-to-modest correlation between skill and ability is consistent with chess practice producing skill gains that are mostly specific to chess itself, rather than gains that generalise into a broader measure like a full IQ test.

That pattern — skill in a narrow, heavily practiced domain outpacing any change in general cognitive ability — shows up across most “brain game” claims once they are tested rigorously, which is the same caution worth applying to any single activity marketed as a shortcut to a higher score, chess included. Getting better at chess reliably makes you better at chess; the evidence that it reliably makes you better at anything else is much thinner than the reputation implies. If you want to know where you actually stand rather than infer it from a hobby or a rating, a properly normed test is the direct route — though even a properly normed one runs into its own limits at the very top of the scale, which is where the correlation evidence here and the measurement ceiling start to overlap.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged chess and iq, chess rating, chess ratings and iq, cognitive ability, deliberate practice, Elo rating, fluid reasoning, general intelligence, grandmaster, intelligence research, IQ Science, mensa, Processing Speed, Working Memory

IQ Testing for Children

Taking a Test

IQ Testing for Children: Ages, Norms, and What a Score Means

Children are not tested on the same instrument as adults, and the test itself changes twice before age eighteen. Here is which one applies when, how reliable an early score really is, and what a parent should and should not conclude from a single number.
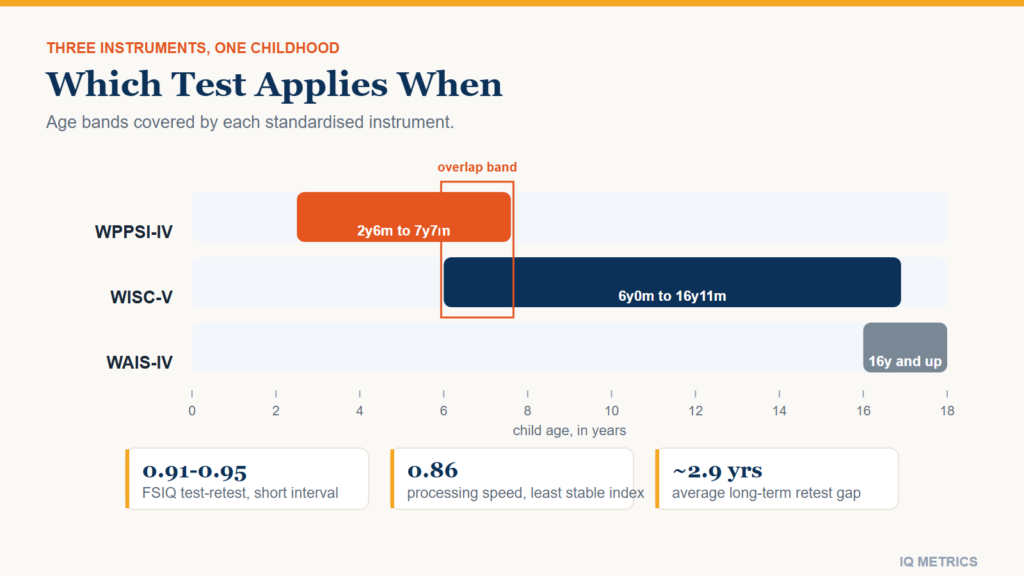
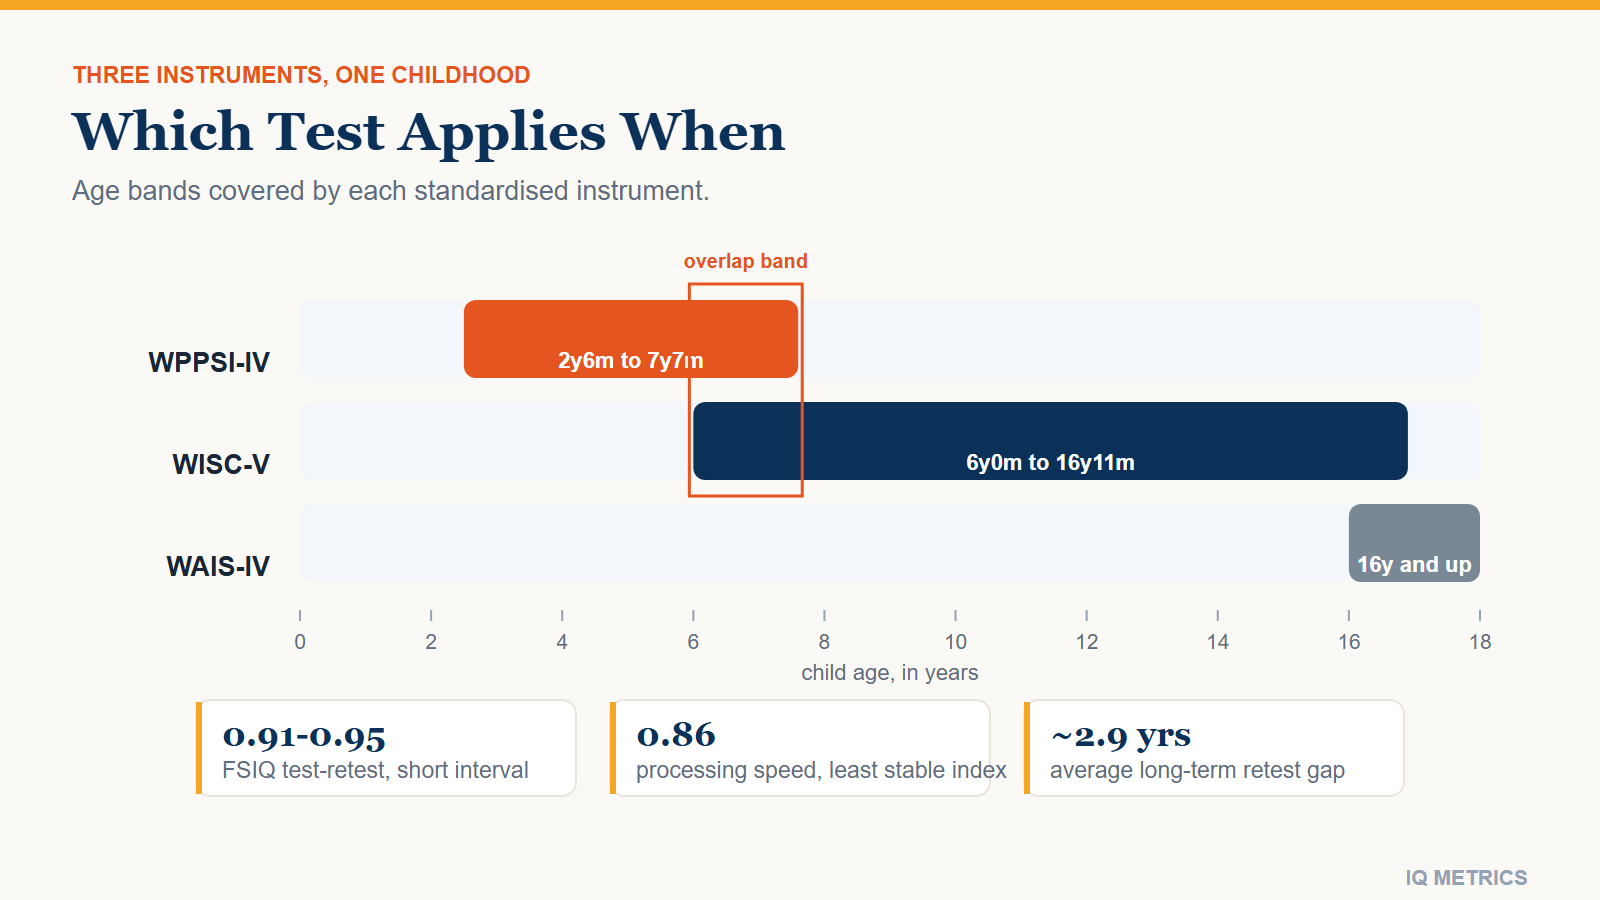
Timeline chart showing which IQ test applies at which childhood age, WPPSI from two and a half to seven, WISC from six to sixteen, and WAIS from sixteen onward, with the six to seven overlap band marked

Children are tested on different instruments than adults, and on more than one instrument across childhood. A five-year-old, a ten-year-old and a sixteen-year-old sitting for a cognitive assessment are not taking scaled-down or scaled-up versions of the same test — they are on entirely different instruments, built and normed separately for their age band, with different weighting between verbal and non-verbal tasks.

Knowing which test applies when, and how much weight to put on an early result, matters more than the score itself. A number produced at age five behaves differently — statistically — from the same number produced at age fourteen, even though both are reported on the identical 100-centred scale.

Which test, at which age

The Wechsler Preschool and Primary Scale of Intelligence (WPPSI) covers ages 2 years 6 months through 7 years 7 months. The Wechsler Intelligence Scale for Children (WISC) covers ages 6 years 0 months through 16 years 11 months, overlapping the WPPSI for roughly eighteen months, during which a clinician can choose either instrument depending on the child. From 16 onward, testing moves to the adult scale, the WAIS.

Timeline chart showing which IQ test applies at which childhood age, WPPSI from two and a half to seven, WISC from six to sixteen, and WAIS from sixteen onward, with the six to seven overlap band marked

The practical difference is not just item difficulty. The youngest WPPSI band leans heavily on non-verbal and receptive tasks — block patterns, picture matching, object assembly — because expressive vocabulary and sustained attention are still developing and are poor proxies for reasoning ability at that age. By the WISC years, verbal comprehension carries much more weight, and by WAIS the index structure (verbal comprehension, visual spatial, fluid reasoning, working memory, processing speed) is what a full adult report is built from. Each transition is also a renorming: a child moving from the WPPSI to the WISC is not just handed harder versions of the same items, but compared against a different standardisation sample entirely, one drawn specifically from children in that older age band.

What the index scores actually measure

A modern child’s report is built from several separate indices, not one number. Verbal comprehension covers vocabulary, reasoning with words and general knowledge. Visual spatial covers reading and reconstructing spatial patterns. Fluid reasoning covers spotting a rule in material the child has never seen before, independent of what they have been taught. Working memory covers holding and manipulating information briefly, such as repeating a sequence backward. Processing speed covers how quickly a child can complete simple visual tasks accurately under mild time pressure. The Full Scale IQ is a composite of all five, which means two children can arrive at the identical overall number by completely different routes — one strong across the board, another with a real strength in one area balancing a real weakness in another.

How stable is a child’s score, really

More stable than most parents expect, and less stable than a single adult retest would be. Short-term test-retest studies (children retested after a few weeks) put Full Scale IQ reliability in the 0.91-0.95 range. Longer-term studies, retesting children after an average gap of nearly three years, still found Full Scale IQ correlating around 0.91 between the two sittings. The weakest link is not the overall score but one specific index: processing speed, which is the least stable of the four main indices across repeat testing, sitting closer to 0.86.

This is a different question from the one answered in our piece on the best age to take an IQ test, which covers how much a result can move between sittings for a given child. This article is about the testing framework itself — which instrument, what it measures, and what a session looks like once you are in the room.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

What a session actually involves

A child’s IQ assessment is individually administered by a trained examiner, not a timed group test and nothing like a rapid online instrument. A full WISC or WPPSI session typically runs one to two hours, often split across a break, and moves between verbal questions, physical manipulatives (blocks, puzzle pieces, picture cards) and timed tasks scored for both speed and accuracy. The examiner is watching for more than the final number: how a child approaches an unfamiliar problem, whether attention holds up across the session, and whether a low score on one subtest reflects ability or something else, such as fatigue or anxiety about the setting. Most examiners spend the first several minutes building rapport rather than presenting test items, precisely because a nervous or unfamiliar child under-performs relative to their real ability, and a thorough report will usually note explicitly whether effort, attention or anxiety appeared to affect any particular score.

The output is not one number but several: an overall Full Scale IQ plus index scores for the separate domains, each with its own percentile. A parent handed only the composite score is missing most of what the assessment actually found; reading the individual indices is usually more informative than the single headline figure.

When a score does not match the classroom

One of the more common reasons a child ends up tested at all is a mismatch: a teacher reporting a struggling student who seems sharp in conversation, or a child who reads well above grade level but cannot finish timed classwork. A full index breakdown is built for exactly this situation. A child can score in the gifted range on verbal comprehension and fluid reasoning while scoring only average on processing speed, and on paper that produces a merely-above-average Full Scale IQ that undersells what is actually a twice-exceptional profile — high ability alongside a specific processing difference. This is also where ADHD, autism and dyslexia intersect with IQ testing: each of those can depress one or two specific indices without touching the others, and a composite score alone will hide exactly the pattern a parent or teacher needs to see.

When, and whether, to retest

Practice effects are real: a child retested soon after an initial assessment will often score somewhat higher on the same instrument simply from familiarity with the item types, not from a genuine change in ability. This is why professionals typically space formal retests at least a year apart, and why a single early result — particularly one from the WPPSI years — should be treated as one data point rather than a permanent label. How much of any later change reflects real development versus test familiarity is exactly the kind of question that made researchers go looking for domains where practice and repetition explain most of what separates high and low performers, which turns out to depend enormously on the domain — chess ratings are a particularly well-studied case.

What parents should actually do with a score

  • Read the percentile, not just the number. A percentile calculator converts any composite score into where it sits against same-age peers, which is what the number is actually for.
  • Do not over-weight one low or high index. A single depressed processing-speed score inside an otherwise average profile is common and is the least stable index for exactly that reason.
  • Treat a WPPSI-era score as provisional. The instrument is good at what it is designed for, but young children’s scores move more between sittings than an older child’s.
  • Use a licensed psychologist for anything with real stakes — a diagnosis, a placement decision, a gifted-programme application. A screening result is a starting point, not a substitute for a full evaluation.
  • Ask for the index breakdown, not just the composite. A flat profile and a spiky one can share the same headline number while calling for completely different next steps.

If you are exploring an assessment rather than pursuing a clinical evaluation, the site’s own children’s assessment, built for ages 4 to 17, gives instant access with no signup. For anything with academic, clinical or legal weight attached to the result, a licensed examiner administering a full WISC or WPPSI battery is the only appropriate route.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged child development, child iq testing, cognitive ability, cognitive development, developmental testing, gifted children, intelligence research, IQ Science, iq testing for children, kids iq test, percentile rank, test norms, WISC, WPPSI

Assortative Mating and IQ

Research & Evidence

Do Smart People Marry Smart People? What the Research Shows

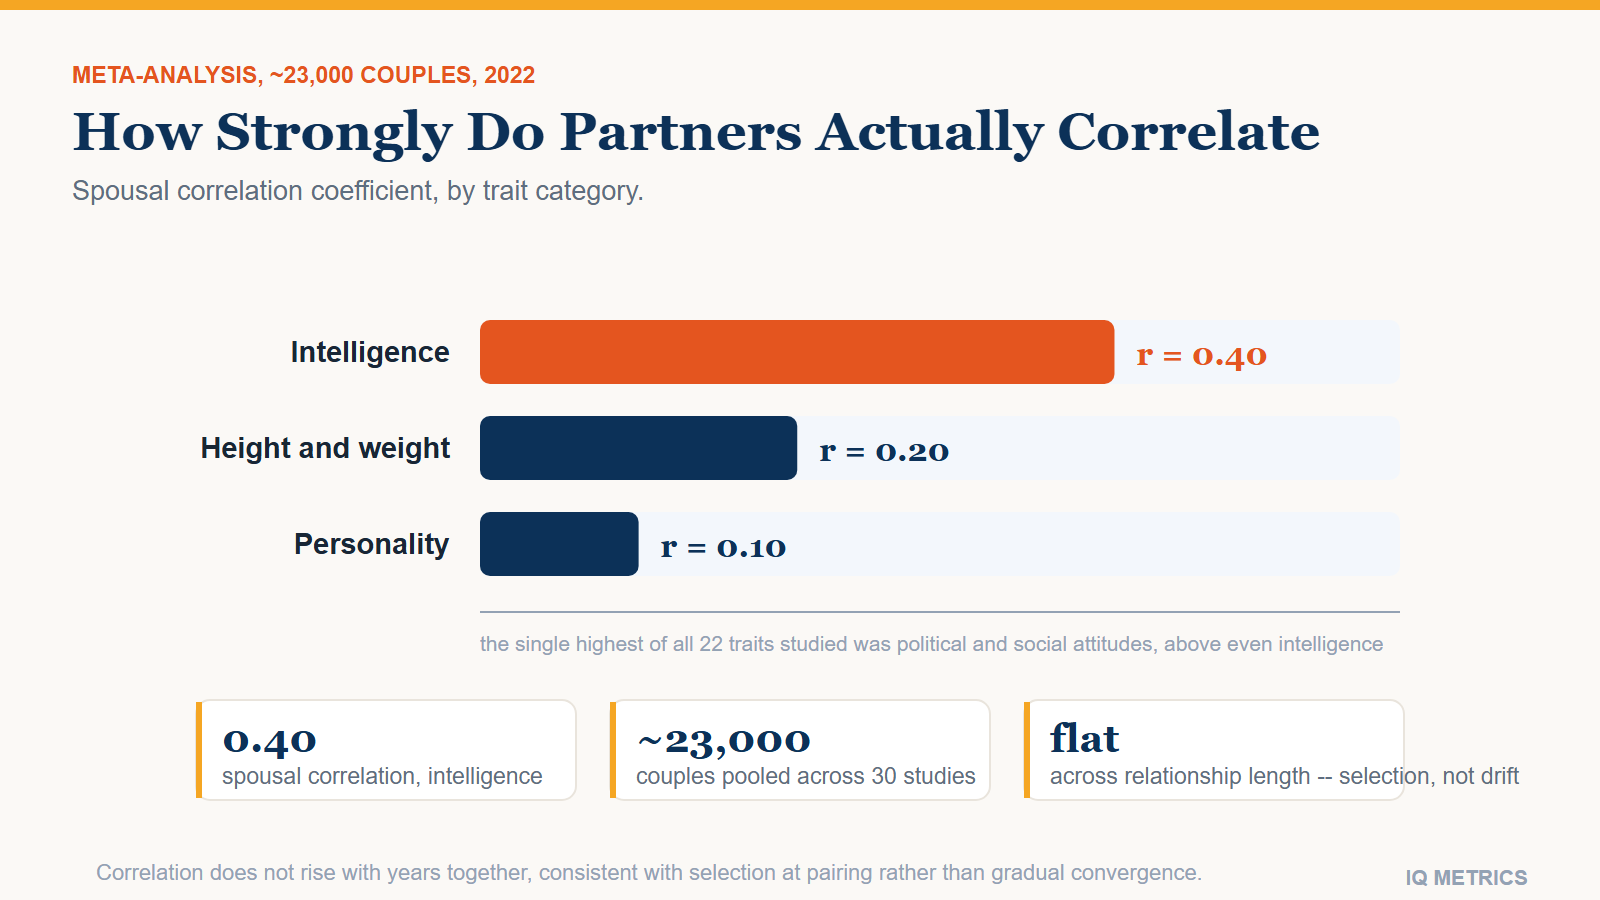
Married and long-term partners score more alike on IQ than on almost any other trait psychologists measure, personality included. The correlation is about 0.40, it shows up before the relationship starts, and it has real downstream effects on how heritability studies get interpreted.

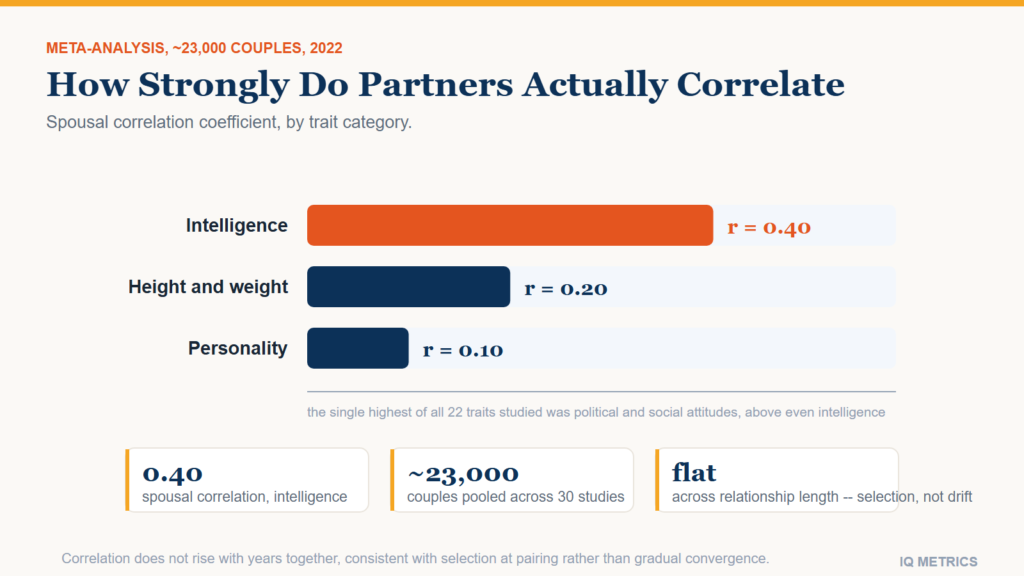
Bar chart comparing spousal correlation coefficients across trait categories, showing intelligence at 0.40, height and weight at 0.20, and personality traits at 0.10

Yes, and more strongly than for most other traits. Long-term partners’ IQ scores correlate at roughly 0.40, well above the correlation for height and weight (about 0.20) and personality (about 0.10). Psychologists call this assortative mating, and for cognitive ability it is one of the largest such effects researchers have measured for any trait.

That number is not just a curiosity about dating. It shows up in how heritability studies are interpreted, it affects how extreme scores are distributed across a population, and it has a specific, well-replicated answer to the obvious follow-up question: are people choosing similar partners, or do partners grow more alike over time?

How strongly do partners actually correlate

A 2022 meta-analysis pooled roughly 30 studies and about 23,000 couples across 22 different traits, from political attitudes to substance use to physical measurements. Correlations across all 22 traits ranged from 0.08 to 0.58, and cognitive ability sat inside the highest cluster alongside social and political attitudes. For intelligence specifically, the pooled spousal correlation landed around 0.40 — roughly double the correlation for height and weight, and about four times the correlation for personality traits such as conscientiousness or extraversion.

Bar chart comparing spousal correlation coefficients across trait categories, showing intelligence at 0.40, height and weight at 0.20, and personality traits at 0.10

Put another way: if you know one partner’s general cognitive ability and nothing else about a couple, you can predict the other partner’s ability better than you could predict their height, their weight, or almost any personality trait you might guess at instead. Political and social attitudes edged even higher in the same analysis, which is its own reminder that people sort into relationships along more than one axis at once.

Selection, not slow convergence

There are two very different stories that could produce a 0.40 correlation. Either people choose partners who already resemble them, or partners spend years together and gradually converge — picking up each other’s vocabulary, reading habits and interests until their scores drift closer. The evidence favours the first story. The correlation does not increase with relationship length in these datasets, which is what you would expect if the similarity were set at the point of selection and simply persisted, rather than something that builds gradually across a marriage.

That matters because it rules out the tidier, more romantic explanation. Couples are not becoming alike; they largely started that way, whether through shared environments that put similar people in the same rooms — university, a profession, a social circle — or through people actively noticing and preferring similarity when they had a choice.

Nobody compares scores on a first date

Almost none of this sorting happens through anyone actually comparing test results. People sort on visible, communicable proxies for ability — years of education, choice of career, vocabulary, the kinds of conversations someone gravitates toward — and those proxies correlate with measured IQ well enough that sorting on them produces the same downstream effect as sorting on the score directly. Educational attainment in particular tends to show spousal correlations at least as high as raw cognitive ability, and often higher, which makes sense once you notice that a degree, a profession and a reading list are all things a prospective partner can actually observe, where a percentile score is not.

Shared environments do a lot of the initial filtering for free. University, competitive workplaces and specific social circles concentrate people who already resemble each other on ability and educational trajectory before anyone makes an active choice, which is part of why the correlation is already sizeable before any deliberate preference gets involved at all — and part of why the earlier finding about overestimating a partner’s intelligence still fits: once the environment has done its filtering, most of the “sorting” left to notice is really just recognising you.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

Why this matters for genetics research

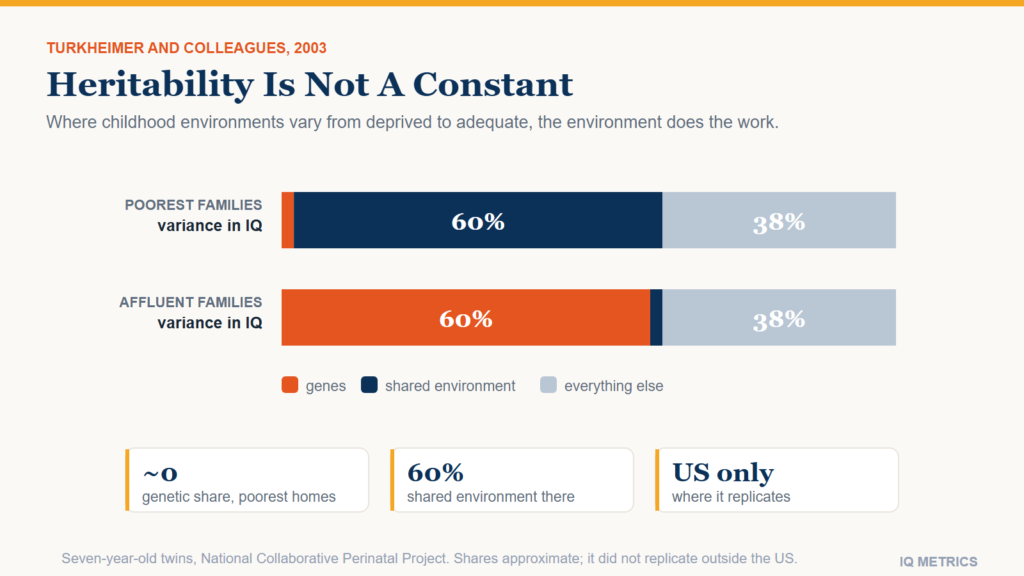
Twin and adoption studies, the backbone of what we know about how heritable IQ is, generally assume mating is close to random with respect to the trait being studied. Assortative mating breaks that assumption. When parents are more similar in cognitive ability than chance would produce, their children end up sharing more genetic variance for that trait than a simple additive model predicts, which is one reason sibling and twin correlations for IQ run slightly higher than a naive heritability calculation alone would account for. Behavioural geneticists build assortative mating into their models explicitly for this reason; ignoring it would quietly inflate certain heritability estimates.

It also interacts with socioeconomic status in a way that is easy to miss. Because people often meet partners through education and work, cognitive assortative mating and socioeconomic assortative mating travel together more often than not — which concentrates both genetic and environmental advantages (or disadvantages) inside the same households rather than spreading them evenly across a population.

There is a more specific technical wrinkle worth knowing if you ever read a twin study closely. Identical twins share essentially all their segregating genes regardless of how their parents paired up, so assortative mating cannot change an identical-twin correlation much. Fraternal twins and ordinary siblings, who share only about half their segregating genes under random mating, end up sharing somewhat more than half when their parents were drawn from an assortatively mated population — because both parents are pulling genetic variants for the trait from the same, narrower part of the distribution instead of independently sampling the whole population. A model that assumes purely random mating and ignores this will misread part of that extra sibling resemblance as shared environment or as additive genetic variance it did not actually measure, which is exactly why modern behavioural-genetic models estimate assortative mating as a term of its own rather than folding it into either category by default.

At the population level, sustained assortative mating on ability also tends to widen the spread of household outcomes over generations rather than narrow it — concentrating high scores, and the education and income that often travel with them, inside the same families instead of distributing them more evenly. Sociologists studying rising household income inequality treat “who marries whom” as one contributing thread among several, not the whole explanation, and untangling how much of it is the pairing itself versus everything that pairing correlates with remains an active, contested area of research rather than a settled number.

People are not great at judging what they are selecting for

One more finding is worth knowing before you assume this is all conscious. Research on how people rate their partners’ intelligence has found that people tend to overestimate a romantic partner’s cognitive ability even more than they overestimate their own — love, or at least attachment, appears to inflate the perception on top of whatever real similarity is already there. So the sorting itself looks fairly precise in aggregate data, even though any individual person asked to explain why they chose their partner is unlikely to describe it in terms of a matched percentile.

What this means if you have, or are raising, children

Two similarly high-scoring parents do not simply average into a guaranteed high-scoring child. Individual scores regress toward the population mean from the midparent value, a pattern Francis Galton first documented with height in the 1880s and which holds for cognitive ability too. Assortative mating does pull the midparent value itself further from the population average than random pairing would, which softens the regression somewhat compared to a scenario where partners paired up by chance — but it does not eliminate it. A child of two very high-scoring parents is likely to score high, and is also likely to score somewhat closer to average than either parent individually.

If that child is eventually tested, the practical questions are less about genetics and more about process — which instrument gets used, how stable an early score actually is, and what a single number should and should not be taken to mean. That side of it is covered in our guide to IQ testing for children.

The short version

Assortative mating for intelligence is real, large by the standards of trait correlations, and set mostly at the point partners choose each other rather than built up afterward. It is one input among many into how ability and opportunity end up distributed across families and generations — alongside heritability and socioeconomic status, not instead of them. If you are curious where your own score sits before speculating about any of this, a properly normed test is the only reliable way to find out.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged assortative mating, assortative mating and iq, cognitive ability, general intelligence, genetics and iq, heritability of iq, intelligence research, IQ Science, mate selection, nature versus nurture, Regression to the Mean, Socioeconomic Status, spousal correlation, twin studies

Growth Mindset and Intelligence

Research & Evidence

Growth Mindset and Intelligence: What the Trials Found

The claim that believing intelligence is malleable makes you achieve more is one of the most widely taught ideas in education, and one of the most heavily contested in the research literature. Three waves of evidence have now landed. Here is what each found, and the question none of them actually answered.

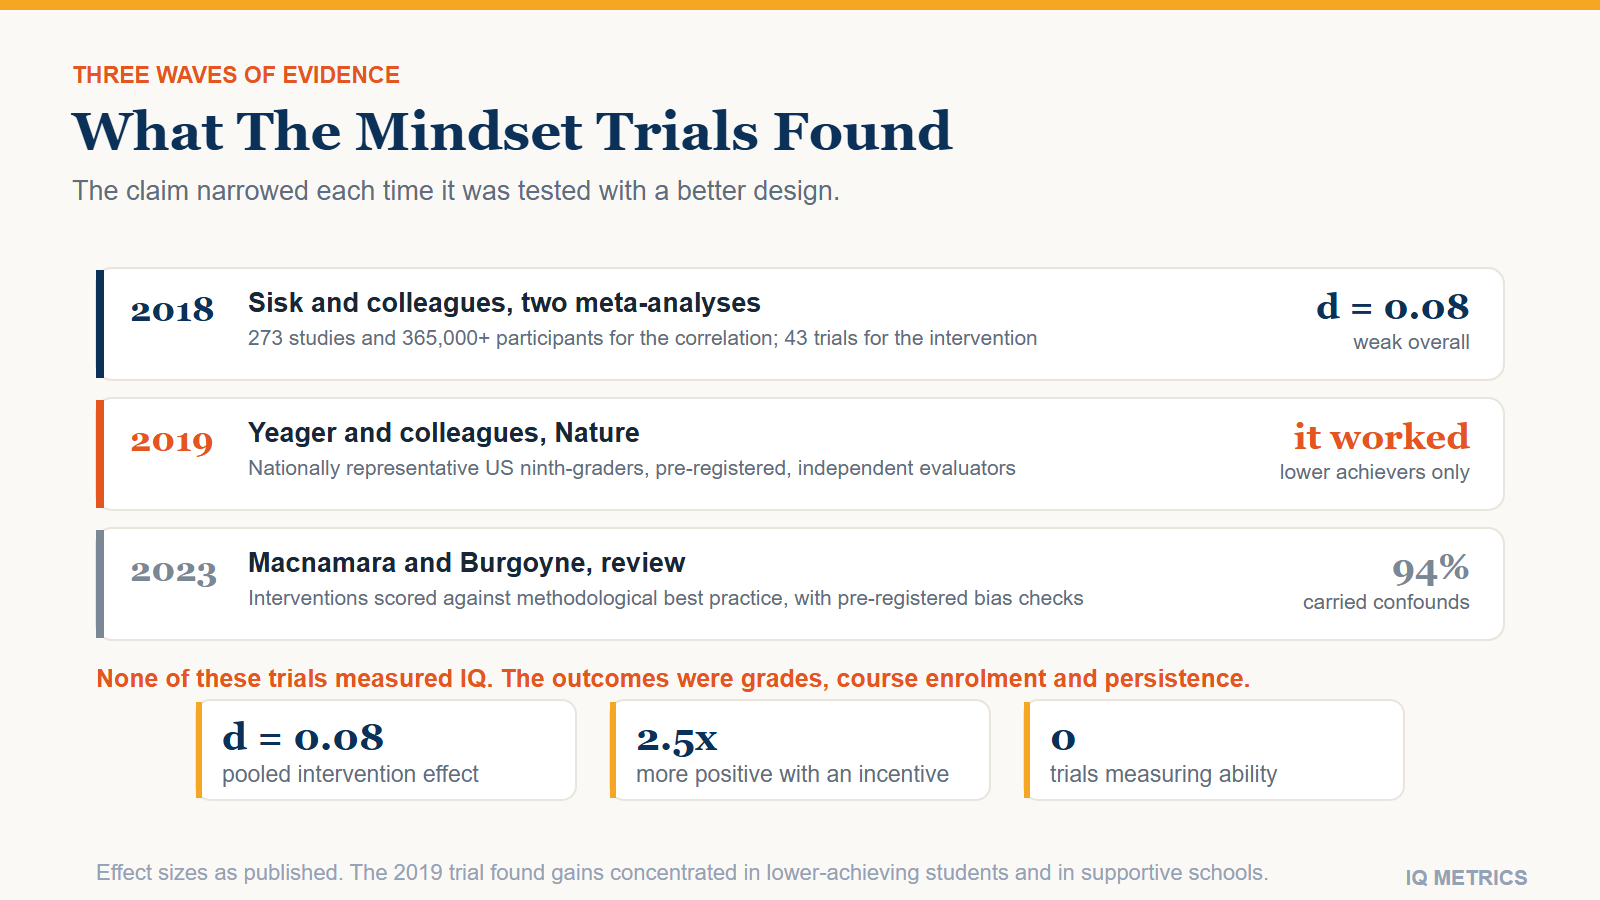
Chart comparing three waves of growth mindset evidence, showing a weak pooled intervention effect, a targeted national trial that worked for lower-achieving students, and a later review finding widespread bias

The growth mindset claim is that believing intelligence can be developed leads people to work differently and therefore achieve more. It has been taught in schools worldwide for two decades. The evidence, taken as a whole, supports a much narrower version than the one that got taught: pooled across trials the effect on achievement is small, in one large national experiment it was real but concentrated in specific students and specific schools, and a 2023 review found the literature itself carries serious bias.

There is also a question that gets quietly skipped in almost every popular account, and it matters more here than anywhere else on this site: no growth mindset trial has measured IQ. Not one. What follows separates what was tested from what is claimed.

What the claim actually is

Carol Dweck’s framing distinguishes a fixed mindset, in which ability is a trait you have a fixed amount of, from a growth mindset, in which ability develops through effort and strategy. The predicted mechanism is about response to difficulty: someone who reads a failure as evidence of a limit withdraws, while someone who reads it as evidence that the approach needs changing persists. The intervention is usually short — often under an hour online — and teaches the brain-as-malleable idea directly.

It is worth being precise about the claim, because the popular version drifts. The research claim is that mindset affects behaviour under difficulty and therefore achievement. It is not that believing you can get smarter makes you smarter, which is a much stronger claim that nobody set out to test.

The first meta-analysis found a weak effect

In 2018 Victoria Sisk and colleagues ran two meta-analyses. The first pooled 273 studies with over 365,000 participants to ask how strongly mindset correlates with academic achievement. The second pooled 43 intervention studies with over 57,000 participants to ask whether teaching a growth mindset changes achievement. Both effects were weak. The intervention effect came out at d = 0.08 — statistically distinguishable from zero given the sample size, and small enough that it would be invisible in any individual classroom.

The moderator analysis was more interesting than the headline. Effects were larger for students who were academically at risk and for students from low socioeconomic backgrounds. That is a coherent pattern rather than noise: an intervention that addresses a belief can only help someone whose belief was the obstacle, and a student already doing well was probably not held back by thinking ability was fixed. It also predicts that universal rollouts will underperform targeted ones, which is roughly what happened.

Chart comparing three waves of growth mindset evidence, showing a weak pooled intervention effect, a targeted national trial that worked for lower-achieving students, and a later review finding widespread bias

The national experiment, and where it worked

The strongest single piece of evidence is the National Study of Learning Mindsets, published in Nature in 2019 by David Yeager and a large team. It is the study to take seriously: a nationally representative sample of United States ninth-graders, randomised, pre-registered, with the analysis plan set in advance and independent evaluators. The design was built to settle the question rather than to confirm it.

It found a real effect, and found it in a specific place. Grades improved among lower-achieving students, and enrolment in advanced mathematics rose. Among students already doing well, little changed. The effect also depended on the school: it held where peer norms supported taking on academic challenge and faded where they did not. A one-hour online exercise cannot sustain a behaviour that a student’s environment discourages, which is a finding about the limits of cheap interventions generally.

So the honest summary of the strongest study is not “growth mindset works” or “growth mindset failed”. It is that a well-designed version produced a modest, targeted improvement in grades for the students who needed it, in schools that reinforced it.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

The 2023 review found bias in the literature

Macnamara and Burgoyne then examined the intervention literature against a set of methodological best practices, and the results are the reason for caution about the wider field rather than about any one trial.

  • 94 percent of the growth mindset interventions reviewed carried confounds — the treatment group got something other than the mindset message that the control group did not.
  • Authors with a known financial interest in mindset training were about two and a half times as likely to report positive effects.
  • Higher-quality studies were less likely to show a benefit, which is the signature pattern of an effect that shrinks as methods improve.

That last point is the serious one. A real effect usually holds up or sharpens under better methods. An effect that fades as designs tighten is more consistent with bias in the weaker studies than with a robust phenomenon, and it is the same pattern that deflated the brain-training literature.

A quieter problem runs underneath all of it: measurement. Mindset is usually captured by a handful of self-report items asking whether you agree that intelligence is fixed. Whether agreeing with those statements corresponds to how a person actually behaves when a problem gets hard is not well established, and different studies operationalise the construct differently. When the definition, the measure and the intervention all vary between studies, a pooled effect size is harder to interpret than the single number suggests — a point subsequent commentaries have pressed on both sides of the dispute.

Does any of this change an IQ score?

There is no evidence that it does, and almost no evidence either way, because the outcome measures in this literature are grades, course enrolment and task persistence. Cognitive ability was not the dependent variable in the trials that matter, so anyone citing growth mindset as a route to a higher IQ is extrapolating well past the data.

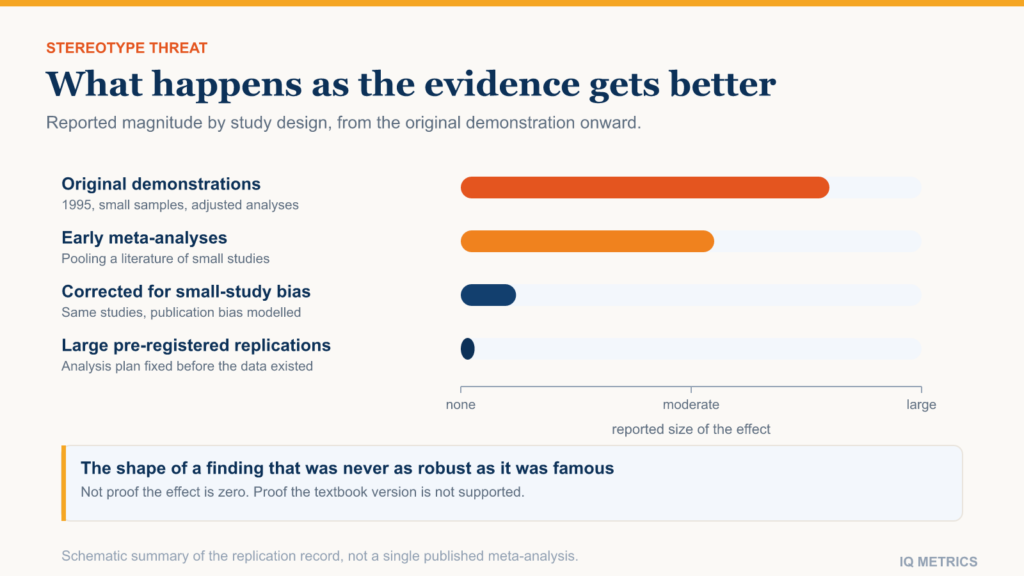
A weaker version is defensible. Beliefs about ability plausibly affect how someone approaches a test — whether they persist on a hard item or give up on it — and effort on the day is a genuine source of variation in scores. That would be an effect on measured performance rather than on underlying ability, which is the same distinction that applies to stereotype threat and to test anxiety. Both belong to the set of factors that move a result without moving the ability behind it.

What survives the criticism

Stripped of the oversell, several things stand. Targeted interventions for struggling students have the best support and the clearest mechanism, and the students they help most overlap substantially with the ones whose circumstances constrain them in the first place — the pattern described in the evidence on socioeconomic status. Context matters: the same message lands differently depending on whether the environment supports acting on it. And a short, cheap intervention producing any measurable change in grades is not nothing, provided nobody sells it as a substitute for teaching.

What does not survive is the strong version: that mindset is a major determinant of achievement, that a one-hour exercise transforms outcomes for everyone, or that it touches cognitive ability. That version was always more popular than it was supported, and it is a useful case study in how a modest finding becomes a movement — the same trajectory as several of the persistent myths about the brain.

What to do with this

If you are a student or a parent, the defensible takeaway is modest and still worth having: treating difficulty as information about strategy rather than as a verdict on capacity is a better response, and it is most valuable for someone who has been struggling. Just do not expect it to substitute for the things with larger effects, most obviously time in education itself.

If the underlying question is how much of ability is fixed, the evidence sits across three articles rather than one: what heritability actually means, how far practice takes you, and what moves a score. And if you want a measurement rather than a belief about yourself, a properly normed test is the shortest route to one.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged Academic Achievement, cognitive ability, Dweck, education, fixed mindset, growth mindset, growth mindset and intelligence, intelligence research, IQ Science, learning, meta-analysis, motivation, replication crisis, Stereotype Threat

Talent vs Practice

Research & Evidence

Talent vs Practice: What Decides How Good You Get?

The 10,000-hour rule made a strong claim: expert performance is built by practice, not given by talent. When researchers pooled the studies that had actually measured it, practice explained about a quarter of the difference between people in games and almost none in professional work. Here is what fills the rest of the gap.
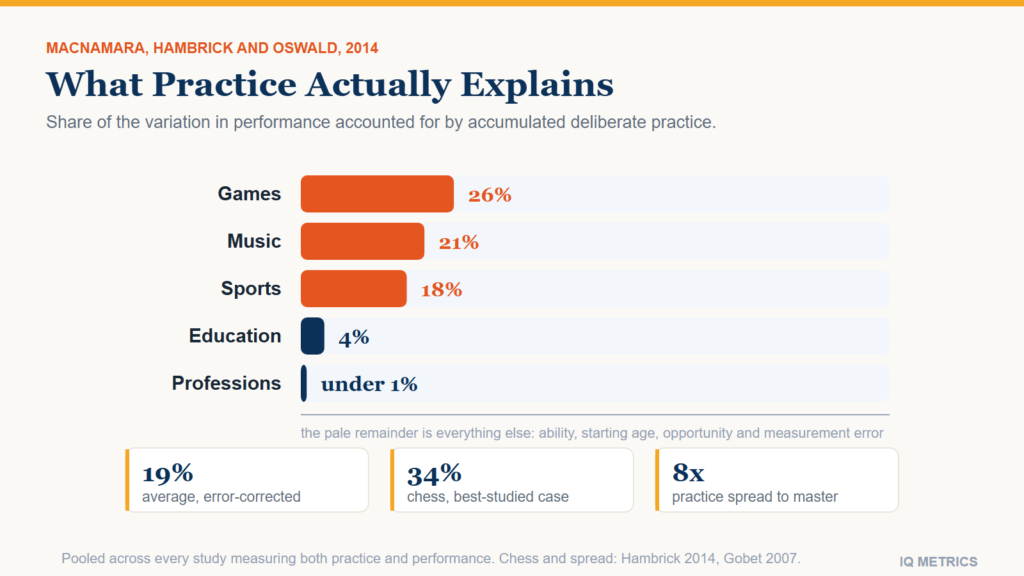
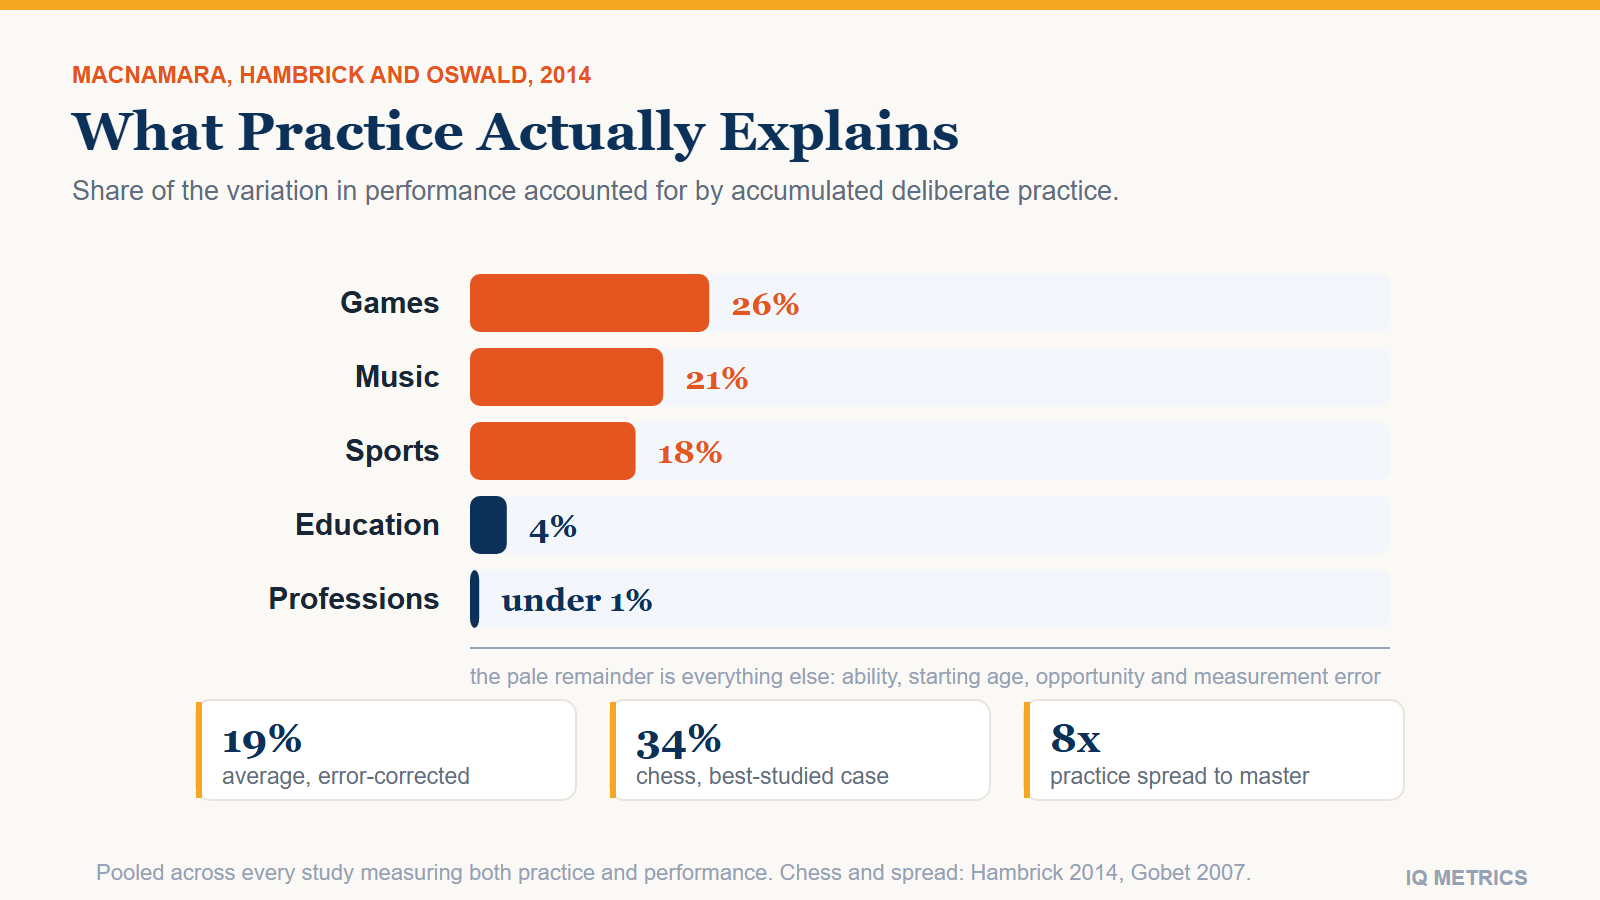
Bar chart of the percentage of performance variance explained by deliberate practice in five domains, from 26 percent in games down to under 1 percent in professions, with the unexplained remainder shown

Practice matters enormously and it does not explain most of the difference between people. Those two statements are both supported, and holding them together is the whole of this subject. When Brooke Macnamara, David Hambrick and Frederick Oswald pooled every study that had measured accumulated practice against performance, practice accounted for 26 percent of the variance in games, 21 percent in music, 18 percent in sports, 4 percent in education and less than 1 percent in professional work. Averaged across domains and corrected for measurement error, about 19 percent.

That is a large effect by the standards of psychology and a small one relative to what was claimed. This article traces how the claim got made, what the numbers look like domain by domain, what occupies the remaining variance, and what any of it means for a test score.

Where the 10,000-hour rule came from

The research behind the slogan is a 1993 study by Anders Ericsson and colleagues of violinists at a Berlin music academy. The best students had accumulated substantially more solitary, effortful practice than the good ones. Ericsson called this deliberate practice and drew a sharp distinction between it and merely playing a lot: it is structured, aimed at a specific weakness, and immediately corrected.

Two things then happened. The finding was popularised as a threshold — ten thousand hours and you are an expert — which Ericsson himself disowned, since the figure was an average for one group in one conservatoire and not a target. And the stronger theoretical claim, that individual differences in expert performance are largely or wholly a product of deliberate practice, became the thing everyone remembered. That claim is testable, and it has now been tested a great deal.

What happened when the studies were pooled

The 2014 meta-analysis is the central result. Its design is simple: gather every study that recorded both accumulated deliberate practice and a performance measure, and see how strongly they relate. The domain-by-domain spread turned out to be far more informative than the average.

  • Games — 26 percent of variance explained, the strongest domain, and chess supplies most of the data.
  • Music — 21 percent, the domain the original claim was built on.
  • Sports — 18 percent.
  • Education — 4 percent.
  • Professions — under 1 percent, which is to say essentially nothing.

The gradient is the finding. Practice explains most where the task is stable, closed and well-defined, and almost nothing where the work is variable and the goalposts move. A chess position obeys the same rules it did a century ago; a job does not. So the ten-thousand-hours framing is least wrong exactly where people are least likely to apply it, and least applicable to the careers it is usually invoked about.

Bar chart of the percentage of performance variance explained by deliberate practice in five domains, from 26 percent in games down to under 1 percent in professions, with the unexplained remainder shown

Chess is the best-studied case

Chess is where the evidence is richest, because ratings give a continuous, well-calibrated performance measure that few domains can match. A 2014 reanalysis by Hambrick, Oswald, Altmann, Meinz, Gobet and Campitelli put deliberate practice at 34 percent of the reliable variance in chess skill and 29.9 percent in music. A third is a lot. It is also not most of it.

The more striking number comes from a 2007 study by Fernand Gobet and Guillermo Campitelli of 104 Argentinian players ranging from weak amateurs to grandmasters. The minimum practice needed to reach master level was around 3,000 hours — and the slowest player to get there had needed roughly eight times as much as the fastest. Both reached the same title. If practice hours were the mechanism, that spread should not exist.

Note the boundary of this claim. It is about how much practice buys you at the top of one game, not about whether playing chess makes you generally smarter, which is a different question with a different answer — covered in the article on chess and IQ.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

So what is the rest of the variance?

Some of it is measurement. Retrospective estimates of practice hours are self-reported and often reconstructed years later, which attenuates any correlation and means the true effect is somewhat larger than the raw numbers suggest. The 2014 meta-analysis corrected for this, which is why its corrected figures run higher, and honest accounting has to concede it.

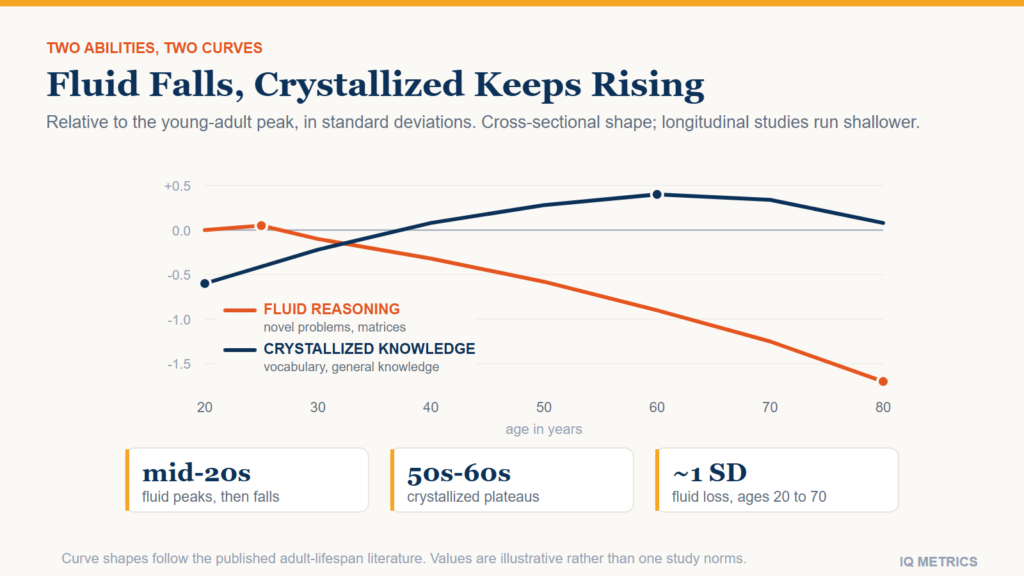
Beyond that, several factors have real support. Starting age matters independently of total hours. Working memory capacity predicts performance in some domains even among people matched on practice, and it is worth being precise that this is a capacity distinct from reasoning ability — the difference is set out in the piece on working memory and reasoning. And reasoning ability itself predicts the early rate of skill acquisition particularly strongly, which is why measures of fluid ability show up in expertise research at all.

There is also a selection effect that is easy to miss. People who improve quickly tend to enjoy the activity and keep going; people who improve slowly tend to stop. Accumulated practice is therefore partly an outcome of early aptitude rather than purely a cause of later skill, and no correlational design can fully separate the two.

One more caveat cuts the other way, and it is the reason these percentages should not be read as constants. Variance explained depends on who is in the sample. Study only grandmasters and almost everyone has practised enormously, so practice explains little of what separates them; widen the sample to include beginners and the same variable suddenly explains a great deal. Much of the expertise literature deliberately samples near the top, which pushes the practice figure down. The gradient across domains survives this objection, because it compares like with like, but any single number does not travel well outside the sample that produced it.

Ericsson objected, and the objection is partly fair

Ericsson’s response was that the meta-analysis diluted his construct: many of the pooled studies measured accumulated experience or general practice, not deliberate practice in his strict sense of individualised, coached, immediately corrected work on a specific weakness. That is a real methodological objection and it is probably right that the pooled figure understates properly-defined deliberate practice.

It also does not rescue the strong claim. Even within chess and music, where the measures come closest to his definition, the figure lands around a third. And the strict definition creates a problem of its own: if only practice that produces improvement counts as deliberate, the theory becomes difficult to falsify. The defensible position that survives both sides is that deliberate practice is necessary and not sufficient.

Why this is not an argument for giving up

The variance-explained framing answers a question about differences between people who are already competing. It does not tell an individual what returns their own effort will produce, and those are two different questions. Nobody reaches master level at anything on 300 hours. The floor is real even where the ceiling is unevenly distributed, and almost everyone reading this is nowhere near their own floor.

What the evidence does argue against is the inference that someone who improved slowly did not try hard enough. That is the moral sting of the strong practice claim, and it is not supported. It also argues against the reverse error — reading a test score as a verdict on your ceiling. A score is a measurement of current ability under specific conditions, which is why what a score predicts about later outcomes is always a matter of averages and never of individuals.

What it means for your own score

Treat ability and practice as inputs that multiply rather than as rivals. Higher reasoning ability buys a faster rate of return on the same hours, which is why it shows up in early acquisition; sustained practice compounds whatever rate you have, which is why it dominates at the top of narrow, stable domains. Neither substitutes for the other, and a score tells you about one input on one day.

If the underlying question is whether the ability itself can be moved, that is covered in what actually raises a score, and the specific claim that believing ability is malleable changes outcomes is examined in the growth mindset evidence. To get a current measurement rather than an estimate, take a properly normed test.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged 10000 hour rule, chess, cognitive ability, deliberate practice, Ericsson, expertise, intelligence research, IQ Science, learning, nature versus nurture, skill acquisition, talent, talent vs practice, Working Memory