IQ Metrics
IIF Certified Assessment Start IQ Test
IIF Certified Assessment

Socioeconomic Status and IQ

Research & Evidence

Socioeconomic Status and IQ: What the Evidence Shows

Family circumstances track IQ scores, and the relationship is stranger than a simple gap. In the poorest families studied, genes explained almost none of the variation in childhood scores and shared environment explained most of it. In affluent families the pattern reversed. Here is what that finding does and does not support.
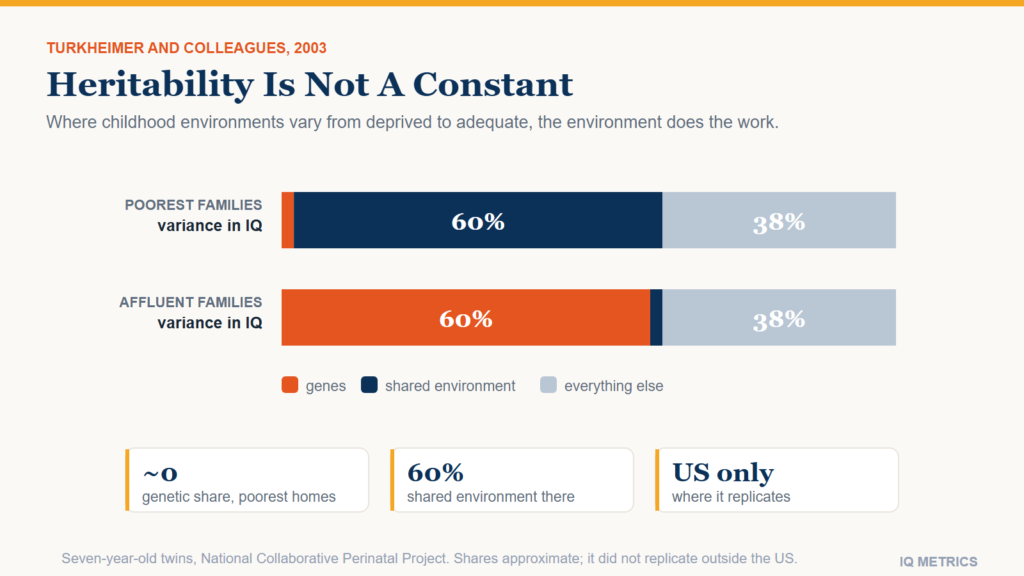
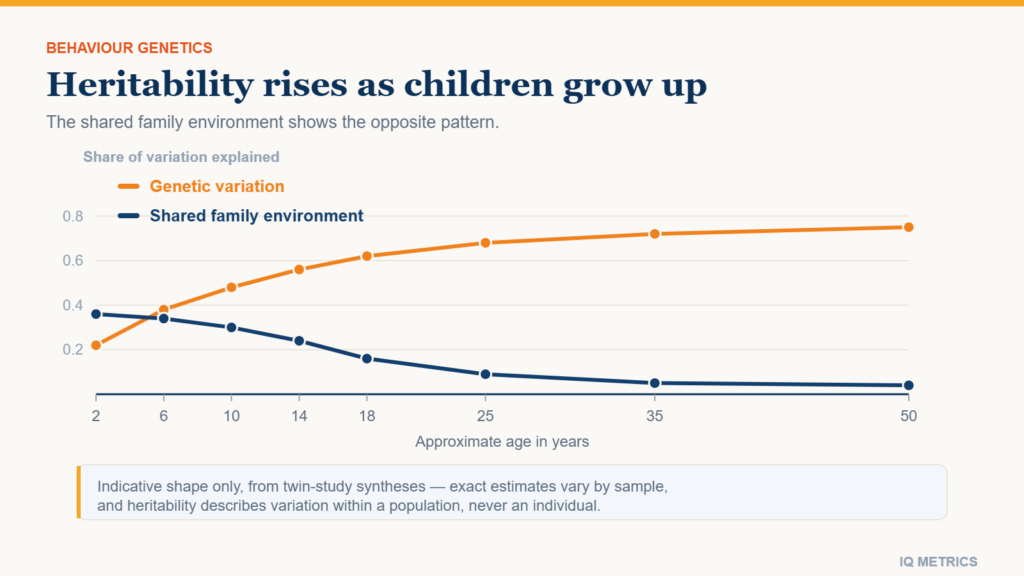
Chart showing how the heritability of IQ changes with family income in the Turkheimer 2003 twin study, with shared environment accounting for most variance in the poorest families and genes for most in affluent ones

Children from wealthier families score higher on IQ tests on average. That much has been in the literature for a century and is not seriously disputed. The interesting part is the shape of the relationship, because socioeconomic status does not merely shift scores up and down — in the best-known study of the question it changed how much heritability itself explained. That result is genuinely surprising, it has been partly replicated and partly not, and it is routinely overstated in both directions.

This article covers the size of the gap, the gene-environment interaction behind it, the adoption evidence that comes closest to a natural experiment, and the mechanisms that plausibly carry the effect. It is about the arrow running from circumstances to scores. The arrow running the other way — whether a score predicts what you go on to earn — is a separate question, covered in the evidence on IQ and income.

How large is the gap

Across studies, measures of family socioeconomic status correlate with childhood IQ at somewhere around 0.3. That is a real association and a moderate one: it means status accounts for something like a tenth of the variation in scores, and that the distributions overlap heavily. Plenty of children from poor families score above the average for rich ones. A correlation of this size is a fact about populations and close to useless as a prediction about a person.

The correlation is also not one clean variable. Household income, parental education and parental occupation each contribute, they are entangled with each other, and they are entangled with genetics too, since the parents passing on the environment are also passing on the genes. Untangling that is what the twin and adoption designs below exist to do, and it is why an unadjusted income-to-score correlation is the weakest evidence in this article rather than the strongest.

Turkheimer: heritability itself changes with income

In 2003 Eric Turkheimer and colleagues analysed IQ scores from seven-year-old twins in the National Collaborative Perinatal Project, a sample with an unusually large number of families at or below the poverty line — which matters, because most twin studies draw from comfortable volunteers and so cannot see the bottom of the range at all. Instead of estimating one heritability for the sample, they let the genetic and environmental components vary as a function of socioeconomic status.

The result: in the poorest families, shared environment accounted for roughly 60 percent of the variance in scores and the genetic contribution was close to zero. In affluent families the pattern was approximately reversed. The interpretation that follows is not that genes matter less for poor children in some mystical sense. It is that genetic potential expresses itself only to the extent that the environment permits it. Where conditions vary from adequate to excellent, the remaining differences between children are largely genetic. Where conditions vary from deprived to adequate, the environment is doing the work — it is the binding constraint.

This is a genuinely important qualification to the standard heritability figure quoted for adult IQ, and it sits alongside rather than against the twin-study evidence on heritability. A heritability estimate is not a constant of nature; it is a description of one population in one set of conditions.
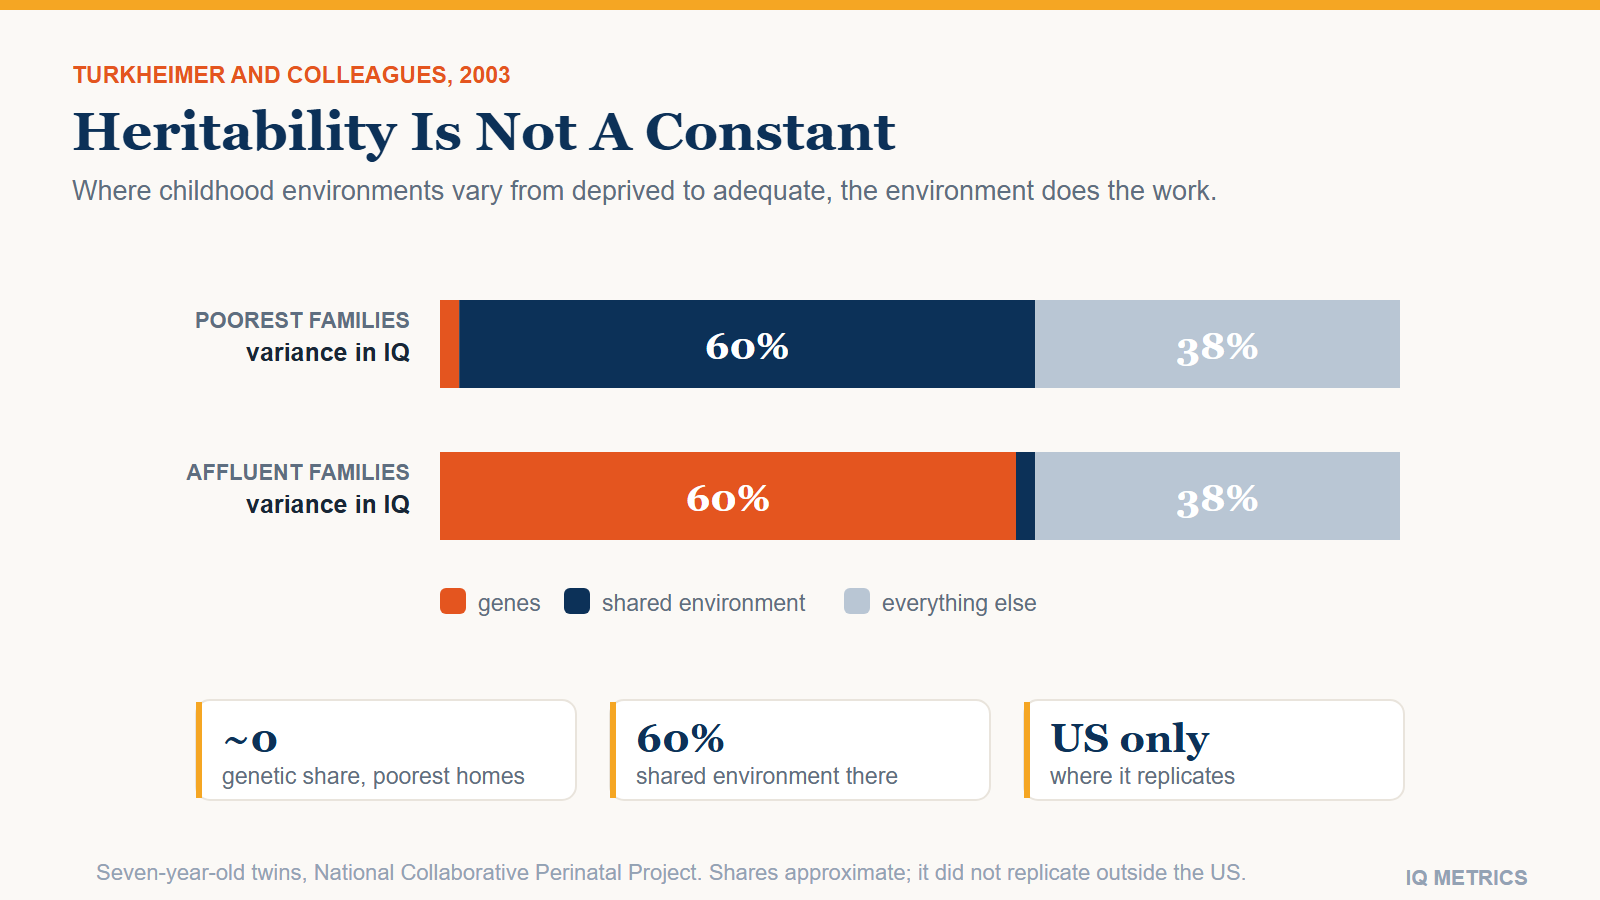
Chart showing how the heritability of IQ changes with family income in the Turkheimer 2003 twin study, with shared environment accounting for most variance in the poorest families and genes for most in affluent ones

Why the finding did not replicate everywhere

The honest version of this story includes the replication record, which is mixed in an informative way. A 2016 meta-analysis by Tucker-Drob and Bates pooled the studies that had tested this interaction. They found it, on average, in United States twin samples — though accounting for less variance than the original headline suggested. In samples from Europe, England and Australia they did not find it at all.

That cross-national split is a result in itself rather than a failure. The most straightforward reading is that the interaction appears where the bottom of the income distribution is genuinely deprived and disappears where a welfare floor, universal healthcare and more evenly funded schools compress the range of childhood environments. On that reading the finding is not about income as such, but about how bad the worst environments in a country are allowed to get — which is a testable claim, and one reason the question is still open.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

Adoption studies: the closest thing to an experiment

Twin designs infer environmental effects; adoption designs move children between environments, which is as close to a natural experiment as this field gets. The clearest example is a 1999 French study by Michel Duyme and colleagues, which found 65 children who had been adopted between the ages of four and six after abuse or neglect, and whose measured IQ before adoption was below 86 — the group averaged 77.

Reassessed in adolescence, all of them had gained, and how much depended on where they landed. Children adopted into low-status families gained 7.7 points on average. Children adopted into high-status families gained 19.5. Same starting range, same country, same age at placement, and a twelve-point difference attributable to the adoptive home. Two things make this unusually persuasive: the pre-adoption score is measured rather than assumed, and adoptive placements are not made at random but also are not made by the birth families, which breaks the usual confound between the genes a child inherits and the home they grow up in.

Note the direction it points. Even in the best-placed group the gain did not erase the differences between individual children, and pre-adoption scores still predicted post-adoption ones. Environment moved every child substantially; it did not make them interchangeable.

What actually carries the effect

“Socioeconomic status” is a proxy, not a mechanism. It stands in for a bundle of things that each have their own evidence, and the bundle is why the association is robust even though no single element explains much.

  • Environmental toxins. The dose-response relationship between childhood lead exposure and lost cognitive ability is one of the better-established findings in the field, and exposure tracks housing age and neighbourhood — see the evidence on lead.
  • Nutrition, particularly early and particularly iodine and iron deficiency, where the effects are largest in the populations that are most deficient. What diet does and does not do is narrower than the supplement market suggests.
  • Schooling. Quantity of education raises scores measurably, and access to it is unevenly distributed; the natural experiments on schooling put the effect at a few points per year.
  • Chronic stress and instability, which affect working memory and attention directly and also affect test-day performance, overlapping with test anxiety.
  • Language exposure, which loads onto the crystallized half of a score far more than the fluid half — a distinction that matters for interpretation and is set out in the fluid and crystallized article.

What this evidence does not support

Three inferences get drawn from this literature that it will not carry. The first is about individuals: none of it predicts a particular person’s score from their background, and the overlap between groups is far larger than the gap between them.

The second is about groups. Heritability estimated within a population carries no information about the causes of differences between populations — this is a point of arithmetic rather than of politics, and it is the reason national IQ rankings cannot support the claims made for them. The Turkheimer finding actually sharpens the point: if the expression of genetic potential depends on the environment, then comparing groups in different environments tells you nothing clean about either.

The third is fatalism, and it is contradicted by the adoption data on its own terms. A twelve-point difference produced by where a child was placed is a large effect by any standard in this field. What the evidence describes is a constraint that can be loosened, not a ceiling that cannot.

Reading a score with this in mind

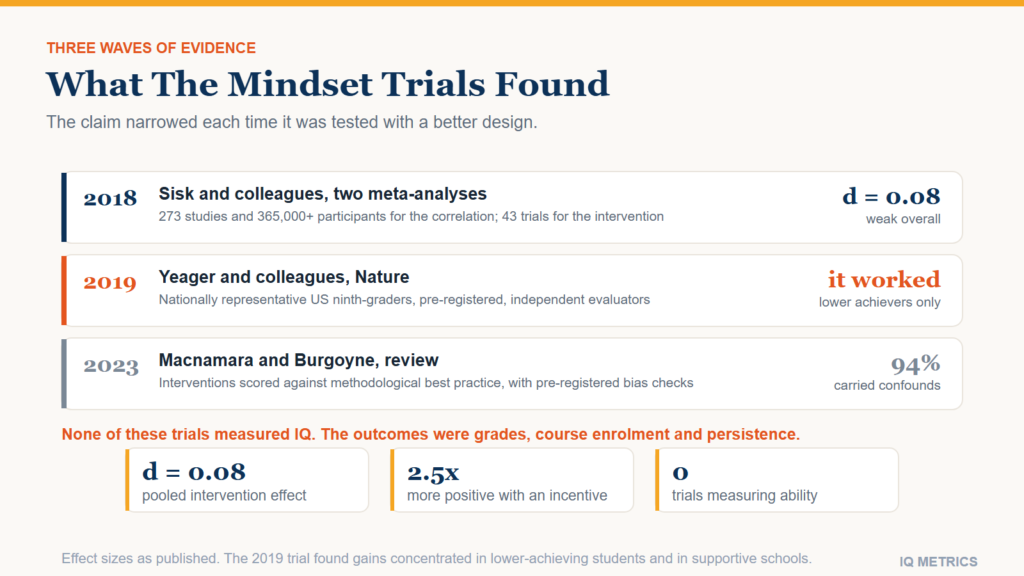
For anyone interpreting a real result, the practical upshot is that a score is a measurement taken under conditions, and the conditions are part of the reading. That is true of the test-day variables covered in the factors that affect a result and it is true over a lifetime of them. Whether beliefs about ability form another such condition is examined in the article on growth mindset.

If you want a benchmark for yourself rather than for a population, a properly normed test measures where you are now — which is the only thing any test has ever measured.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged adoption studies, child development, cognitive ability, education, environment and IQ, heritability, intelligence research, IQ and poverty, IQ Science, IQ score factors, nature versus nurture, Socioeconomic Status, socioeconomic status and IQ, twin studies

Fluid vs Crystallized Intelligence

Understanding IQ

Fluid vs Crystallized Intelligence: What Each One Measures

Fluid intelligence is what you use on a problem you have never seen before. Crystallized intelligence is everything you have already banked. The distinction has survived eighty years of factor analysis because the two halves genuinely behave differently, and the clearest proof is what happens to each one as you get older.
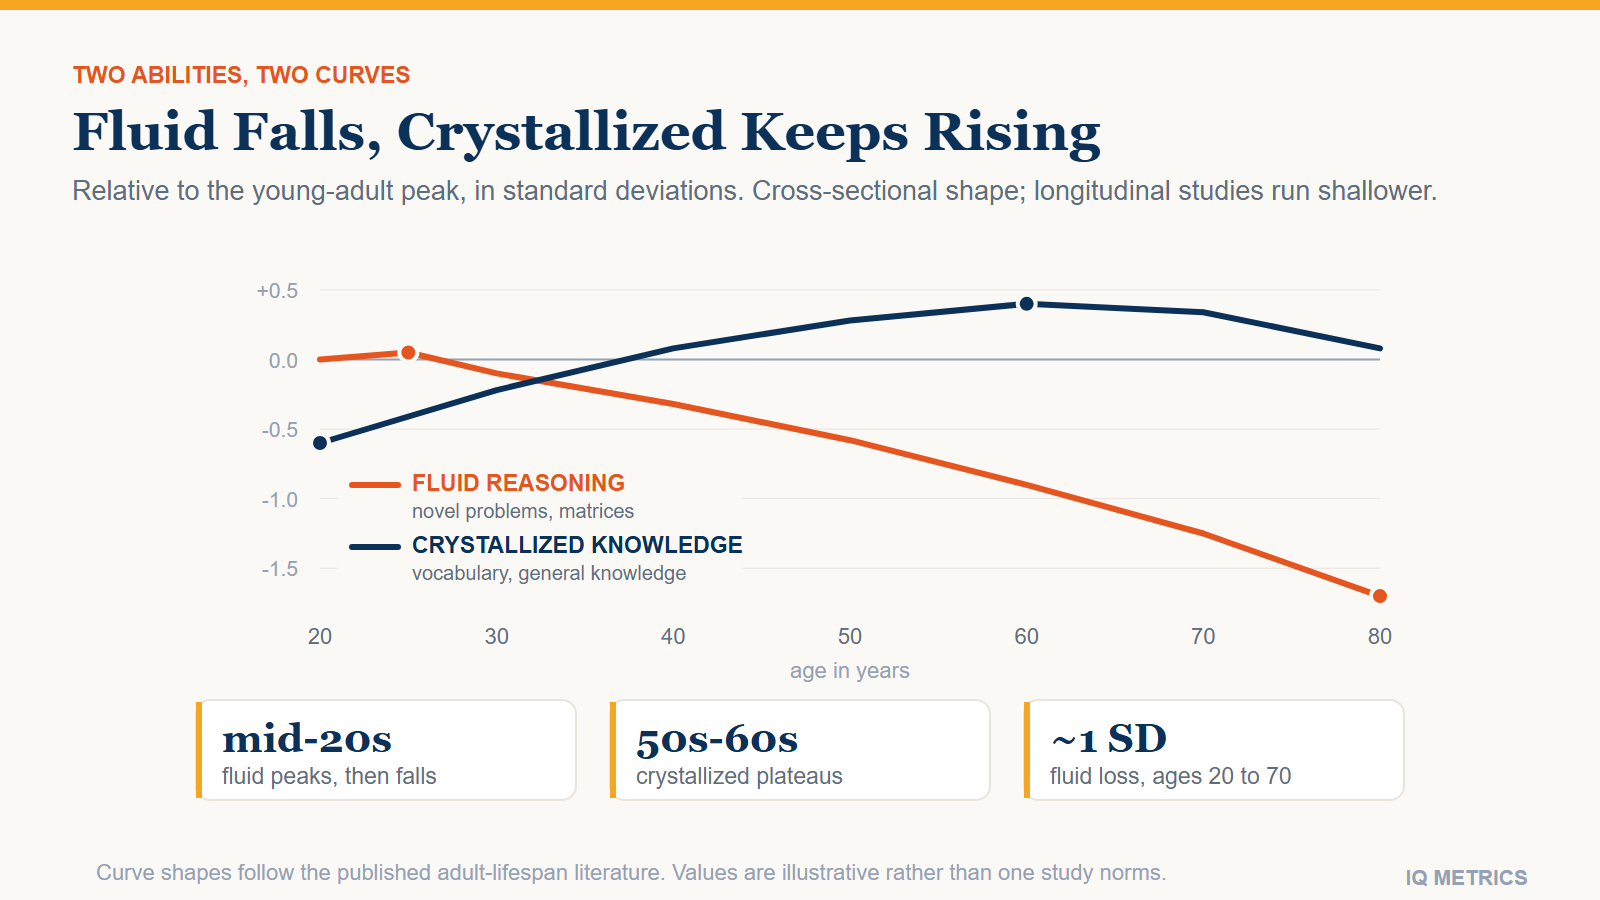
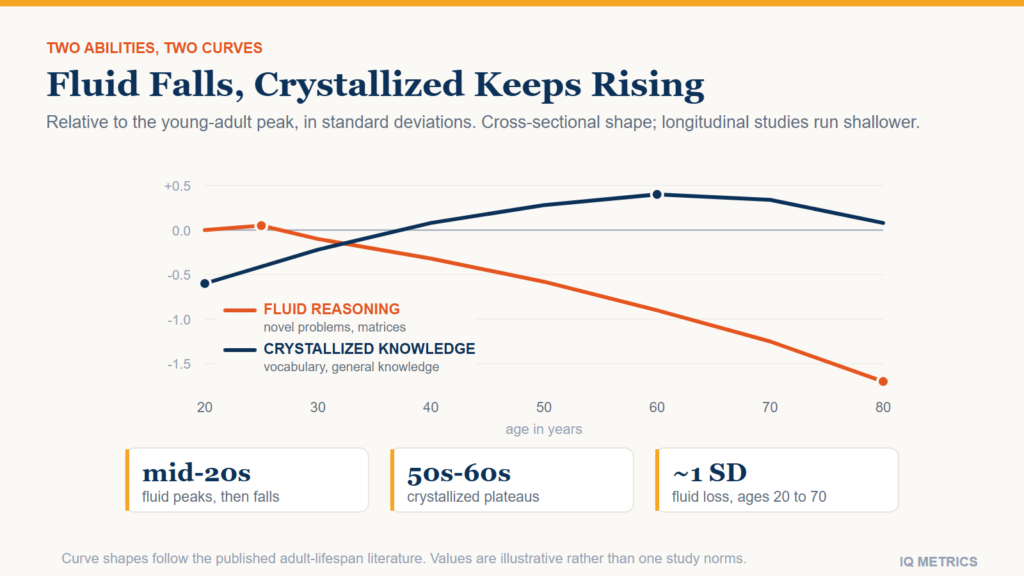
Chart of fluid and crystallized intelligence across the adult lifespan, showing fluid reasoning peaking in the mid-twenties and declining steadily while crystallized knowledge keeps rising into the sixties

Fluid intelligence is what you use on a problem you have never seen before — finding the rule in a matrix, holding several constraints in mind at once, working out a relationship nobody taught you. Crystallized intelligence is everything you have already banked: vocabulary, facts, procedures, the accumulated residue of what you have learned and can still retrieve. Raymond Cattell drew that line in the 1940s and it has outlasted most of its rivals, because the two halves are not just conceptually tidy. They load on different subtests, they respond differently to schooling, and across a lifetime they move in almost opposite directions.

That last point is the one worth staying for. Most explanations of this pair stop at the definitions. What follows is where the split actually shows up — on a real score report, in the age curves, and in which half your own test result is sampling.

What fluid intelligence measures

The defining feature of a fluid task is that prior knowledge does not help much. A matrix item shows you a grid with one cell missing and asks which option completes it; the rule might be rotation, addition of elements, or alternation, and it is different on the next item. Nothing you studied prepares you for the specific pattern. What carries you is the ability to generate candidate rules, test them against the evidence and discard the ones that fail, all while keeping the partial answer in working memory.

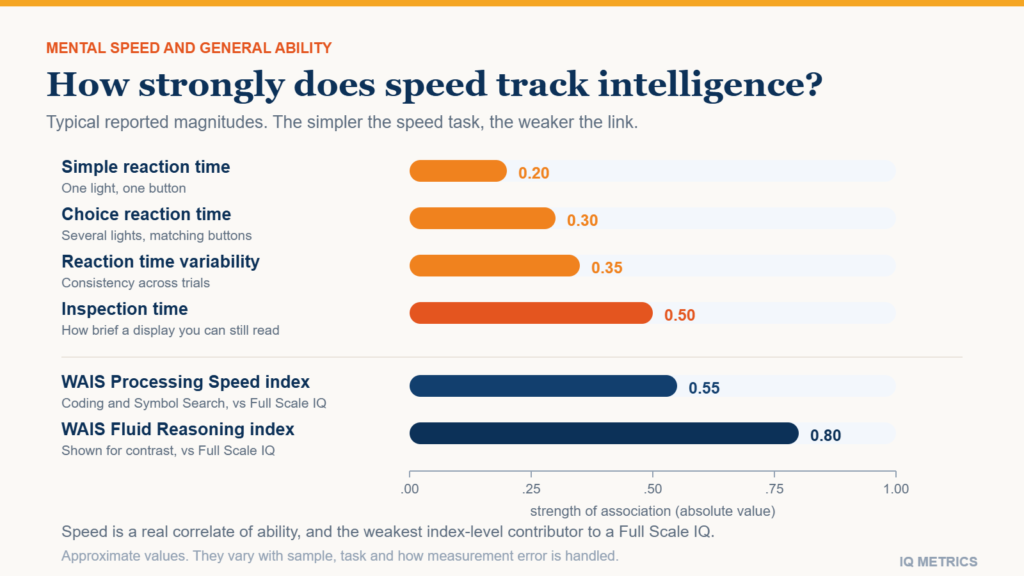
This is why Raven’s Progressive Matrices became the reference instrument for fluid ability, and why culture-fair tests are built almost entirely from figural material. Strip out the words and you strip out most of what a particular education gave you. Fluid tasks also lean heavily on how quickly you can manipulate information, which is why processing speed correlates with fluid scores far more than with verbal ones.

What crystallized intelligence measures

Crystallized ability is knowledge that has been organised well enough to be used. A vocabulary subtest is the classic measure, and it is a better one than it looks: knowing what “reticent” means is not a fact you were taught in a lesson, it is a trace of years of reading, inference and retention. General knowledge and verbal-similarities items work the same way. They ask what has stuck, not what you can work out now.

The common objection — that this is just measuring privilege or trivia — is half right and worth taking seriously. Crystallized scores are more sensitive to schooling and to language background than fluid ones, which is exactly what makes them useful for some purposes and a liability for others. That trade-off is the substance of the cultural bias argument, and it applies unevenly across the two halves rather than to “IQ tests” as a block.

Where the two split on a score report

On a professionally administered test the distinction is not theoretical, it is printed. The Wechsler Adult Intelligence Scale is the most widely used adult battery, and its fifth edition, published in 2024, made the split sharper than before by breaking the old Perceptual Reasoning Index into two: a Visual Spatial Index and a Fluid Reasoning Index. Alongside them sit Verbal Comprehension, Working Memory and Processing Speed.

  • Verbal Comprehension — vocabulary, similarities, general information. This is the crystallized index in all but name.
  • Fluid Reasoning — matrix reasoning and figure weights, plus quantitative and inductive items. Novel problems, minimal prior content.
  • Visual Spatial — block design and visual puzzles; spatial manipulation split out from reasoning proper.
  • Working Memory and Processing Speed — the machinery both halves run on, reported separately because they can fail independently.

A single full-scale number averages all of this into one figure, which is precisely what hides the interesting result. Someone can sit two standard deviations apart on Verbal Comprehension and Fluid Reasoning and still land near 100 overall. That is why clinicians read the index scores before the composite, and why a report that gives you only one number has thrown away most of what the testing session found. If you are looking at a report now, reading it index by index is the difference between a label and information.

Chart of fluid and crystallized intelligence across the adult lifespan, showing fluid reasoning peaking in the mid-twenties and declining steadily while crystallized knowledge keeps rising into the sixties
Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

The age curves are the strongest evidence

If fluid and crystallized ability were the same thing wearing two names, they would age the same way. They do not, and the gap is large. Fluid reasoning peaks in the mid-twenties and declines from there at roughly two-hundredths of a standard deviation per year, with the slope steepening after the mid-fifties. Between ages 20 and 70 that adds up to something between three-quarters of a standard deviation and a full one — eleven to fifteen points on the familiar scale.

Crystallized ability does the opposite. Vocabulary and general knowledge climb through middle age, plateau somewhere in the fifties and sixties, and hold up until quite late in life. This is the resolution of an old puzzle: people plainly get better at their work into their fifties while getting measurably slower at unfamiliar puzzles. Both things are true, of different abilities. The pattern is set out in more detail in the evidence on when intelligence peaks.

One honest caveat. Most of these curves come from cross-sectional data — different people of different ages measured at one time — and that design confounds ageing with generational differences in schooling and nutrition. Longitudinal studies that follow the same people tend to show the fluid decline starting later and running shallower. The direction of the two curves is not in dispute; the exact age at which the fluid one turns down is.

Investment theory: where crystallized ability comes from

Cattell did not propose two unrelated faculties. His investment theory says crystallized ability is what fluid ability turns into when it is spent on a culture: the child with more reasoning capacity extracts more from the same lesson, book or conversation, and that advantage accumulates as knowledge. It is a compounding account, and it explains two things a two-independent-abilities model cannot.

First, why the two correlate substantially rather than being independent — they share a cause and one feeds the other. Second, why they come apart with age exactly as they do: once the deposit is made, crystallized ability keeps paying out even as the fluid capacity that built it declines. It also predicts that an extra year of school should move crystallized scores more than fluid ones, which is roughly what the schooling evidence finds. Cattell’s pair was later folded into the broader Cattell-Horn-Carroll model that most modern batteries are built on, one of the theories that shaped IQ testing, and both sit underneath the general factor described in the account of g.

Which half is your online test measuring?

Almost always the fluid half, and mostly for practical reasons. Figural and matrix items can be generated in quantity, scored without judgment and used across languages, none of which is true of a vocabulary subtest that has to be normed against a specific population. So a short online reasoning test is sampling something real, but it is sampling one side of the pair. The distinction between the verbal and non-verbal halves of a score is the same split seen from the other direction.

The practical consequence: if your online result sits well below your sense of your own vocabulary and knowledge, that is not necessarily a contradiction, and neither number is lying. Full clinical batteries measure both because both are real. What those batteries look like is covered in the guide to professional IQ tests.

What this means for your own score

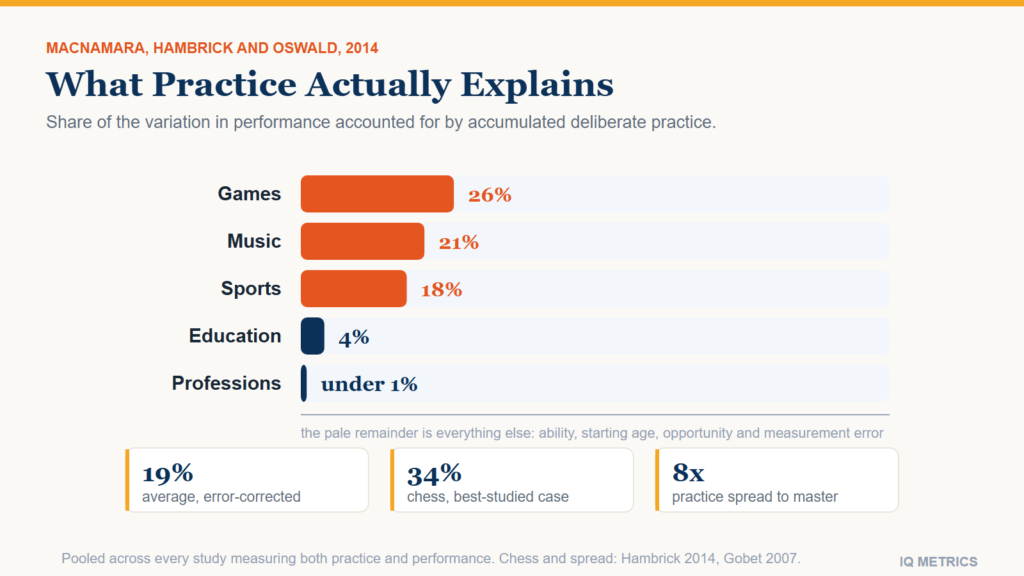
Three things follow. Ask which half a test sampled before treating the number as a summary of your intelligence. Expect the two to diverge with age, and read a mid-life score in that light rather than as decline across the board. And be sceptical of any claim to have raised “your IQ” that does not say which half moved: training reliably shifts crystallized measures, because that is what learning is, while moving fluid ability has proved far harder. How much of the outcome is fixed at all is the subject of the evidence on talent against practice, and how sharply both halves track family circumstances is covered in the article on socioeconomic status.

If you want to see where you sit on the fluid side specifically, a properly normed reasoning test will tell you more in half an hour than any amount of reading about the construct.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged Cattell, CHC theory, cognitive ability, crystallized intelligence, fluid intelligence, fluid reasoning, fluid vs crystallized intelligence, G Factor, general intelligence, Index Scores, intelligence research, IQ Science, matrix reasoning, verbal comprehension, wais

What Is AGI?

Understanding IQ

What Is AGI, and How Would Anyone Measure It?

Artificial general intelligence means a system that can learn and apply knowledge across the full range of tasks a person can, rather than excelling at a narrow set. The trouble is that the major labs each publish a different definition, none of them converts into a test, and so claims that AGI has arrived cannot be checked either way.

Chart comparing four published definitions of artificial general intelligence from OpenAI, Google, Microsoft and the ARC Prize Foundation, showing how little they overlap on what would count

AGI stands for artificial general intelligence: an AI system with the ability to learn, reason and apply knowledge across the full range of tasks a person can handle, rather than performing brilliantly in one narrow domain. That much is broadly agreed. Almost nothing after it is.

The organisations building these systems publish materially different definitions, none of those definitions specifies a test, and there is no reference population against which a result could be scored. So when a launch announcement is described as the arrival of AGI, there is no procedure available to check the claim. That is a measurement problem, and human intelligence testing solved a version of it a century ago.

Why nobody agrees on what AGI means

The published definitions differ on what would count, and the differences are not cosmetic.

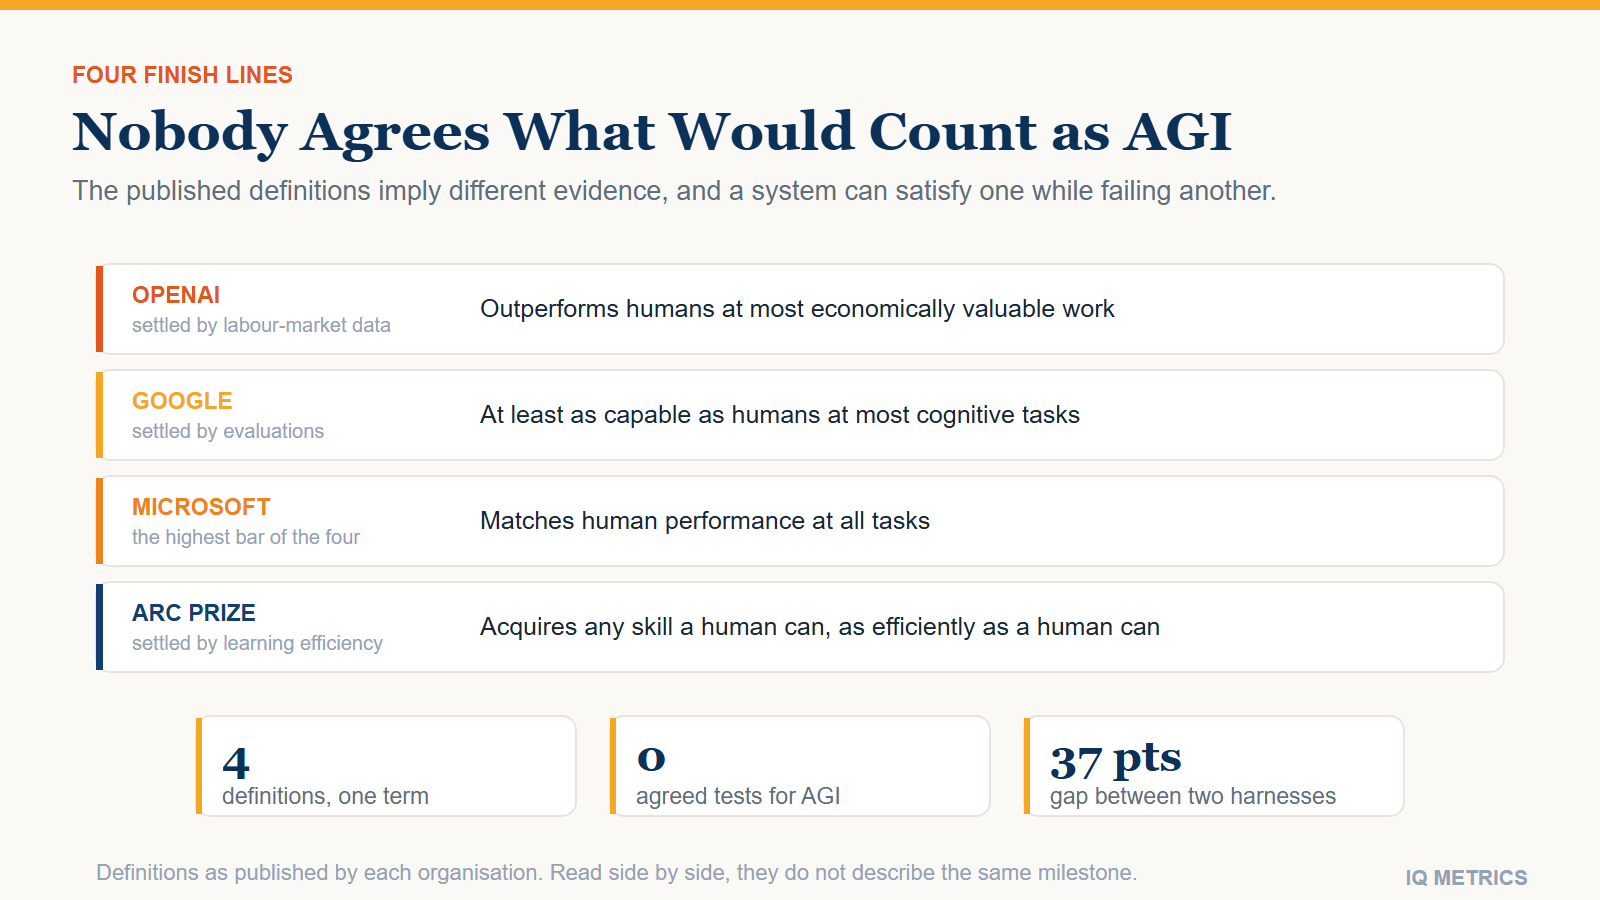
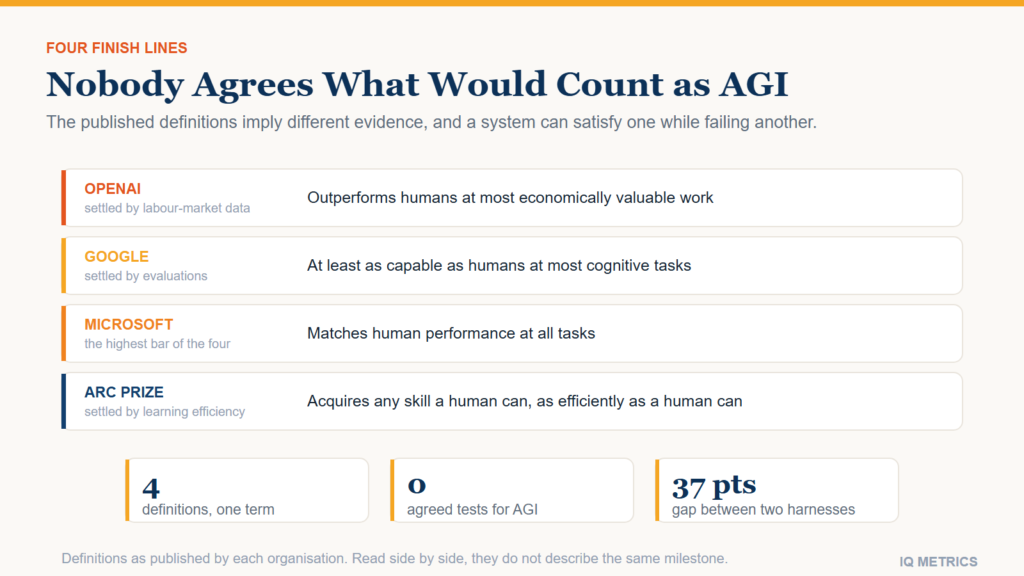
  • OpenAI: autonomous systems that outperform humans at most economically valuable work.
  • Google: AI that is at least as capable as humans at most cognitive tasks.
  • Microsoft: the point at which an AI can match human performance at all tasks.
  • ARC Prize Foundation: a system’s ability to acquire any skill a human can, as efficiently as a human can.

Read them side by side and the gaps open up. OpenAI’s is economic and could in principle be satisfied without the system ever learning anything new. Microsoft’s says all tasks, which is a far higher bar than most. The ARC Prize definition is the only one that puts learning efficiency at the centre, which is also the only version that resembles what psychologists mean by general ability.

The disagreement is not merely academic, because each definition implies a different finish line and a different set of evidence. An economic definition is settled by labour-market data. A cognitive-task definition is settled by evaluations. A learning-efficiency definition is settled by putting a system in front of something genuinely unfamiliar and counting how much evidence it needs. A system could satisfy one and fail another on the same day, which is roughly where things stand.

A term that means four things does not support a yes-or-no answer. It supports four of them.

What is the difference between AI, AGI and superintelligence?

The three terms describe a ladder, and most confusion comes from using them interchangeably.

  • Narrow AI is everything in use today: systems that perform specific tasks, sometimes far better than people, without the ability to transfer that competence to an unrelated problem. A model that writes excellent code and cannot fold a towel is narrow, however impressive the code.
  • AGI would match human ability across the full breadth of tasks rather than in a slice of them. Breadth is the operative word: the claim is about range, not peak performance.
  • Superintelligence would exceed human ability across that same full range. It is a claim about what comes after AGI, and is entirely hypothetical.

The distinction that matters for measurement is the first one. Narrow ability is straightforward to test, because you can specify the task. Breadth is not, because you would have to specify every task — which is the problem the next section is about.

How would anyone actually measure AGI?

The most serious attempt starts from a 2019 paper by François Chollet called "On the Measure of Intelligence", which argued that nearly every AI benchmark of the period measured skill at a task — and that skill at a task can simply be bought with enough data and training. What a benchmark should measure instead, on that argument, is how efficiently a system picks up a skill it was never trained on.

That produced the ARC-AGI series, built around puzzles with no vocabulary, no cultural reference and no arithmetic beyond counting, where every task has a different rule and nothing carries over. The distinction it targets is the one human testing already draws between fluid reasoning — working out something new — and crystallized ability, which is what you have accumulated. The general factor in human ability leans most heavily on the first.

Older proposals still get cited and are worth knowing. The Turing test asked whether a machine could be told apart from a person in conversation. Marvin Minsky suggested in 1970 that a machine should be able to read Shakespeare, grease a car, play office politics and tell a joke. The coffee test, associated with Steve Wozniak, proposes that AGI arrives when a machine can walk into an unfamiliar house and make a pot of coffee. Each captures something. None produces a score.

Chart comparing four published definitions of artificial general intelligence from OpenAI, Google, Microsoft and the ARC Prize Foundation, showing how little they overlap on what would count
Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

Did GPT-6 Astra just reach AGI?

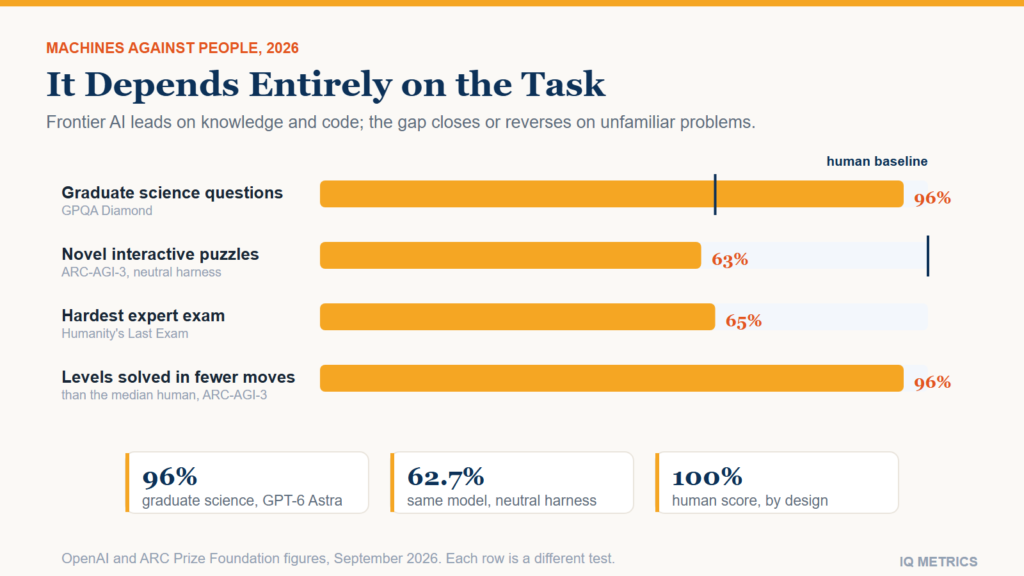
In September 2026 OpenAI announced GPT-6 Astra, and reported 99.9 percent on ARC-AGI-3 — the interactive benchmark built specifically to resist this kind of result. Coverage framed it as the arrival of the AGI era.

The organisation that owns the benchmark disagrees, in writing. The ARC Prize Foundation’s own analysis states plainly that while it believes the system represents meaningful progress towards generalisation, it is not claiming that it is AGI, and notes that it said at launch that saturating the benchmark would not represent proof of achieving AGI.

There is a measurement detail underneath that, and it is the part worth carrying away. The 99.9 percent came from a harness supplied by the model’s own developer, which preserves the system’s reasoning state between moves. On the ARC Prize Foundation’s neutral, provider-independent harness, the same model on the same benchmark scored 62.7 percent. Both numbers were published; only one of them travelled.

Two scores 37 points apart, differing only in how the test was administered, is a familiar problem to anyone who works with cognitive assessment. It is why standardised administration is part of the test rather than an afterthought, and it is a large part of why benchmark results move so fast.

What human intelligence testing already learned about this

The problem AGI research is running into now is the one that produced modern psychometrics. A raw count of correct answers tells you almost nothing on its own. To become a score it needs three things, and machine evaluation currently has none of them.

  • A defined population. A score is a position among some group. There is no population of machines and no obvious candidate for one.
  • A norming sample. The test administered under standard conditions to a representative sample, which is what converts a raw count into a scale position.
  • Standardised administration. Fixed conditions, so that two results mean the same thing. The 62.7 versus 99.9 split is exactly what its absence looks like.

Human testing has all three and is still careful: a well-reported score comes with a confidence interval, because measurement error is real and a single number overstates precision. That is the discipline behind reporting a score as a range, and it is conspicuously missing from benchmark figures quoted to one decimal place.

So how close are we?

Honestly: unanswerable as posed, and that is not evasion. Without an agreed definition and an agreed test, the distance to AGI has no units. What can be tracked is narrower and more useful — which specific abilities have fallen, which have not, and how quickly the boundary moves. On that basis the last two years have been remarkable and the remaining gaps are real, particularly around acting in the physical world and learning from very little evidence.

The claim to treat sceptically is not that progress is fast. It is that any single result settles the question. For where machines currently stand against people task by task, the domain-by-domain comparison is the companion to this article; for what happens to your own thinking as you use these systems, the evidence on cognitive debt is more concrete than any forecast. And if the underlying interest is in how general ability gets measured at all, sitting a properly normed reasoning test shows you what a century of solving this problem produced.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged AGI, AI and intelligence, AI benchmarks, artificial intelligence, crystallized intelligence, fluid reasoning, G Factor, general intelligence, intelligence research, intelligence test, measurement, test norms, turing test, what is agi

Does Using AI Make You Dumber?

Mind & Everyday Life

Does Using AI Make You Dumber? What the Studies Measured

The claim that AI is making us stupider has real research behind it and is still routinely overstated. No study has measured a drop in intelligence. What has been measured is lower mental engagement during a delegated task and weaker memory for work you did not do yourself, which is a narrower finding and a more useful one.

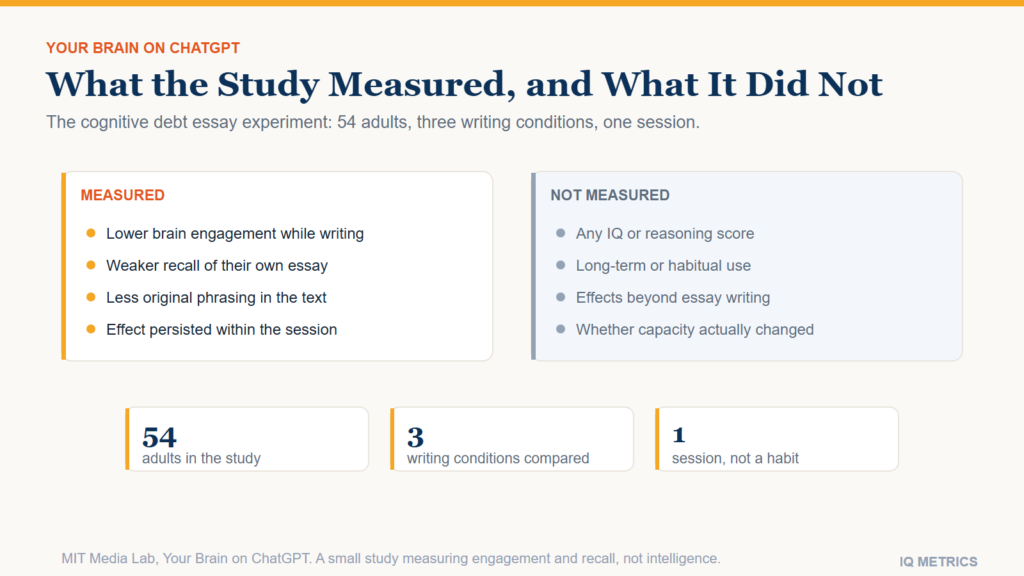
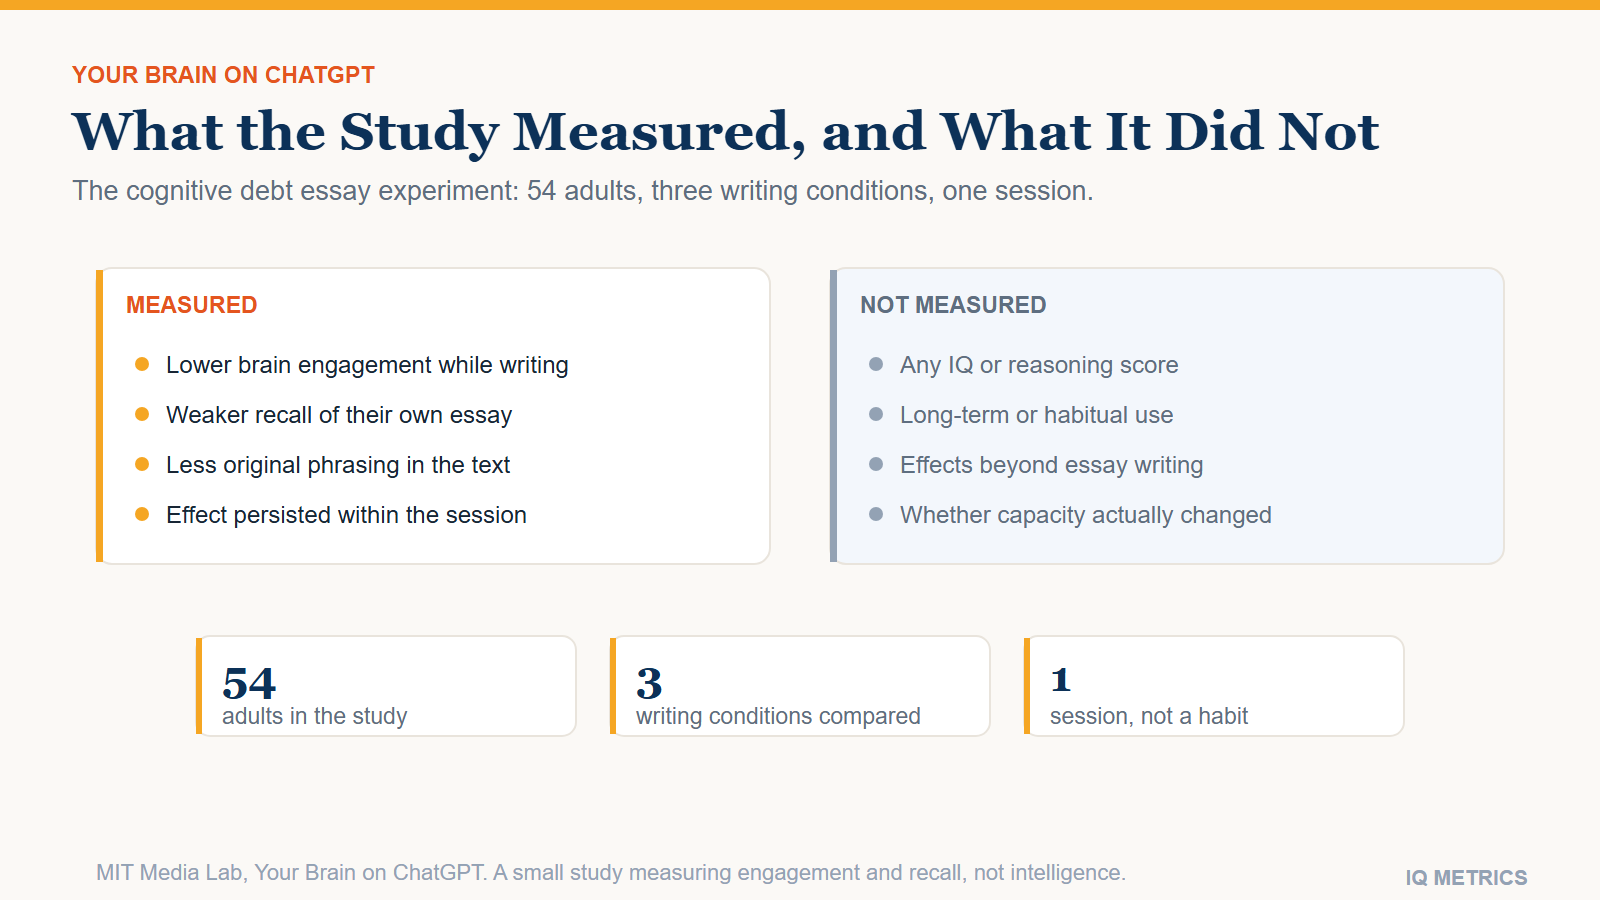
Chart of what the cognitive debt essay-writing study measured, showing lower brain engagement and weaker recall in the AI-assisted group, alongside the outcomes the study did not measure including IQ

Does using AI make you dumber? On the evidence available in 2026, no study has shown that AI use lowers intelligence, and none has measured an IQ score before and after. What researchers have measured is narrower and still worth taking seriously: people who delegate a thinking task to a language model engage less while doing it, remember less about it afterwards, and evaluate the output less critically the more they trust the tool.

Those are real findings about attention, memory and judgment. They are not findings about general intelligence, and the distance between the two is where most of the alarming coverage lives.

What the cognitive debt study actually measured

The study driving most of the headlines is work from the MIT Media Lab titled "Your Brain on ChatGPT: Accumulation of Cognitive Debt when Using an AI Assistant for Essay Writing Task". Fifty-four adults wrote essays under one of three conditions: with a language model, with a search engine, or with no tools at all. The researchers recorded brain electrical activity during the task and analysed the resulting text.

The model-assisted group showed measurably lower cognitive engagement while writing. They also showed weaker recall of their own essays afterwards — in several cases struggling to quote work they had submitted minutes earlier. The authors called the accumulated effect cognitive debt: a shortfall you take on by skipping the effortful part, which comes due later.

  • The finding is about engagement during the task and memory for the output.
  • It is not a finding about reasoning ability, problem solving, or any score on a cognitive test.
  • Nobody in the study was given an intelligence test at any point.

What the study did not show

Being clear about the limits is not a way of dismissing the work. It is how the work should be read, and the authors are considerably more careful than the coverage.

  • Fifty-four people is a small sample. Effects this size in samples this size routinely shrink when a study is repeated at scale.
  • One task, one session. Essay writing under observation over a short window is not the same as habitual use over years, which is what the headline claim implies.
  • Brain engagement is not intelligence. Lower measured activity during a task you delegated is close to what you would predict. It does not follow that capacity changed.
  • Cognitive debt is a metaphor, coined by the authors and not a validated psychological construct with an established measure behind it.

The correct summary is that a well-designed small study found lower engagement and weaker recall under AI assistance, and that this is a reason to pay attention rather than a demonstration that anyone got less intelligent. The site applies the same standard to claims that things raise intelligence, which usually turn out to be weaker than advertised in exactly the same way.

Chart of what the cognitive debt essay-writing study measured, showing lower brain engagement and weaker recall in the AI-assisted group, alongside the outcomes the study did not measure including IQ

The finding that should worry you more

A separate line of research points at something more specific than general dulling. A survey by researchers at Microsoft and Carnegie Mellon University found that the people who most trusted the accuracy of AI assistants thought least critically about what those assistants produced. Confidence in the tool, rather than time spent with it, predicted the drop in scrutiny.

Work tracking professional consultants found the same shape from the other direction: measurable short-term performance gains, reported in the range of 14 to 40 percent, alongside erosion of the independent judgment the assistance was supposed to support. The mechanism is not mysterious. Automation handles the routine cases and hands you the exceptions, which removes exactly the ordinary practice that keeps judgment sharp — so when the tool is wrong, the person checking it is out of practice.

Judgment behaves like a skill rather than a trait. It decays without use, and it does not show up on an intelligence test either way, which is part of why smart people can be reliably bad at particular kinds of decision. We look at that gap in why high scorers still make poor decisions.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

What would a study need to show to settle this?

It is worth being concrete about the gap between what exists and what would actually answer the question, because the gap is large and nothing currently published closes it.

  • A normed cognitive measure, before and after. Not brain activity during a task, but a standard instrument administered at the start and again at the end.
  • Random assignment and a real control group. People who choose to use AI heavily differ from people who do not, in ways that would produce this pattern on their own.
  • Months or years, not one session. The claim is about habitual use, so the study has to run long enough for a habit to exist.
  • A correction for practice effects. Sitting the same test twice raises the second score whatever happened in between, and that alone can manufacture or mask an effect.

No published study does all four. That is not a criticism of the researchers — a study like that is expensive and slow — but it does mean anyone claiming AI has measurably lowered human intelligence is going beyond the evidence. The same standard applies to the reverse claim: nobody has shown it is harmless either.

Does this apply to children and students?

The research discussed here was conducted on adults, and extending it to developing minds is exactly the kind of leap the evidence does not support. Children are not small adults for these purposes: the skills at issue are still being acquired rather than maintained, which could plausibly make delegation more costly or less, and neither has been demonstrated.

What is reasonably well established is narrower and older: learning that involves retrieval and effortful practice sticks better than learning that does not. A tool that removes the effort removes the thing that made it stick. That is an argument about how the tool is used in teaching, not about whether it lowers intelligence, and it long predates language models.

Is this the same as cognitive offloading?

Related but not identical, and the distinction is worth keeping. Cognitive offloading is the long-studied habit of storing information outside your head — a phone number in a contacts list, a route in a map app — and the research on what it does to memory predates language models by decades. We cover that literature separately in our report on AI and memory.

The cognitive debt work is about something narrower: not what happens to your memory when you store a fact elsewhere, but what happens to your engagement and recall when you delegate the thinking itself. Offloading a phone number costs you the number. Offloading the reasoning may cost you the practice.

How to use AI without losing the practice

Nothing in this research supports avoiding these tools, and the productivity findings are as real as the engagement ones. What the evidence does support is being deliberate about which part of the work you hand over.

  • Attempt first, then delegate. Producing your own answer before asking for one preserves the effortful step the studies found missing, and gives you something to compare against.
  • Use it to critique rather than to produce. Asking a model to find the weakness in your reasoning keeps you doing the reasoning.
  • Distrust fluent output on purpose. The Microsoft and Carnegie Mellon result says confidence in the tool is the risk factor, so the correction is to check most carefully when the answer reads best.
  • Keep some work unassisted. Not for virtue: for the same reason anyone practices anything they intend to stay good at.

If the underlying worry is about your own thinking rather than the technology, the useful move is to measure rather than speculate. A properly normed reasoning test gives you a baseline you can compare against later, reported as a position in a reference population rather than a bare number. And if the deeper question is whether machines are overtaking us, the domain-by-domain comparison is a better guide than any single study.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged AI and intelligence, artificial intelligence, brain health, chatgpt, cognitive debt, cognitive offloading, critical thinking, does ai make you dumber, IQ Science, learning, mental effort, sample size, study quality, Working Memory

What Is ChatGPT’s IQ Score?

Scores & Scales

ChatGPT IQ Score: Why the Numbers Disagree

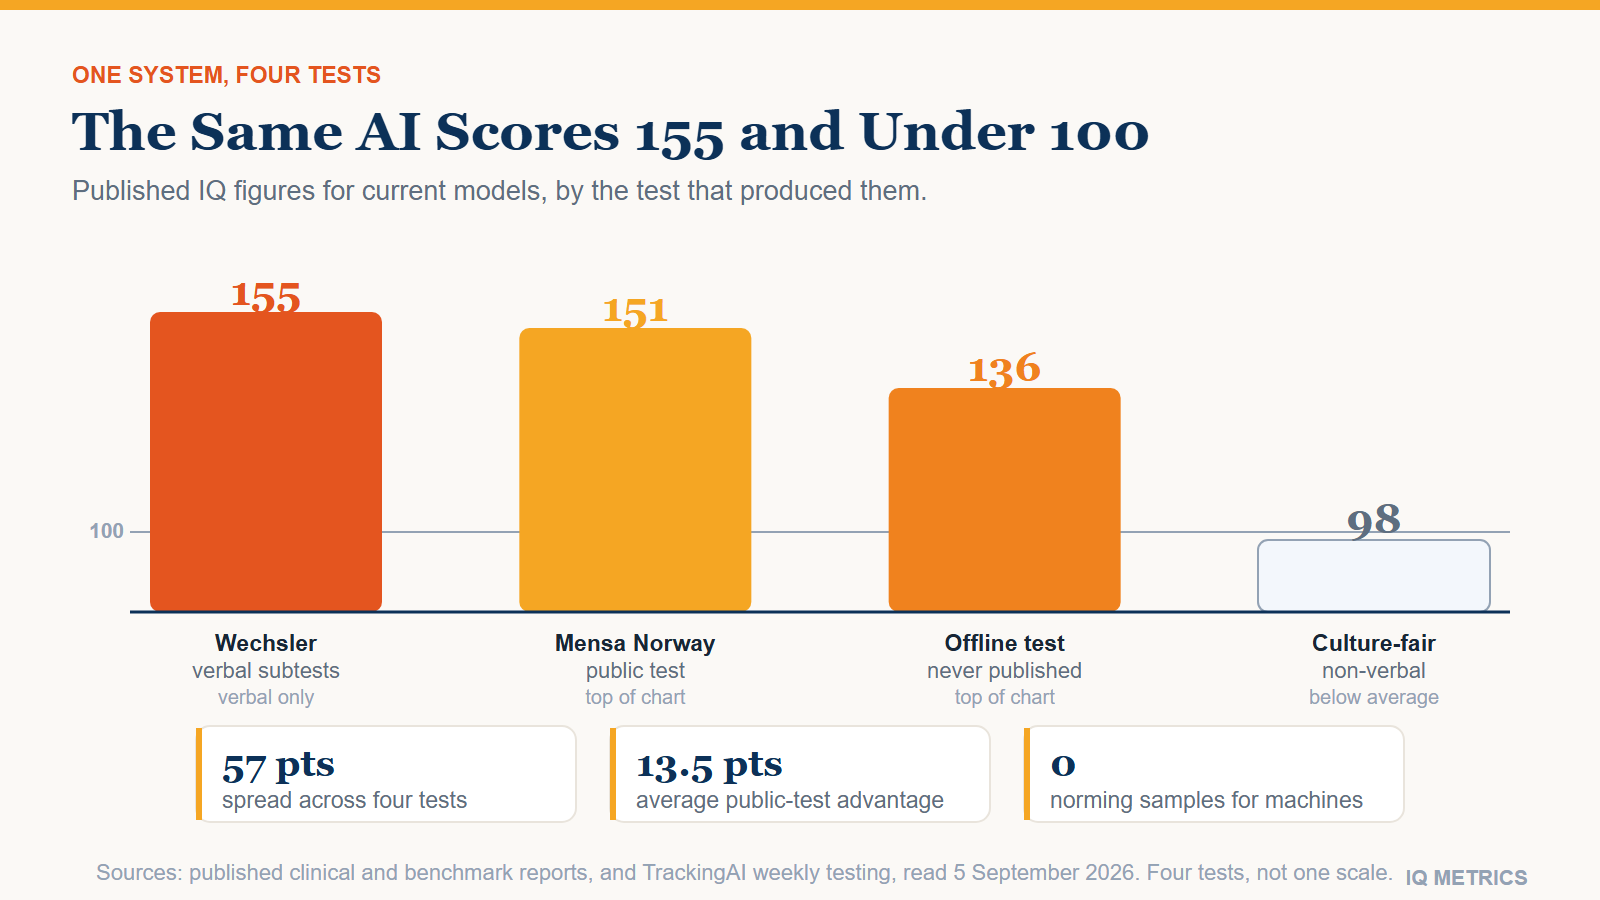
Search for ChatGPT’s IQ score and you will find 155, 136, 116 and under 100, all reported seriously, sometimes for the same model. They are not contradictions to be resolved. They are different tests, scored different ways, and the spread between them is the most informative thing about the whole exercise.

Chart of reported AI IQ figures from four different tests, ranging from below 100 on a culture-fair test to 155 on the verbal subtests of the Wechsler scale, showing how far the same systems spread across tests

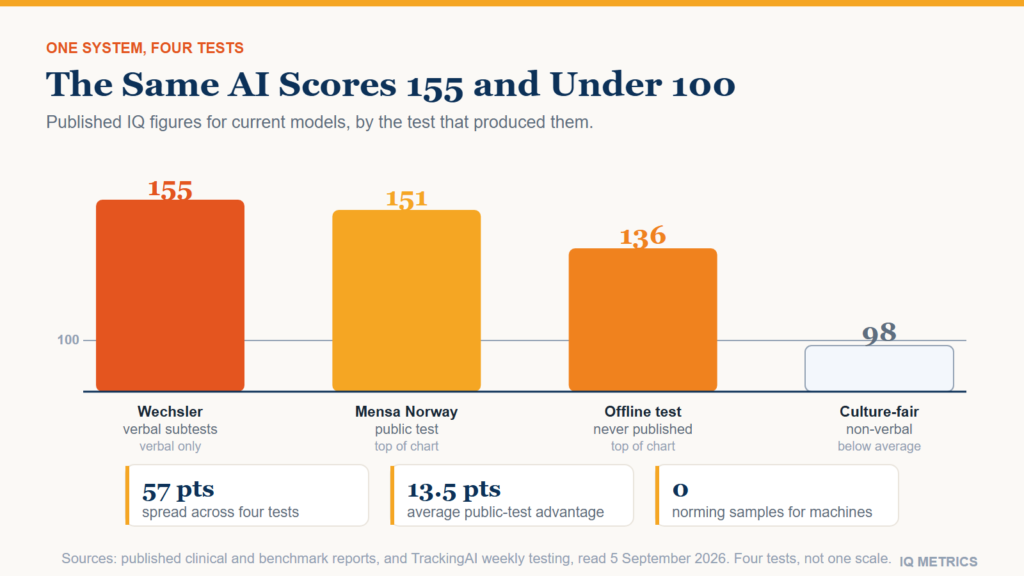
There is no single ChatGPT IQ score. Published figures for the same family of systems range from slightly below 100 on one culture-fair test to 155 on the verbal half of a clinical instrument, with 116 and 136 reported in between. Every one of those numbers was produced honestly. They disagree because they come from different tests, administered under different conditions, and because none of them is an IQ in the sense the word has when a psychologist uses it.

That spread is worth understanding, because the same forces distort the score a person gets from an online test.

What IQ scores has ChatGPT actually been given?

Four results account for most of what circulates, and they are not measuring comparable things.

  • 155 on the Wechsler verbal subtests. A clinical psychologist administered parts of the Wechsler Adult Intelligence Scale and reported a verbal IQ of 155, above 99.9 percent of the American standardisation sample. Only the verbal subtests could be given: the performance subtests need eyes, ears and hands.
  • Under 100 on a culture-fair test. On the Worldwide IQ Test, a non-verbal assessment designed to minimise language and cultural loading, GPT-4o scored slightly below the population average of 100.
  • 116 and 136 on two other tests. OpenAI’s o3 model was reported at 116 on one assessment and at 136 on the public Mensa Norway test, which would place it above roughly 98 percent of people if it were a person.
  • Up to 151 on tracked weekly testing. The TrackingAI project has been administering the Mensa Norway test to frontier models every week; by September 2026 the top of that chart had reached 151.

A system cannot be simultaneously in the top 0.1 percent and below average. What varies is the test.

Why does the same system score 155 and under 100?

The Wechsler verbal subtests reward stored knowledge: vocabulary, general information, verbal similarities. That is the closest thing to a language model’s home ground, and the result reflects it. The culture-fair test does the opposite. It strips out language and prior knowledge deliberately and asks for pattern completion on abstract figures, which is precisely the ability these systems have found hardest.

In a person, this rarely happens, because human abilities correlate: someone with a top-percentile vocabulary usually does well on matrices too. In a machine there is no such tie between the two, so the choice of test decides the answer. The same principle explains why verbal and non-verbal index scores can diverge sharply in a human profile too, and why a single full-scale number can hide it.

Chart of reported AI IQ figures from four different tests, ranging from below 100 on a culture-fair test to 155 on the verbal subtests of the Wechsler scale, showing how far the same systems spread across tests

How do you even give an IQ test to a chatbot?

Less straightforwardly than the headline numbers suggest, and the administration details do a lot of work. The Mensa Norway test behind most published AI figures is a set of 35 visual-pattern puzzles. A model that cannot see is given those puzzles described in words; a model that can see is given the original images. TrackingAI runs both variants weekly and reports the average of the last seven administrations rather than a single sitting.

That produces something genuinely instructive. The same underlying system often appears twice on the chart, once reading a description and once looking at the picture, and the two scores are not the same. One model scored 133 when the puzzles were described to it and 136 when it could see them. Another scored 113 reading and 108 looking. The direction is not even consistent.

  • The format of administration moved the score by several points without anything about the system changing.
  • Averaging seven sittings hides how much any single sitting varies, which for a person is exactly what a confidence interval is for.
  • A test built to be visual becomes a different test when it is read aloud, in the same way a timed test becomes a different test when the clock is removed.

Human testing treats this as fundamental rather than incidental. Standardised administration — same instructions, same time limit, same materials — is part of the instrument, because two scores only mean the same thing if they were produced the same way. Almost none of the AI figures in circulation were.

Your own number

Where would your own score land?

Take the IIF-certified assessment and get your score with the scale it was measured on, the percentile it corresponds to and the confidence range around it — the three figures most online tests leave out.

Find your IQ score now!

Secure & encryptedInstant results10–20 minutes

What happens when the test has never been published?

This is the most revealing comparison available, and it comes from the same project that produces the headline numbers. TrackingAI runs two tests on every model it follows. One is Mensa Norway, a public online test that has been on the internet for years and is therefore in the training data. The other is an offline test written by a Mensa member that, in the project’s own words, has never been on the public internet and is in no AI training data.

Reading the underlying chart data on 5 September 2026, 27 models carried a score on both tests. Across those 27, scores on the public test averaged about 13.5 points higher than scores on the unpublished one — close to a full standard deviation on the usual IQ scale. The public test topped out at 151; the unpublished test at 136.

  • One widely used model scored 137 on the public test and 113 on the unpublished one, a 24-point gap.
  • Another scored 145 publicly and 127 privately.
  • A third scored 108 publicly and 88 privately.
  • A small number moved the other way, which is a useful reminder that this is a pattern rather than a law.

An honest caveat belongs here, because it is the kind this site insists on. Two different tests are not directly comparable: they have different norming samples, different difficulty and different item formats, and the unpublished test’s construction has not been released. The gap is consistent with the public test having leaked into the training data, but it does not prove it on its own. What can be said plainly is that models score substantially higher on the test they have almost certainly seen.

The human parallel is exact, and it is the reason serious tests are kept out of circulation. Someone who has worked through a test before scores higher on it the second time without having become any smarter. That is the practice effect, and it is a measured, predictable thing rather than a suspicion.

Is an AI IQ score a real IQ?

No. An IQ is not a mark out of anything. It is a position within a reference population, expressed on a scale with a stated mean — almost always 100 — and a stated standard deviation, usually 15. Producing one requires a norming study in which the test is given to a representative sample of that population under standard conditions.

For a machine, there is no population to be a member of and no norming sample, so the final step simply cannot be taken. What a model produces on an IQ test is a count of correct answers. Calling that count an IQ borrows the authority of a scale it was never placed on. We make the full argument in our piece on why a model scoring 120 is not scoring an IQ.

There is a second problem specific to machines. Standard administration assumes a fixed time, no external help and no second attempt. A model may be run at different effort settings, with or without tools, once or many times, and the reported figure is usually the best of those runs. A human score reported that way would not be accepted either.

What this means for your own score

The lesson transfers directly. A number without a stated scale and a stated reference group is not a result, whoever produced it. When you take a test online, the questions that matter are which population your score is being compared against, what the scale’s standard deviation is, and how much measurement error sits around the figure — a point we cover in the explainer on why a score is a range, not a number.

It also means treating a score you got on a test you had already seen with the same scepticism you would apply to a model’s 151. If you want a number that means something, take a properly normed reasoning test once, cold, and read the result as a range rather than a point. For what the resulting figure does and does not tell you, how to read a test report is the place to start, and the wider human-versus-machine comparison puts the AI numbers in context.

Share this article

Know someone who keeps seeing these numbers quoted without the scale they were measured on? Send it to them.

Tagged AI and intelligence, AI benchmarks, artificial intelligence, chatgpt, chatgpt iq score, Culture Fair Test, intelligence test, iq scale, IQ Score, mensa, norming sample, standard deviation, test norms, wais